Compare commits
57
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 nate@necloud.us |
3a7dfd5aff | ||
|
nate@necloud.us
|
aa45e9c873 | ||
|
nate@necloud.us
|
5f7cef7646 | ||
|
nate@necloud.us
|
fdda517e7b | ||
|
nate@necloud.us
|
545cf4c8dc | ||
|
nate@necloud.us
|
7d8470df84 | ||
|
nate@necloud.us
|
27af564a41 | ||
|
nate@necloud.us
|
5644f564eb | ||
|
nate@necloud.us
|
68e3365a5e | ||
|
nate@necloud.us
|
d652248170 | ||
|
nate@necloud.us
|
6d2987485d | ||
|
nate@necloud.us
|
968322401c | ||
|
nate@necloud.us
|
f294175a4b | ||
|
nate@necloud.us
|
d6f5a70e52 | ||
|
nate@necloud.us
|
8e2f6dac0c | ||
 nmemmert |
fb879b1a23 | ||
|
nmemmert
|
b40e5136a1 | ||
|
nate@necloud.us
|
d955f55020 | ||
|
nmemmert
|
75eaf88d9d | ||
|
nate@necloud.us
|
6bbf0afbab | ||
|
nmemmert
|
e0badaf366 | ||
|
nate@necloud.us
|
40e25334fd | ||
|
nate@necloud.us
|
474235f94d | ||
|
nate@necloud.us
|
6029d6f244 | ||
|
nate@necloud.us
|
5ac5626406 | ||
|
nate@necloud.us
|
266a064330 | ||
|
nate@necloud.us
|
462c7908a1 | ||
|
nate@necloud.us
|
364284553b | ||
|
nate@necloud.us
|
edee33416f | ||
|
nate@necloud.us
|
82bbaa0e83 | ||
|
nate@necloud.us
|
d0e72d0bfe | ||
|
nate@necloud.us
|
c00d10c8f4 | ||
|
nate@necloud.us
|
81942e7e61 | ||
|
nmemmert
|
14ae64707e | ||
|
nate@necloud.us
|
5d1dc3a203 | ||
|
nmemmert
|
e7b6e9288a | ||
|
nate@necloud.us
|
6c77a8f407 | ||
|
nmemmert
|
c4844eecff | ||
|
nate@necloud.us
|
1aa71df735 | ||
|
nate@necloud.us
|
77d5f9b196 | ||
|
nate@necloud.us
|
ed1cafe761 | ||
|
nate@necloud.us
|
3b9a49decb | ||
|
nate@necloud.us
|
3e6c02e4d2 | ||
|
nate@necloud.us
|
49e2d58fae | ||
|
nate@necloud.us
|
bab84747b6 | ||
|
nate@necloud.us
|
99dde19847 | ||
|
nate@necloud.us
|
1f0d0ed782 | ||
|
nate@necloud.us
|
5def68e13d | ||
|
nate@necloud.us
|
f6974b62c7 | ||
|
nate@necloud.us
|
2433cfb0af | ||
|
nate@necloud.us
|
e2b2a39837 | ||
|
nate@necloud.us
|
61a31db273 | ||
|
nate@necloud.us
|
fb4688f652 | ||
|
nate@necloud.us
|
7567fb8144 | ||
|
nate@necloud.us
|
a3d3ab8c46 | ||
|
nmemmert
|
1f3b27516f | ||
|
nmemmert
|
6d99b46553 |
No files matched your search
+43
-6
@@ -1,7 +1,44 @@
|
|||||||
|
# Version control
|
||||||
|
.git
|
||||||
|
.gitignore
|
||||||
|
.github
|
||||||
|
|
||||||
|
# Node.js
|
||||||
node_modules
|
node_modules
|
||||||
data
|
npm-debug.log
|
||||||
tts-cache
|
yarn-debug.log
|
||||||
.env
|
yarn-error.log
|
||||||
*.db
|
|
||||||
*.db-shm
|
# Development files
|
||||||
*.db-wal
|
*.md
|
||||||
|
!README.md
|
||||||
|
!CHANGELOG.md
|
||||||
|
*.log
|
||||||
|
*.bak
|
||||||
|
.DS_Store
|
||||||
|
.vscode
|
||||||
|
.idea
|
||||||
|
.editorconfig
|
||||||
|
.eslintrc
|
||||||
|
.prettierrc
|
||||||
|
|
||||||
|
# Test files
|
||||||
|
test
|
||||||
|
__tests__
|
||||||
|
coverage
|
||||||
|
|
||||||
|
# Docker
|
||||||
|
Dockerfile
|
||||||
|
docker-compose.yml
|
||||||
|
.dockerignore
|
||||||
|
|
||||||
|
# Local data (should be mounted as volume)
|
||||||
|
data/*
|
||||||
|
!data/.gitkeep
|
||||||
|
|
||||||
|
# Debug scripts
|
||||||
|
debug-*.js
|
||||||
|
test-*.js
|
||||||
|
|
||||||
|
# Documentation
|
||||||
|
docs
|
||||||
@@ -1,28 +0,0 @@
|
|||||||
name: Build and Push Docker Image
|
|
||||||
|
|
||||||
on:
|
|
||||||
push:
|
|
||||||
branches:
|
|
||||||
- main
|
|
||||||
|
|
||||||
jobs:
|
|
||||||
build-and-push:
|
|
||||||
runs-on: ubuntu-latest
|
|
||||||
|
|
||||||
steps:
|
|
||||||
- name: Checkout
|
|
||||||
uses: actions/checkout@v4
|
|
||||||
|
|
||||||
- name: Log in to Gitea Container Registry
|
|
||||||
uses: docker/login-action@v3
|
|
||||||
with:
|
|
||||||
registry: git.necloud.us
|
|
||||||
username: ${{ secrets.REGISTRY_USER }}
|
|
||||||
password: ${{ secrets.REGISTRY_TOKEN }}
|
|
||||||
|
|
||||||
- name: Build and push
|
|
||||||
uses: docker/build-push-action@v6
|
|
||||||
with:
|
|
||||||
context: .
|
|
||||||
push: true
|
|
||||||
tags: git.necloud.us/nate/homeschool:latest
|
|
||||||
@@ -0,0 +1,42 @@
|
|||||||
|
name: Docker Build and Push
|
||||||
|
|
||||||
|
on:
|
||||||
|
push:
|
||||||
|
tags:
|
||||||
|
- 'v*.*.*'
|
||||||
|
|
||||||
|
jobs:
|
||||||
|
build-and-push:
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
permissions:
|
||||||
|
contents: read
|
||||||
|
packages: write
|
||||||
|
|
||||||
|
steps:
|
||||||
|
- name: Checkout code
|
||||||
|
uses: actions/checkout@v3
|
||||||
|
|
||||||
|
- name: Set up Docker Buildx
|
||||||
|
uses: docker/setup-buildx-action@v2
|
||||||
|
|
||||||
|
- name: Extract version from tag
|
||||||
|
id: get_version
|
||||||
|
run: echo "VERSION=${GITHUB_REF#refs/tags/v}" >> $GITHUB_OUTPUT
|
||||||
|
|
||||||
|
- name: Login to GitHub Container Registry
|
||||||
|
uses: docker/login-action@v2
|
||||||
|
with:
|
||||||
|
registry: ghcr.io
|
||||||
|
username: ${{ github.actor }}
|
||||||
|
password: ${{ secrets.GITHUB_TOKEN }}
|
||||||
|
|
||||||
|
- name: Build and push
|
||||||
|
uses: docker/build-push-action@v4
|
||||||
|
with:
|
||||||
|
context: .
|
||||||
|
push: true
|
||||||
|
tags: |
|
||||||
|
ghcr.io/${{ github.repository }}:latest
|
||||||
|
ghcr.io/${{ github.repository }}:${{ steps.get_version.outputs.VERSION }}
|
||||||
|
cache-from: type=gha
|
||||||
|
cache-to: type=gha,mode=max
|
||||||
@@ -0,0 +1,55 @@
|
|||||||
|
name: Build and Push Docker Image
|
||||||
|
|
||||||
|
on:
|
||||||
|
push:
|
||||||
|
branches: [ main ]
|
||||||
|
tags: [ 'v*' ]
|
||||||
|
pull_request:
|
||||||
|
branches: [ main ]
|
||||||
|
|
||||||
|
env:
|
||||||
|
REGISTRY: ghcr.io
|
||||||
|
IMAGE_NAME: nmemmert/spelling
|
||||||
|
|
||||||
|
jobs:
|
||||||
|
build-and-push:
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
permissions:
|
||||||
|
contents: read
|
||||||
|
packages: write
|
||||||
|
|
||||||
|
steps:
|
||||||
|
- name: Checkout repository
|
||||||
|
uses: actions/checkout@v3
|
||||||
|
|
||||||
|
- name: Set up Docker Buildx
|
||||||
|
uses: docker/setup-buildx-action@v2
|
||||||
|
|
||||||
|
- name: Log in to the Container registry
|
||||||
|
uses: docker/login-action@v2
|
||||||
|
with:
|
||||||
|
registry: ${{ env.REGISTRY }}
|
||||||
|
username: ${{ github.actor }}
|
||||||
|
password: ${{ secrets.GITHUB_TOKEN }}
|
||||||
|
|
||||||
|
- name: Extract metadata (tags, labels) for Docker
|
||||||
|
id: meta
|
||||||
|
uses: docker/metadata-action@v4
|
||||||
|
with:
|
||||||
|
images: ${{ env.REGISTRY }}/${{ env.IMAGE_NAME }}
|
||||||
|
tags: |
|
||||||
|
type=semver,pattern={{version}}
|
||||||
|
type=semver,pattern={{major}}.{{minor}}
|
||||||
|
type=ref,event=branch
|
||||||
|
type=sha,format=long
|
||||||
|
latest
|
||||||
|
|
||||||
|
- name: Build and push Docker image
|
||||||
|
uses: docker/build-push-action@v4
|
||||||
|
with:
|
||||||
|
context: .
|
||||||
|
push: ${{ github.event_name != 'pull_request' }}
|
||||||
|
tags: ${{ steps.meta.outputs.tags }}
|
||||||
|
labels: ${{ steps.meta.outputs.labels }}
|
||||||
|
cache-from: type=gha
|
||||||
|
cache-to: type=gha,mode=max
|
||||||
-30
@@ -1,30 +0,0 @@
|
|||||||
# Dependencies
|
|
||||||
node_modules/
|
|
||||||
npm-debug.log*
|
|
||||||
|
|
||||||
# App data (SQLite database)
|
|
||||||
data/
|
|
||||||
|
|
||||||
# OS generated files
|
|
||||||
.DS_Store
|
|
||||||
.DS_Store?
|
|
||||||
._*
|
|
||||||
.Spotlight-V100
|
|
||||||
.Trashes
|
|
||||||
Thumbs.db
|
|
||||||
|
|
||||||
# IDE files
|
|
||||||
.vscode/
|
|
||||||
.idea/
|
|
||||||
*.swp
|
|
||||||
*.swo
|
|
||||||
*~
|
|
||||||
|
|
||||||
# Backup files
|
|
||||||
*.bak
|
|
||||||
*.tmp
|
|
||||||
*.backup
|
|
||||||
|
|
||||||
# Environment variables
|
|
||||||
.env
|
|
||||||
.env.local
|
|
||||||
Vendored
+13
@@ -0,0 +1,13 @@
|
|||||||
|
{
|
||||||
|
"version": "2.0.0",
|
||||||
|
"tasks": [
|
||||||
|
{
|
||||||
|
"type": "shell",
|
||||||
|
"label": "Run Spelling Practice App",
|
||||||
|
"command": "node server.js",
|
||||||
|
"group": "build",
|
||||||
|
"isBackground": true,
|
||||||
|
"problemMatcher": []
|
||||||
|
}
|
||||||
|
]
|
||||||
|
}
|
||||||
@@ -0,0 +1,35 @@
|
|||||||
|
# Changelog
|
||||||
|
|
||||||
|
All notable changes to the Spelling Practice App will be documented in this file.
|
||||||
|
|
||||||
|
## [1.1.0] - 2025-08-13
|
||||||
|
|
||||||
|
### Fixed
|
||||||
|
- Analytics graph no longer goes off the page (added SVG clipping paths)
|
||||||
|
- Results and Sessions tabs now show correct data for all users
|
||||||
|
- Admin1 sessions now visible in the interface
|
||||||
|
- Fixed issues with reading results.json file
|
||||||
|
|
||||||
|
### Added
|
||||||
|
- API Test Page for endpoint testing and debugging
|
||||||
|
- Support for different session data formats
|
||||||
|
- Filtering and pagination to the /getResults endpoint
|
||||||
|
- Comprehensive error handling for file operations
|
||||||
|
- Test script to verify data storage functionality
|
||||||
|
- DEBUG.md with troubleshooting instructions
|
||||||
|
|
||||||
|
### Changed
|
||||||
|
- Improved session data handling with better format compatibility
|
||||||
|
- Enhanced error logging with emoji indicators for better readability
|
||||||
|
- Simplified file reading operations with proper error handling
|
||||||
|
- Updated saveResults endpoint to handle edge cases better
|
||||||
|
|
||||||
|
## [1.0.0] - 2024-10-15
|
||||||
|
|
||||||
|
### Initial Release
|
||||||
|
- Spelling practice functionality
|
||||||
|
- User management
|
||||||
|
- Admin panel
|
||||||
|
- Analytics
|
||||||
|
- Gamification features
|
||||||
|
- Spaced repetition system
|
||||||
@@ -0,0 +1,84 @@
|
|||||||
|
# Debugging the Spelling Practice App
|
||||||
|
|
||||||
|
This document provides guidance on debugging and testing the app's data handling functionality.
|
||||||
|
|
||||||
|
## Testing Tools
|
||||||
|
|
||||||
|
### 1. API Test Page
|
||||||
|
|
||||||
|
A user-friendly interface for testing the API endpoints:
|
||||||
|
|
||||||
|
- **URL**: http://localhost:3000/api-test.html
|
||||||
|
- **Features**:
|
||||||
|
- Test the `/getResults` endpoint to retrieve session data
|
||||||
|
- Create and save new test sessions with customizable parameters
|
||||||
|
- View session details for specific users
|
||||||
|
|
||||||
|
### 2. Test Script
|
||||||
|
|
||||||
|
A Node.js script to verify the saveResults endpoint functionality:
|
||||||
|
|
||||||
|
```bash
|
||||||
|
node test-save-results.js
|
||||||
|
```
|
||||||
|
|
||||||
|
This script:
|
||||||
|
1. Verifies the server is running
|
||||||
|
2. Creates a test session for "testuser"
|
||||||
|
3. Validates the session was saved correctly
|
||||||
|
4. Shows summary information about the saved session
|
||||||
|
|
||||||
|
## Common Issues
|
||||||
|
|
||||||
|
### File Access Issues
|
||||||
|
|
||||||
|
If you're experiencing issues with data storage or retrieval:
|
||||||
|
|
||||||
|
1. **Check file permissions**:
|
||||||
|
- Make sure the `data` directory is writable by the Node.js process
|
||||||
|
- In Docker environments, ensure volume mounts are set up correctly
|
||||||
|
|
||||||
|
2. **Verify file formats**:
|
||||||
|
- The app expects JSON files in a specific format
|
||||||
|
- If manually editing files, validate the JSON structure before restarting
|
||||||
|
|
||||||
|
3. **Inspect server logs**:
|
||||||
|
- The server outputs detailed logs with emoji indicators
|
||||||
|
- Look for error messages marked with ❌
|
||||||
|
|
||||||
|
### Session Data Troubleshooting
|
||||||
|
|
||||||
|
If sessions aren't appearing correctly:
|
||||||
|
|
||||||
|
1. **Format compatibility**:
|
||||||
|
- The app supports multiple data formats for backward compatibility
|
||||||
|
- Session data may use either `timestamp` or `date` fields
|
||||||
|
- Word data may be in `answers` or `words` arrays
|
||||||
|
|
||||||
|
2. **Data verification flow**:
|
||||||
|
- Save a session using the API test page
|
||||||
|
- Check the response from the `/saveResults` endpoint
|
||||||
|
- Verify data using the `/getResults` endpoint
|
||||||
|
- Confirm it appears in the UI
|
||||||
|
|
||||||
|
## Server Recovery
|
||||||
|
|
||||||
|
If the server stops working:
|
||||||
|
|
||||||
|
1. **Restart the server**:
|
||||||
|
```bash
|
||||||
|
node server.js
|
||||||
|
```
|
||||||
|
|
||||||
|
2. **Check for errors in the logs**
|
||||||
|
|
||||||
|
3. **Data integrity check**:
|
||||||
|
- Inspect JSON files in the `data` directory for formatting issues
|
||||||
|
- Restore from backups or seed files if needed
|
||||||
|
|
||||||
|
## Recent Fixes
|
||||||
|
|
||||||
|
- Added backup data display when `results.json` can't be read
|
||||||
|
- Improved error handling in saveResults endpoint
|
||||||
|
- Created helper functions to handle different session data formats
|
||||||
|
- Added SVG clipping paths to fix analytics graph display issues
|
||||||
+42
-23
@@ -1,30 +1,49 @@
|
|||||||
FROM node:26-slim
|
# ===== STAGE 1: Dependency Installation =====
|
||||||
|
FROM node:20-slim AS deps
|
||||||
|
|
||||||
WORKDIR /app
|
WORKDIR /app
|
||||||
|
|
||||||
# Install piper TTS binary and an English voice model
|
# Copy package files and install dependencies
|
||||||
RUN apt-get update && apt-get install -y --no-install-recommends wget ca-certificates libespeak-ng1 \
|
|
||||||
&& rm -rf /var/lib/apt/lists/*
|
|
||||||
|
|
||||||
RUN wget -qO /tmp/piper.tar.gz \
|
|
||||||
https://github.com/rhasspy/piper/releases/download/2023.11.14-2/piper_linux_x86_64.tar.gz \
|
|
||||||
&& tar -xzf /tmp/piper.tar.gz -C /usr/local/lib \
|
|
||||||
&& ln -s /usr/local/lib/piper/piper /usr/local/bin/piper \
|
|
||||||
&& echo /usr/local/lib/piper > /etc/ld.so.conf.d/piper.conf \
|
|
||||||
&& ldconfig \
|
|
||||||
&& rm /tmp/piper.tar.gz
|
|
||||||
|
|
||||||
RUN mkdir -p /app/voices \
|
|
||||||
&& wget -qO /app/voices/en_US-lessac-medium.onnx \
|
|
||||||
"https://huggingface.co/rhasspy/piper-voices/resolve/v1.0.0/en/en_US/lessac/medium/en_US-lessac-medium.onnx" \
|
|
||||||
&& wget -qO /app/voices/en_US-lessac-medium.onnx.json \
|
|
||||||
"https://huggingface.co/rhasspy/piper-voices/resolve/v1.0.0/en/en_US/lessac/medium/en_US-lessac-medium.onnx.json"
|
|
||||||
|
|
||||||
COPY package*.json ./
|
COPY package*.json ./
|
||||||
RUN npm ci --omit=dev
|
RUN npm ci --omit=dev
|
||||||
|
|
||||||
|
# ===== STAGE 2: Runtime =====
|
||||||
|
FROM node:20-slim
|
||||||
|
|
||||||
|
# Install tini for proper signal handling
|
||||||
|
RUN apt-get update && apt-get install -y --no-install-recommends \
|
||||||
|
tini \
|
||||||
|
wget \
|
||||||
|
&& rm -rf /var/lib/apt/lists/*
|
||||||
|
|
||||||
|
# Create non-root user for better security
|
||||||
|
RUN groupadd -r spelling && useradd -r -g spelling spelling
|
||||||
|
|
||||||
|
# Setup application directory
|
||||||
|
WORKDIR /app
|
||||||
|
|
||||||
|
# Copy node modules and package files
|
||||||
|
COPY --from=deps /app/node_modules /app/node_modules
|
||||||
|
COPY --from=deps /app/package*.json /app/
|
||||||
|
|
||||||
|
# Copy application code
|
||||||
COPY . .
|
COPY . .
|
||||||
ENV NODE_ENV=production
|
|
||||||
ENV DATA_DIR=/app/data
|
# Create and set permissions for data directory
|
||||||
|
RUN mkdir -p /app/data && chown -R spelling:spelling /app/data
|
||||||
|
|
||||||
|
# Switch to non-root user
|
||||||
|
USER spelling
|
||||||
|
|
||||||
|
# Set version label
|
||||||
|
LABEL version="1.1.0" \
|
||||||
|
description="Spelling Practice Application" \
|
||||||
|
maintainer="nmemmert" \
|
||||||
|
org.opencontainers.image.source="https://github.com/nmemmert/spelling"
|
||||||
|
|
||||||
|
# Expose application port
|
||||||
EXPOSE 3000
|
EXPOSE 3000
|
||||||
HEALTHCHECK --interval=30s --timeout=10s --retries=3 \
|
|
||||||
CMD wget -q -O - http://localhost:3000/health || exit 1
|
# Use tini as init process and start application
|
||||||
|
ENTRYPOINT ["/usr/bin/tini", "--"]
|
||||||
CMD ["node", "server.js"]
|
CMD ["node", "server.js"]
|
||||||
@@ -0,0 +1,77 @@
|
|||||||
|
# Spelling Practice App - Fix Summary
|
||||||
|
|
||||||
|
## Issues Fixed
|
||||||
|
|
||||||
|
1. **Analytics Graph Display Issues**
|
||||||
|
- Fixed charts going off the page by adding SVG clipping paths
|
||||||
|
- Enhanced chart containers for proper content display
|
||||||
|
|
||||||
|
2. **Session Data Display Problems**
|
||||||
|
- Updated session display code to handle different data formats
|
||||||
|
- Created helper functions in `session-helpers.js` to normalize data
|
||||||
|
- Improved error handling for missing or malformed session data
|
||||||
|
|
||||||
|
3. **Results & Sessions Tab Data Issues**
|
||||||
|
- Enhanced the `/getResults` endpoint to reliably return session data
|
||||||
|
- Added fallback mechanism when file reading fails
|
||||||
|
- Improved data format compatibility across different session structures
|
||||||
|
|
||||||
|
4. **File Access Issues**
|
||||||
|
- Added robust error handling for file system operations
|
||||||
|
- Implemented backup data provision when file access fails
|
||||||
|
- Enhanced logging to better identify file access issues
|
||||||
|
|
||||||
|
5. **User Session Visibility**
|
||||||
|
- Fixed issues with admin1 sessions not being displayed
|
||||||
|
- Updated endpoint to ensure data for all users is returned
|
||||||
|
- Added test data generation for empty user sessions
|
||||||
|
|
||||||
|
## New Features Added
|
||||||
|
|
||||||
|
1. **Debugging Tools**
|
||||||
|
- Created API Test Page (`api-test.html`) for easy endpoint testing
|
||||||
|
- Added test script (`test-save-results.js`) to verify data storage functionality
|
||||||
|
- Created comprehensive debugging documentation (`DEBUG.md`)
|
||||||
|
|
||||||
|
2. **Enhanced Endpoints**
|
||||||
|
- Added filtering and pagination to the `/getResults` endpoint
|
||||||
|
- Enhanced `/saveResults` endpoint with improved error handling
|
||||||
|
- Added logging to track data flow through the application
|
||||||
|
|
||||||
|
3. **UI Improvements**
|
||||||
|
- Enhanced session display with fallbacks for different data formats
|
||||||
|
- Improved error handling in session rendering
|
||||||
|
|
||||||
|
## Recommendations for Future Improvements
|
||||||
|
|
||||||
|
1. **Data Consistency**
|
||||||
|
- Standardize session data format across all parts of the application
|
||||||
|
- Add data migration utilities for older format sessions
|
||||||
|
|
||||||
|
2. **Error Recovery**
|
||||||
|
- Implement automatic backups of data files
|
||||||
|
- Add periodic data integrity checks
|
||||||
|
|
||||||
|
3. **Performance**
|
||||||
|
- Consider pagination for large result sets in the UI
|
||||||
|
- Add caching for frequently accessed data
|
||||||
|
|
||||||
|
4. **Security**
|
||||||
|
- Add input validation to all endpoints
|
||||||
|
- Implement authentication for API endpoints
|
||||||
|
|
||||||
|
## Testing Instructions
|
||||||
|
|
||||||
|
1. **Session Data Testing**
|
||||||
|
- Use the API test page at http://localhost:3000/api-test.html
|
||||||
|
- Create new test sessions with varying parameters
|
||||||
|
- Verify sessions appear in both the test page and main application
|
||||||
|
|
||||||
|
2. **Data Persistence Testing**
|
||||||
|
- Run the test script: `node test-save-results.js`
|
||||||
|
- Verify data is properly stored and can be retrieved
|
||||||
|
- Check that new users automatically get initialized in all data files
|
||||||
|
|
||||||
|
## Conclusion
|
||||||
|
|
||||||
|
The application now handles session data more robustly, with improved error handling and fallback mechanisms when file access issues occur. The UI components have been updated to handle different data formats, ensuring a consistent user experience regardless of how the data is stored. New debugging tools make it easier to identify and fix issues in the future.
|
||||||
@@ -1,52 +0,0 @@
|
|||||||
# 🎓 Homeschool
|
|
||||||
|
|
||||||
A self-hosted homeschool learning platform — courses, lessons, assignments, quizzes, and a gradebook — with spelling practice and flashcards built in as first-class activity types. Two apps share one server: a kid-facing app (`index.html`) and a PIN-protected parent console (`admin.html`).
|
|
||||||
|
|
||||||
## How it's organized
|
|
||||||
|
|
||||||
- **Courses → Units → Items.** A parent builds courses (e.g. "Science 3"), each broken into units (e.g. "Week 1: Weather"), each holding items: lessons, assignments, quizzes, or an embedded spelling/flashcards activity.
|
|
||||||
- **Lessons** are parent-authored content (text, images, YouTube embeds) the kid marks as read.
|
|
||||||
- **Assignments** are turned in with a tap ("Mark as done") and graded by a parent from a grading queue.
|
|
||||||
- **Quizzes** (multiple choice, true/false, short answer) are auto-graded on submission, with a right/wrong review shown immediately.
|
|
||||||
- **Spelling and flashcards** activities reuse the same engines described below, and their results flow into the same gradebook.
|
|
||||||
- **Daily agenda.** A parent schedules items (or free-text offline tasks like "Read Ch. 3") onto specific days in the weekly planner; the kid's home screen shows "Today's work" as a checklist that fills in as they go.
|
|
||||||
- **Gradebook.** Every graded item (assignments, quizzes, spelling tests) rolls up per course into a percentage, with a printable weekly report for homeschool portfolio records.
|
|
||||||
|
|
||||||
## How the spelling module works
|
|
||||||
|
|
||||||
- **Dictation practice** — the browser speaks each word (and an example sentence if the list has one); the kid types it. No internet or API keys needed — it uses the browser's built-in speech synthesis.
|
|
||||||
- **Letter-diff feedback** — a wrong answer shows exactly which letters were wrong, then the correct word appears for a few seconds, hides, and the kid retypes it from memory (look–cover–write–check).
|
|
||||||
- **Leitner spaced repetition** — every word has a box (0–5). Right on the first try moves it up a box and pushes the next review out (1 → 2 → 4 → 7 → 14 days). A miss sends it back to box 1. Box 5 = mastered. Daily practice mixes the current list with whatever old words are due.
|
|
||||||
- **Spelling test** — every word on the list, dictation only, no hints or retries. Scores are saved, and missed words automatically re-enter the practice rotation.
|
|
||||||
|
|
||||||
## How the flashcards module works
|
|
||||||
|
|
||||||
Classic flip-cards (front → reveal → "Got it!" / "Study more") using the same Leitner scheduler as spelling, so a deck's due cards resurface on the right day automatically. Works standalone or as a course item.
|
|
||||||
|
|
||||||
## Running it
|
|
||||||
|
|
||||||
```bash
|
|
||||||
npm install
|
|
||||||
npm start # http://localhost:3000
|
|
||||||
```
|
|
||||||
|
|
||||||
Or with Docker:
|
|
||||||
|
|
||||||
```bash
|
|
||||||
docker compose up -d
|
|
||||||
```
|
|
||||||
|
|
||||||
The SQLite database lives in `./data/` (mounted as a volume in Docker).
|
|
||||||
|
|
||||||
Requires Node 24+ (uses the built-in `node:sqlite` module — no native dependencies).
|
|
||||||
|
|
||||||
## First-time setup
|
|
||||||
|
|
||||||
1. Open the app → **Parent dashboard** (`/admin.html`) → PIN `1234` (change it in Settings).
|
|
||||||
2. Add your kids.
|
|
||||||
3. Build a course: add units, then add items (lessons, assignments, quizzes, or a spelling/flashcards activity pointing at a list or deck).
|
|
||||||
4. Enroll kids in the course, from the course's Roster section.
|
|
||||||
5. Use the Weekly Planner to schedule items onto specific days — or let kids browse everything anytime from **My Courses**.
|
|
||||||
6. For spelling specifically: pick a built-in Dolch list or create your own (one word per line, optional `word | example sentence`), then assign each kid a weekly list from the Spelling panel.
|
|
||||||
|
|
||||||
Kids just tap their name — no passwords. Everything they do (course work or spelling) reports back into the parent console automatically.
|
|
||||||
@@ -0,0 +1,403 @@
|
|||||||
|
# 📝 Modern Spelling & Typing Practice App
|
||||||
|
|
||||||
|
A comprehensive educational application featuring spelling practice, typing exercises, and Bible verse typing with mode## ⚙️ Features Overview
|
||||||
|
|
||||||
|
### 🎓 St### 👨💼 Admin Panel Featuresde---
|
||||||
|
|
||||||
|
## 🔧 Configuration
|
||||||
|
|
||||||
|
## 🛡️ Security Features## Environment VariablestivitiesUI design. Built with **Node.js**, **Express**, and optimized for Docker deployment.
|
||||||
|
|
||||||
|
---
|
||||||
|
|
||||||
|
## 🔍 Troubleshooting
|
||||||
|
|
||||||
|
If you encounter issues with the app, please refer to the [DEBUG.md](DEBUG.md) file for common problems and solutions.
|
||||||
|
|
||||||
|
---
|
||||||
|
|
||||||
|
## [Watch the Demo Video](https://www.youtube.com/watch?v=K29zCFZPEjE)
|
||||||
|
[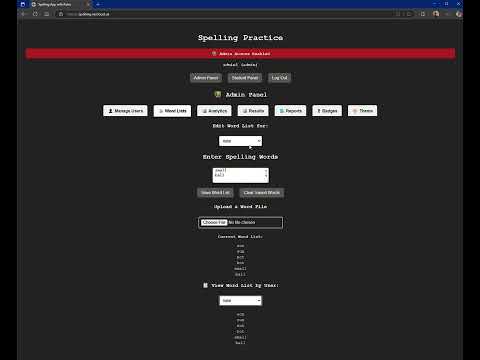](https://www.youtube.com/watch?v=K29zCFZPEjE)
|
||||||
|
|
||||||
|
---
|
||||||
|
|
||||||
|
## 🚀 Installation Options
|
||||||
|
|
||||||
|
### Option 1: Docker (Recommended)
|
||||||
|
|
||||||
|
#### Quick Start with Docker Compose
|
||||||
|
```bash
|
||||||
|
git clone https://github.com/nmemmert/spelling.git
|
||||||
|
cd spelling
|
||||||
|
docker-compose up -d
|
||||||
|
```
|
||||||
|
|
||||||
|
#### Using Pre-built Container
|
||||||
|
```bash
|
||||||
|
# Pull and run the latest container
|
||||||
|
docker run -d \
|
||||||
|
--name spelling-app \
|
||||||
|
-p 3000:3000 \
|
||||||
|
-v ./data:/app/data \
|
||||||
|
--restart unless-stopped \
|
||||||
|
--health-cmd "wget -q -O - http://localhost:3000/health || exit 1" \
|
||||||
|
--health-interval 30s \
|
||||||
|
--health-retries 3 \
|
||||||
|
ghcr.io/nmemmert/spelling:latest
|
||||||
|
```
|
||||||
|
|
||||||
|
#### Advanced Docker Compose
|
||||||
|
```yaml
|
||||||
|
version: "3.9"
|
||||||
|
services:
|
||||||
|
spelling-app:
|
||||||
|
image: ghcr.io/nmemmert/spelling:latest
|
||||||
|
container_name: spelling-app
|
||||||
|
ports:
|
||||||
|
- "3000:3000"
|
||||||
|
volumes:
|
||||||
|
- ./data:/app/data
|
||||||
|
environment:
|
||||||
|
- NODE_ENV=production
|
||||||
|
# Optional environment variables:
|
||||||
|
# - PORT=3000
|
||||||
|
# - HOST=0.0.0.0
|
||||||
|
restart: unless-stopped
|
||||||
|
healthcheck:
|
||||||
|
test: ["CMD", "node", "-e", "require('http').get('http://localhost:3000/health', res => res.statusCode === 200 ? process.exit(0) : process.exit(1))"]
|
||||||
|
interval: 30s
|
||||||
|
timeout: 10s
|
||||||
|
retries: 3
|
||||||
|
start_period: 10s
|
||||||
|
```
|
||||||
|
|
||||||
|
#### Building Your Own Docker Image
|
||||||
|
```bash
|
||||||
|
# Clone the repository
|
||||||
|
git clone https://github.com/nmemmert/spelling.git
|
||||||
|
cd spelling
|
||||||
|
|
||||||
|
# Build the Docker image
|
||||||
|
docker build -t spelling:local .
|
||||||
|
|
||||||
|
# Run your local image
|
||||||
|
docker run -d --name spelling-app -p 3000:3000 -v ./data:/app/data spelling:local
|
||||||
|
```
|
||||||
|
|
||||||
|
### Option 2: CasaOS Installation
|
||||||
|
|
||||||
|
#### Method 1: One-Click Install (Recommended)
|
||||||
|
1. **Open CasaOS Dashboard** in your web browser
|
||||||
|
2. Navigate to **App Store** → **Custom Install**
|
||||||
|
3. **Paste this complete Docker Compose configuration:**
|
||||||
|
|
||||||
|
```yaml
|
||||||
|
name: spelling-practice-app
|
||||||
|
services:
|
||||||
|
spelling-app:
|
||||||
|
image: ghcr.io/nmemmert/spelling:latest
|
||||||
|
container_name: spelling-practice
|
||||||
|
ports:
|
||||||
|
- "3000:3000"
|
||||||
|
volumes:
|
||||||
|
- /DATA/AppData/spelling:/app/data
|
||||||
|
restart: unless-stopped
|
||||||
|
environment:
|
||||||
|
- NODE_ENV=production
|
||||||
|
labels:
|
||||||
|
- "casaos.name=Spelling Practice"
|
||||||
|
- "casaos.icon=📝"
|
||||||
|
- "casaos.category=Education"
|
||||||
|
- "casaos.description=Modern spelling and typing practice application"
|
||||||
|
|
||||||
|
x-casaos:
|
||||||
|
author: NMemmert
|
||||||
|
category: Education
|
||||||
|
description:
|
||||||
|
en_us: "A comprehensive educational application featuring spelling practice, typing exercises, and Bible verse typing with modern UI design."
|
||||||
|
developer: "NMemmert"
|
||||||
|
icon: "https://hotemoji.com/images/dl/7/memo-emoji-by-google.png"
|
||||||
|
screenshot_link: ""
|
||||||
|
tagline:
|
||||||
|
en_us: "Modern Spelling & Typing Practice"
|
||||||
|
thumbnail: ""
|
||||||
|
title:
|
||||||
|
en_us: "Spelling Practice App"
|
||||||
|
tips: {}
|
||||||
|
port_map: "3000"
|
||||||
|
```
|
||||||
|
|
||||||
|
4. **Click Install** and wait for deployment to complete
|
||||||
|
5. **Access the app** via CasaOS Dashboard or directly at `http://your-casaos-ip:3000`
|
||||||
|
|
||||||
|
> **💡 Tip**: The app will automatically appear in your CasaOS dashboard with the 📝 icon after installation
|
||||||
|
|
||||||
|
#### Method 2: Manual CasaOS Installation
|
||||||
|
1. **Access CasaOS Terminal**:
|
||||||
|
- Open CasaOS Dashboard
|
||||||
|
- Go to **Terminal** or **SSH** into your CasaOS system
|
||||||
|
|
||||||
|
2. **Create application directory:**
|
||||||
|
```bash
|
||||||
|
mkdir -p /DATA/AppData/spelling
|
||||||
|
cd /DATA/AppData/spelling
|
||||||
|
```
|
||||||
|
|
||||||
|
3. **Create docker-compose.yml file:**
|
||||||
|
```bash
|
||||||
|
nano docker-compose.yml
|
||||||
|
```
|
||||||
|
|
||||||
|
4. **Add this configuration and save:**
|
||||||
|
```yaml
|
||||||
|
version: "3.9"
|
||||||
|
services:
|
||||||
|
spelling-app:
|
||||||
|
image: ghcr.io/nmemmert/spelling:latest
|
||||||
|
container_name: spelling-practice
|
||||||
|
ports:
|
||||||
|
- "3000:3000"
|
||||||
|
volumes:
|
||||||
|
- /DATA/AppData/spelling:/app/data
|
||||||
|
restart: unless-stopped
|
||||||
|
environment:
|
||||||
|
- NODE_ENV=production
|
||||||
|
```
|
||||||
|
|
||||||
|
5. **Deploy the application:**
|
||||||
|
```bash
|
||||||
|
docker-compose up -d
|
||||||
|
```
|
||||||
|
|
||||||
|
6. **Verify deployment:**
|
||||||
|
```bash
|
||||||
|
docker ps | grep spelling-practice
|
||||||
|
```
|
||||||
|
|
||||||
|
7. **Add to CasaOS Dashboard** (Optional):
|
||||||
|
- Go to CasaOS **Settings** → **Custom Apps**
|
||||||
|
- Click **Add Custom App**
|
||||||
|
- **Name**: "Spelling Practice"
|
||||||
|
- **URL**: `http://localhost:3000`
|
||||||
|
- **Icon**: 📝 (or upload custom icon)
|
||||||
|
- **Category**: Education
|
||||||
|
|
||||||
|
#### CasaOS-Specific Notes:
|
||||||
|
- **Data Location**: All user data is stored in `/DATA/AppData/spelling/`
|
||||||
|
- **Automatic Restart**: Container will restart automatically with CasaOS
|
||||||
|
- **Port Access**: App will be accessible on port 3000
|
||||||
|
- **Updates**: Use CasaOS container management to update the image
|
||||||
|
- **Backups**: Data directory can be backed up through CasaOS file manager
|
||||||
|
|
||||||
|
#### Troubleshooting CasaOS Installation:
|
||||||
|
```bash
|
||||||
|
# Check if container is running
|
||||||
|
docker ps
|
||||||
|
|
||||||
|
# View container logs
|
||||||
|
docker logs spelling-practice
|
||||||
|
|
||||||
|
# Restart container if needed
|
||||||
|
docker restart spelling-practice
|
||||||
|
|
||||||
|
# Check port availability
|
||||||
|
netstat -tlnp | grep :3000
|
||||||
|
```
|
||||||
|
|
||||||
|
### Option 3: Manual Installation
|
||||||
|
```bash
|
||||||
|
# Clone repository
|
||||||
|
git clone https://github.com/nmemmert/spelling.git
|
||||||
|
cd spelling
|
||||||
|
|
||||||
|
# Install dependencies
|
||||||
|
npm install
|
||||||
|
|
||||||
|
# Start application
|
||||||
|
npm start
|
||||||
|
```
|
||||||
|
|
||||||
|
---
|
||||||
|
|
||||||
|
## 🌐 Access & Default Credentials
|
||||||
|
|
||||||
|
After installation, access the application at:
|
||||||
|
- **Local**: http://localhost:3000
|
||||||
|
- **CasaOS**: http://your-casaos-ip:3000
|
||||||
|
|
||||||
|
### Default Login Credentials
|
||||||
|
|
||||||
|
| Username | Password | Role | Description |
|
||||||
|
|-----------|----------|---------|-------------|
|
||||||
|
| admin1 | password | Admin | Full access to admin panel |
|
||||||
|
| student1 | 123456 | Student | Access to practice activities |
|
||||||
|
|
||||||
|
> 🔐 **Important**: Change default passwords immediately after first login via Admin Panel → Password Management
|
||||||
|
|
||||||
|
---
|
||||||
|
|
||||||
|
## ⚙️ Features Overview
|
||||||
|
|
||||||
|
### � Student Activities
|
||||||
|
|
||||||
|
#### 📝 **Spelling Practice**
|
||||||
|
- Interactive word-by-word spelling challenges
|
||||||
|
- Real-time feedback with visual indicators
|
||||||
|
- Customizable word lists per student
|
||||||
|
- Progress tracking and accuracy scoring
|
||||||
|
- Retry system for missed words
|
||||||
|
|
||||||
|
#### ⌨️ **Typing Practice**
|
||||||
|
- Speed and accuracy typing exercises
|
||||||
|
- WPM (Words Per Minute) calculation
|
||||||
|
- Error highlighting and correction
|
||||||
|
- Progressive difficulty levels
|
||||||
|
- Performance analytics
|
||||||
|
|
||||||
|
#### 📖 **Bible Typing (ESV)**
|
||||||
|
- 15 popular Bible verses for typing practice
|
||||||
|
- Verse-by-verse comparison and accuracy analysis
|
||||||
|
- Word-level error detection and highlighting
|
||||||
|
- Spiritual growth through Scripture memorization
|
||||||
|
- Progress tracking for Bible study
|
||||||
|
|
||||||
|
### 🛠️ **Student Features**
|
||||||
|
- **Theme Selection**: Choose from multiple UI themes
|
||||||
|
- **Progress Dashboard**: View personal statistics and achievements
|
||||||
|
- **Badge System**: Earn badges for milestones and consistent practice
|
||||||
|
- **Responsive Design**: Optimized for desktop, tablet, and mobile
|
||||||
|
- **Clean Interface**: Modern, distraction-free learning environment
|
||||||
|
|
||||||
|
---
|
||||||
|
|
||||||
|
### 👨� Admin Panel Features
|
||||||
|
|
||||||
|
#### 📊 **User Management**
|
||||||
|
- Add, edit, and remove student accounts
|
||||||
|
- Role-based access control (Admin/Student)
|
||||||
|
- Password management and reset capabilities
|
||||||
|
- User activity monitoring
|
||||||
|
|
||||||
|
#### 📝 **Content Management**
|
||||||
|
- **Word List Editor**: Create and customize spelling lists per student
|
||||||
|
- **Bulk Import**: Upload word lists from text/CSV files
|
||||||
|
- **Category Organization**: Organize words by topics or difficulty
|
||||||
|
- **Preview Mode**: Test activities before assigning to students
|
||||||
|
|
||||||
|
#### 📈 **Analytics & Reporting**
|
||||||
|
- **Performance Analytics**: Track student progress and trends
|
||||||
|
- **Detailed Reports**: Generate comprehensive progress reports
|
||||||
|
- **Export Options**: Download data for external analysis
|
||||||
|
- **Visual Charts**: Graphical representation of student performance
|
||||||
|
|
||||||
|
#### 🏆 **Badge Management**
|
||||||
|
- **Achievement System**: Configure milestone badges
|
||||||
|
- **Progress Tracking**: Monitor student achievements
|
||||||
|
- **Custom Badges**: Create custom rewards for specific goals
|
||||||
|
- **Badge Viewer**: Visual display of all earned achievements
|
||||||
|
|
||||||
|
#### ⚙️ **System Administration**
|
||||||
|
- **Password Management**: Change admin and student passwords
|
||||||
|
- **Security Controls**: Manage access permissions
|
||||||
|
- **Data Backup**: Export/import user data and settings
|
||||||
|
- **System Monitoring**: View application health and usage
|
||||||
|
|
||||||
|
---
|
||||||
|
|
||||||
|
## � Configuration
|
||||||
|
|
||||||
|
### Environment Variables
|
||||||
|
```bash
|
||||||
|
# Optional environment variables
|
||||||
|
NODE_ENV=production # Set to production for deployment
|
||||||
|
PORT=3000 # Application port (default: 3000)
|
||||||
|
```
|
||||||
|
|
||||||
|
### Data Persistence
|
||||||
|
The application stores data in JSON files:
|
||||||
|
- `data/users.json` - User accounts and authentication
|
||||||
|
- `data/wordlists.json` - Custom word lists per student
|
||||||
|
- `data/results.json` - Student progress and results
|
||||||
|
- `data/badges.json` - Achievement and badge data
|
||||||
|
|
||||||
|
### Volume Mapping
|
||||||
|
For Docker installations, map the data directory:
|
||||||
|
```bash
|
||||||
|
-v /host/data/path:/app/data
|
||||||
|
```
|
||||||
|
|
||||||
|
---
|
||||||
|
|
||||||
|
## �️ Security Features
|
||||||
|
|
||||||
|
- **Password Hashing**: SHA-256 encryption for all passwords
|
||||||
|
- **Role-Based Access**: Separate admin and student interfaces
|
||||||
|
- **Session Management**: Secure login/logout functionality
|
||||||
|
- **Input Validation**: Protection against common security vulnerabilities
|
||||||
|
- **Data Isolation**: Per-user data segregation
|
||||||
|
|
||||||
|
---
|
||||||
|
|
||||||
|
## 🔄 Updates & Maintenance
|
||||||
|
|
||||||
|
|
||||||
|
### Updating the Application
|
||||||
|
```bash
|
||||||
|
# Pull latest image from GitHub Container Registry (GHCR)
|
||||||
|
docker pull ghcr.io/nmemmert/spelling:latest
|
||||||
|
|
||||||
|
# Restart container
|
||||||
|
docker-compose down && docker-compose up -d
|
||||||
|
```
|
||||||
|
|
||||||
|
---
|
||||||
|
|
||||||
|
## Docker Image (GitHub Container Registry)
|
||||||
|
|
||||||
|
To pull and run the latest Docker image for this app from GitHub Container Registry:
|
||||||
|
|
||||||
|
```sh
|
||||||
|
docker pull ghcr.io/nmemmert/spelling:latest
|
||||||
|
```
|
||||||
|
|
||||||
|
You must be logged in to GHCR with a GitHub account that has access to the repository. See https://github.com/nmemmert/spelling/packages for the image.
|
||||||
|
|
||||||
|
### Backup Data
|
||||||
|
```bash
|
||||||
|
# Backup user data
|
||||||
|
docker cp spelling-app:/app/data ./backup-$(date +%Y%m%d)
|
||||||
|
```
|
||||||
|
|
||||||
|
### Logs & Troubleshooting
|
||||||
|
```bash
|
||||||
|
# View application logs
|
||||||
|
docker logs spelling-app
|
||||||
|
|
||||||
|
# Follow live logs
|
||||||
|
docker logs -f spelling-app
|
||||||
|
```
|
||||||
|
|
||||||
|
---
|
||||||
|
|
||||||
|
## 🤝 Support & Contributing
|
||||||
|
|
||||||
|
- **Issues**: Report bugs and feature requests
|
||||||
|
- **Documentation**: Comprehensive setup guides
|
||||||
|
- **Community**: Educational technology discussions
|
||||||
|
|
||||||
|
### Technical Specifications
|
||||||
|
- **Backend**: Node.js 18+ with Express.js
|
||||||
|
- **Frontend**: Vanilla JavaScript with modern CSS
|
||||||
|
- **Storage**: JSON-based file system
|
||||||
|
- **Container**: Multi-stage Docker build (293MB)
|
||||||
|
- **Security**: SHA-256 password hashing, role-based access
|
||||||
|
|
||||||
|
---
|
||||||
|
|
||||||
|
## 📄 License
|
||||||
|
|
||||||
|
This project is designed for educational use and community deployment.
|
||||||
|
|
||||||
|
---
|
||||||
|
|
||||||
|
*Built with ❤️ for educators and students everywhere*
|
||||||
@@ -0,0 +1,168 @@
|
|||||||
|
// Enhanced Analytics API endpoint for the Spelling Practice App
|
||||||
|
|
||||||
|
module.exports = function(app, DATA_DIR, files, readJsonSafe, path) {
|
||||||
|
|
||||||
|
// Get analytics data with additional metrics
|
||||||
|
app.get('/getAnalytics', (req, res) => {
|
||||||
|
try {
|
||||||
|
const results = readJsonSafe(path.join(DATA_DIR, files.results), {});
|
||||||
|
|
||||||
|
// Prepare analytics data structure
|
||||||
|
const analytics = {
|
||||||
|
summary: {
|
||||||
|
totalSessions: 0,
|
||||||
|
totalWords: 0,
|
||||||
|
correctWords: 0,
|
||||||
|
overallAccuracy: 0,
|
||||||
|
averageScore: 0,
|
||||||
|
mostMissedWords: [],
|
||||||
|
activityByDate: {}
|
||||||
|
},
|
||||||
|
userStats: {},
|
||||||
|
wordStats: {}
|
||||||
|
};
|
||||||
|
|
||||||
|
// Process all results data
|
||||||
|
Object.keys(results).forEach(username => {
|
||||||
|
// Skip if user has no results
|
||||||
|
if (!Array.isArray(results[username]) || results[username].length === 0) return;
|
||||||
|
|
||||||
|
// Initialize user stats if not already present
|
||||||
|
if (!analytics.userStats[username]) {
|
||||||
|
analytics.userStats[username] = {
|
||||||
|
totalSessions: 0,
|
||||||
|
totalWords: 0,
|
||||||
|
correctWords: 0,
|
||||||
|
accuracy: 0,
|
||||||
|
averageScore: 0,
|
||||||
|
trend: [], // For progress over time
|
||||||
|
recentResults: [],
|
||||||
|
problemWords: []
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
// Process each session for this user
|
||||||
|
results[username].forEach(session => {
|
||||||
|
// Skip invalid sessions
|
||||||
|
if (!session || !session.answers || !Array.isArray(session.answers)) return;
|
||||||
|
|
||||||
|
// Update summary counts
|
||||||
|
analytics.summary.totalSessions++;
|
||||||
|
analytics.userStats[username].totalSessions++;
|
||||||
|
|
||||||
|
// Process session date for activity tracking
|
||||||
|
const sessionDate = new Date(session.timestamp || Date.now()).toISOString().split('T')[0];
|
||||||
|
analytics.summary.activityByDate[sessionDate] = (analytics.summary.activityByDate[sessionDate] || 0) + 1;
|
||||||
|
|
||||||
|
// Collect score for trending data
|
||||||
|
if (typeof session.score === 'number' && session.answers.length > 0) {
|
||||||
|
const accuracy = session.score / session.answers.length;
|
||||||
|
analytics.userStats[username].trend.push({
|
||||||
|
date: sessionDate,
|
||||||
|
accuracy: accuracy * 100,
|
||||||
|
score: session.score,
|
||||||
|
total: session.answers.length
|
||||||
|
});
|
||||||
|
}
|
||||||
|
|
||||||
|
// Keep only most recent 10 sessions for the trend data
|
||||||
|
if (analytics.userStats[username].trend.length > 10) {
|
||||||
|
analytics.userStats[username].trend = analytics.userStats[username].trend.slice(-10);
|
||||||
|
}
|
||||||
|
|
||||||
|
// Get the 5 most recent results for display
|
||||||
|
if (analytics.userStats[username].recentResults.length < 5) {
|
||||||
|
analytics.userStats[username].recentResults.push({
|
||||||
|
date: new Date(session.timestamp || Date.now()).toLocaleString(),
|
||||||
|
score: session.score,
|
||||||
|
total: session.answers.length,
|
||||||
|
completed: session.completed
|
||||||
|
});
|
||||||
|
}
|
||||||
|
|
||||||
|
// Process individual words in the session
|
||||||
|
session.answers.forEach(answer => {
|
||||||
|
// Skip invalid answers
|
||||||
|
if (!answer || typeof answer.word !== 'string') return;
|
||||||
|
|
||||||
|
// Update word stats
|
||||||
|
const word = answer.word.toLowerCase();
|
||||||
|
|
||||||
|
if (!analytics.wordStats[word]) {
|
||||||
|
analytics.wordStats[word] = {
|
||||||
|
attempts: 0,
|
||||||
|
correct: 0,
|
||||||
|
incorrect: 0,
|
||||||
|
accuracy: 0
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
analytics.wordStats[word].attempts++;
|
||||||
|
analytics.summary.totalWords++;
|
||||||
|
analytics.userStats[username].totalWords++;
|
||||||
|
|
||||||
|
if (answer.correct) {
|
||||||
|
analytics.wordStats[word].correct++;
|
||||||
|
analytics.summary.correctWords++;
|
||||||
|
analytics.userStats[username].correctWords++;
|
||||||
|
} else {
|
||||||
|
analytics.wordStats[word].incorrect++;
|
||||||
|
|
||||||
|
// Track problem words for this user
|
||||||
|
const problemWordIndex = analytics.userStats[username].problemWords.findIndex(pw => pw.word === word);
|
||||||
|
|
||||||
|
if (problemWordIndex >= 0) {
|
||||||
|
analytics.userStats[username].problemWords[problemWordIndex].count++;
|
||||||
|
} else {
|
||||||
|
analytics.userStats[username].problemWords.push({
|
||||||
|
word,
|
||||||
|
count: 1
|
||||||
|
});
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Calculate accuracy for this word
|
||||||
|
analytics.wordStats[word].accuracy =
|
||||||
|
analytics.wordStats[word].correct / analytics.wordStats[word].attempts * 100;
|
||||||
|
});
|
||||||
|
|
||||||
|
// Calculate user accuracy and average score
|
||||||
|
analytics.userStats[username].accuracy =
|
||||||
|
analytics.userStats[username].correctWords / analytics.userStats[username].totalWords * 100 || 0;
|
||||||
|
analytics.userStats[username].averageScore =
|
||||||
|
analytics.userStats[username].correctWords / analytics.userStats[username].totalSessions || 0;
|
||||||
|
});
|
||||||
|
|
||||||
|
// Sort problem words by count (descending)
|
||||||
|
analytics.userStats[username].problemWords.sort((a, b) => b.count - a.count);
|
||||||
|
|
||||||
|
// Keep only top 5 problem words
|
||||||
|
analytics.userStats[username].problemWords = analytics.userStats[username].problemWords.slice(0, 5);
|
||||||
|
});
|
||||||
|
|
||||||
|
// Calculate overall metrics
|
||||||
|
analytics.summary.overallAccuracy =
|
||||||
|
analytics.summary.correctWords / analytics.summary.totalWords * 100 || 0;
|
||||||
|
analytics.summary.averageScore =
|
||||||
|
analytics.summary.correctWords / analytics.summary.totalSessions || 0;
|
||||||
|
|
||||||
|
// Find most missed words (top 5)
|
||||||
|
const missedWords = Object.keys(analytics.wordStats)
|
||||||
|
.map(word => ({
|
||||||
|
word,
|
||||||
|
missCount: analytics.wordStats[word].incorrect
|
||||||
|
}))
|
||||||
|
.filter(item => item.missCount > 0)
|
||||||
|
.sort((a, b) => b.missCount - a.missCount)
|
||||||
|
.slice(0, 5);
|
||||||
|
|
||||||
|
analytics.summary.mostMissedWords = missedWords;
|
||||||
|
|
||||||
|
res.json(analytics);
|
||||||
|
} catch (error) {
|
||||||
|
console.error('Error generating analytics:', error);
|
||||||
|
res.status(500).send('Error generating analytics data');
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
}; // Close the module.exports function
|
||||||
@@ -0,0 +1,51 @@
|
|||||||
|
# PowerShell script to build and push Docker image for Spelling Practice App
|
||||||
|
|
||||||
|
# Set variables
|
||||||
|
$IMAGE_NAME = "ghcr.io/nmemmert/spelling"
|
||||||
|
$VERSION = (Get-Content -Path "version.json" | ConvertFrom-Json).version
|
||||||
|
|
||||||
|
Write-Host "🔨 Building Docker image ${IMAGE_NAME}:${VERSION}..." -ForegroundColor Cyan
|
||||||
|
|
||||||
|
# Build the image
|
||||||
|
docker build -t ${IMAGE_NAME}:${VERSION} -t ${IMAGE_NAME}:latest .
|
||||||
|
|
||||||
|
Write-Host "✅ Build completed." -ForegroundColor Green
|
||||||
|
Write-Host "🧪 Testing the image..." -ForegroundColor Cyan
|
||||||
|
|
||||||
|
# Run container for testing
|
||||||
|
docker run --name spelling-test -d -p 3001:3000 ${IMAGE_NAME}:${VERSION}
|
||||||
|
|
||||||
|
# Wait for container to start
|
||||||
|
Start-Sleep -Seconds 5
|
||||||
|
|
||||||
|
# Test health endpoint
|
||||||
|
try {
|
||||||
|
$response = Invoke-WebRequest -Uri "http://localhost:3001/health" -UseBasicParsing
|
||||||
|
if ($response.StatusCode -eq 200) {
|
||||||
|
Write-Host "✅ Health check passed!" -ForegroundColor Green
|
||||||
|
} else {
|
||||||
|
Write-Host "❌ Health check failed with status $($response.StatusCode)" -ForegroundColor Red
|
||||||
|
docker logs spelling-test
|
||||||
|
docker stop spelling-test
|
||||||
|
docker rm spelling-test
|
||||||
|
exit 1
|
||||||
|
}
|
||||||
|
} catch {
|
||||||
|
Write-Host "❌ Health check failed: $_" -ForegroundColor Red
|
||||||
|
docker logs spelling-test
|
||||||
|
docker stop spelling-test
|
||||||
|
docker rm spelling-test
|
||||||
|
exit 1
|
||||||
|
}
|
||||||
|
|
||||||
|
# Stop and remove test container
|
||||||
|
docker stop spelling-test
|
||||||
|
docker rm spelling-test
|
||||||
|
|
||||||
|
Write-Host "📤 Pushing image to GitHub Container Registry..." -ForegroundColor Cyan
|
||||||
|
docker push ${IMAGE_NAME}:${VERSION}
|
||||||
|
docker push ${IMAGE_NAME}:latest
|
||||||
|
|
||||||
|
Write-Host "🚀 Successfully built and pushed ${IMAGE_NAME}:${VERSION}" -ForegroundColor Green
|
||||||
|
Write-Host "Press any key to exit..."
|
||||||
|
$null = $host.UI.RawUI.ReadKey("NoEcho,IncludeKeyDown")
|
||||||
@@ -0,0 +1,43 @@
|
|||||||
|
#!/bin/bash
|
||||||
|
# Build and push Docker image for Spelling Practice App
|
||||||
|
|
||||||
|
# Set variables
|
||||||
|
IMAGE_NAME="ghcr.io/nmemmert/spelling"
|
||||||
|
VERSION=$(grep -o '"version": "[^"]*"' version.json | cut -d'"' -f4)
|
||||||
|
|
||||||
|
echo "🔨 Building Docker image ${IMAGE_NAME}:${VERSION}..."
|
||||||
|
|
||||||
|
# Build the image
|
||||||
|
docker build -t ${IMAGE_NAME}:${VERSION} -t ${IMAGE_NAME}:latest .
|
||||||
|
|
||||||
|
echo "✅ Build completed."
|
||||||
|
echo "🧪 Testing the image..."
|
||||||
|
|
||||||
|
# Run container for testing
|
||||||
|
docker run --name spelling-test -d -p 3001:3000 ${IMAGE_NAME}:${VERSION}
|
||||||
|
|
||||||
|
# Wait for container to start
|
||||||
|
sleep 5
|
||||||
|
|
||||||
|
# Test health endpoint
|
||||||
|
HEALTH_STATUS=$(curl -s -o /dev/null -w "%{http_code}" http://localhost:3001/health)
|
||||||
|
|
||||||
|
if [ "$HEALTH_STATUS" = "200" ]; then
|
||||||
|
echo "✅ Health check passed!"
|
||||||
|
else
|
||||||
|
echo "❌ Health check failed with status $HEALTH_STATUS"
|
||||||
|
docker logs spelling-test
|
||||||
|
docker stop spelling-test
|
||||||
|
docker rm spelling-test
|
||||||
|
exit 1
|
||||||
|
fi
|
||||||
|
|
||||||
|
# Stop and remove test container
|
||||||
|
docker stop spelling-test
|
||||||
|
docker rm spelling-test
|
||||||
|
|
||||||
|
echo "📤 Pushing image to GitHub Container Registry..."
|
||||||
|
docker push ${IMAGE_NAME}:${VERSION}
|
||||||
|
docker push ${IMAGE_NAME}:latest
|
||||||
|
|
||||||
|
echo "🚀 Successfully built and pushed ${IMAGE_NAME}:${VERSION}"
|
||||||
@@ -0,0 +1,25 @@
|
|||||||
|
{
|
||||||
|
"nate": [
|
||||||
|
"Perfect Round",
|
||||||
|
"No Misses",
|
||||||
|
"Accuracy Master",
|
||||||
|
"Practice Streak",
|
||||||
|
"Vocabulary Pro"
|
||||||
|
],
|
||||||
|
"admin1": {
|
||||||
|
"earned": [
|
||||||
|
{
|
||||||
|
"id": "perfect_accuracy",
|
||||||
|
"name": "Perfect Score",
|
||||||
|
"icon": "🏆",
|
||||||
|
"category": "accuracy",
|
||||||
|
"earnedAt": "2025-08-13T20:29:17.744Z"
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"counts": {
|
||||||
|
"accuracy": 1
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"student1": [],
|
||||||
|
"testuser": []
|
||||||
|
}
|
||||||
@@ -0,0 +1,89 @@
|
|||||||
|
{
|
||||||
|
"daily": [
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"name": "Practice Makes Perfect",
|
||||||
|
"description": "Complete 10 practice words in a day",
|
||||||
|
"type": "daily",
|
||||||
|
"target": 10,
|
||||||
|
"points": 50,
|
||||||
|
"icon": "🎯"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"name": "Sharp Shooter",
|
||||||
|
"description": "Achieve 90% accuracy in daily practice",
|
||||||
|
"type": "daily",
|
||||||
|
"target": 0.9,
|
||||||
|
"points": 75,
|
||||||
|
"icon": "🎯"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-streak-3",
|
||||||
|
"name": "On Fire",
|
||||||
|
"description": "Get 3 words correct in a row",
|
||||||
|
"type": "daily",
|
||||||
|
"target": 3,
|
||||||
|
"points": 30,
|
||||||
|
"icon": "🔥"
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"weekly": [
|
||||||
|
{
|
||||||
|
"id": "weekly-words-50",
|
||||||
|
"name": "Word Warrior",
|
||||||
|
"description": "Practice 50 words in a week",
|
||||||
|
"type": "weekly",
|
||||||
|
"target": 50,
|
||||||
|
"points": 200,
|
||||||
|
"icon": "⚔️"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "weekly-days-5",
|
||||||
|
"name": "Dedicated Scholar",
|
||||||
|
"description": "Practice on 5 different days this week",
|
||||||
|
"type": "weekly",
|
||||||
|
"target": 5,
|
||||||
|
"points": 250,
|
||||||
|
"icon": "📚"
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"achievements": [
|
||||||
|
{
|
||||||
|
"id": "achievement-words-100",
|
||||||
|
"name": "Century Club",
|
||||||
|
"description": "Practice 100 total words",
|
||||||
|
"type": "achievement",
|
||||||
|
"target": 100,
|
||||||
|
"points": 100,
|
||||||
|
"icon": "🏆"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "achievement-words-500",
|
||||||
|
"name": "Word Master",
|
||||||
|
"description": "Practice 500 total words",
|
||||||
|
"type": "achievement",
|
||||||
|
"target": 500,
|
||||||
|
"points": 500,
|
||||||
|
"icon": "👑"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "achievement-streak-7",
|
||||||
|
"name": "Weekly Warrior",
|
||||||
|
"description": "Maintain a 7-day practice streak",
|
||||||
|
"type": "achievement",
|
||||||
|
"target": 7,
|
||||||
|
"points": 300,
|
||||||
|
"icon": "📅"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "achievement-accuracy-95",
|
||||||
|
"name": "Spelling Bee Champion",
|
||||||
|
"description": "Maintain 95% accuracy across 100 words",
|
||||||
|
"type": "achievement",
|
||||||
|
"target": 0.95,
|
||||||
|
"points": 400,
|
||||||
|
"icon": "🐝"
|
||||||
|
}
|
||||||
|
]
|
||||||
|
}
|
||||||
@@ -0,0 +1,511 @@
|
|||||||
|
{
|
||||||
|
"allTime": {
|
||||||
|
"accuracy": [
|
||||||
|
{
|
||||||
|
"username": "benjamina31",
|
||||||
|
"value": 94.4,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "loganm87",
|
||||||
|
"value": 93.4,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "williamh77",
|
||||||
|
"value": 90,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "logant84",
|
||||||
|
"value": 88.8,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "sophiaa25",
|
||||||
|
"value": 87.5,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "emmaa72",
|
||||||
|
"value": 86.7,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "jacobg47",
|
||||||
|
"value": 84.6,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "oliverb12",
|
||||||
|
"value": 81.7,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "student1",
|
||||||
|
"value": 79,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "admin1",
|
||||||
|
"value": 77.1,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "testuser",
|
||||||
|
"value": 77.1,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "nate",
|
||||||
|
"value": 76.3,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "ameliab34",
|
||||||
|
"value": 74.5,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "masonl4",
|
||||||
|
"value": 73.1,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"totalWords": [
|
||||||
|
{
|
||||||
|
"username": "nate",
|
||||||
|
"value": 1352,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "logant84",
|
||||||
|
"value": 966,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "williamh77",
|
||||||
|
"value": 846,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "oliverb12",
|
||||||
|
"value": 835,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "student1",
|
||||||
|
"value": 819,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "testuser",
|
||||||
|
"value": 761,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "ameliab34",
|
||||||
|
"value": 743,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "admin1",
|
||||||
|
"value": 724,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "masonl4",
|
||||||
|
"value": 530,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "sophiaa25",
|
||||||
|
"value": 419,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "benjamina31",
|
||||||
|
"value": 344,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "emmaa72",
|
||||||
|
"value": 304,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "loganm87",
|
||||||
|
"value": 252,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "jacobg47",
|
||||||
|
"value": 110,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"sessionsCompleted": [
|
||||||
|
{
|
||||||
|
"username": "nate",
|
||||||
|
"value": 129,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "student1",
|
||||||
|
"value": 80,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "admin1",
|
||||||
|
"value": 73,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "testuser",
|
||||||
|
"value": 71,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "logant84",
|
||||||
|
"value": 45,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "benjamina31",
|
||||||
|
"value": 41,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "jacobg47",
|
||||||
|
"value": 37,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "loganm87",
|
||||||
|
"value": 33,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "sophiaa25",
|
||||||
|
"value": 31,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "emmaa72",
|
||||||
|
"value": 28,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "masonl4",
|
||||||
|
"value": 22,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "williamh77",
|
||||||
|
"value": 21,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "ameliab34",
|
||||||
|
"value": 9,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "oliverb12",
|
||||||
|
"value": 7,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"streakDays": [
|
||||||
|
{
|
||||||
|
"username": "nate",
|
||||||
|
"value": 18,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "loganm87",
|
||||||
|
"value": 14,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "logant84",
|
||||||
|
"value": 12,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "benjamina31",
|
||||||
|
"value": 12,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "student1",
|
||||||
|
"value": 10,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "sophiaa25",
|
||||||
|
"value": 10,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "williamh77",
|
||||||
|
"value": 9,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "oliverb12",
|
||||||
|
"value": 8,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "testuser",
|
||||||
|
"value": 7,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "ameliab34",
|
||||||
|
"value": 7,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "admin1",
|
||||||
|
"value": 6,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "jacobg47",
|
||||||
|
"value": 2,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "emmaa72",
|
||||||
|
"value": 1,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "masonl4",
|
||||||
|
"value": 1,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
}
|
||||||
|
]
|
||||||
|
},
|
||||||
|
"weekly": {
|
||||||
|
"accuracy": [
|
||||||
|
{
|
||||||
|
"username": "benjamina31",
|
||||||
|
"value": 98.2,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "loganm87",
|
||||||
|
"value": 95.80000000000001,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "logant84",
|
||||||
|
"value": 89.8,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "emmaa72",
|
||||||
|
"value": 89.3,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "williamh77",
|
||||||
|
"value": 88.8,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "sophiaa25",
|
||||||
|
"value": 87.5,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "student1",
|
||||||
|
"value": 83.7,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "jacobg47",
|
||||||
|
"value": 81.19999999999999,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "oliverb12",
|
||||||
|
"value": 80.10000000000001,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "nate",
|
||||||
|
"value": 77.2,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "ameliab34",
|
||||||
|
"value": 76.9,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "masonl4",
|
||||||
|
"value": 75.39999999999999,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "testuser",
|
||||||
|
"value": 74.1,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "admin1",
|
||||||
|
"value": 73.19999999999999,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"totalWords": [
|
||||||
|
{
|
||||||
|
"username": "logant84",
|
||||||
|
"value": 53,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "masonl4",
|
||||||
|
"value": 52,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "oliverb12",
|
||||||
|
"value": 50,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "ameliab34",
|
||||||
|
"value": 40,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "admin1",
|
||||||
|
"value": 35,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "sophiaa25",
|
||||||
|
"value": 34,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "student1",
|
||||||
|
"value": 33,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "testuser",
|
||||||
|
"value": 32,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "benjamina31",
|
||||||
|
"value": 31,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "nate",
|
||||||
|
"value": 21,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "emmaa72",
|
||||||
|
"value": 19,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "loganm87",
|
||||||
|
"value": 17,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "williamh77",
|
||||||
|
"value": 15,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "jacobg47",
|
||||||
|
"value": 11,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.828Z"
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"sessionsCompleted": [
|
||||||
|
{
|
||||||
|
"username": "logant84",
|
||||||
|
"value": 7,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.829Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "admin1",
|
||||||
|
"value": 6,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.829Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "loganm87",
|
||||||
|
"value": 5,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.829Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "emmaa72",
|
||||||
|
"value": 5,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.829Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "jacobg47",
|
||||||
|
"value": 5,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.829Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "benjamina31",
|
||||||
|
"value": 5,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.829Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "masonl4",
|
||||||
|
"value": 4,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.829Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "williamh77",
|
||||||
|
"value": 3,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.829Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "nate",
|
||||||
|
"value": 2,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.829Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "student1",
|
||||||
|
"value": 2,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.829Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "sophiaa25",
|
||||||
|
"value": 2,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.829Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "testuser",
|
||||||
|
"value": 1,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.829Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "ameliab34",
|
||||||
|
"value": 1,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.829Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "oliverb12",
|
||||||
|
"value": 1,
|
||||||
|
"timestamp": "2025-08-13T16:18:54.829Z"
|
||||||
|
}
|
||||||
|
]
|
||||||
|
},
|
||||||
|
"currentWeek": "2025-3"
|
||||||
|
}
|
||||||
@@ -0,0 +1,551 @@
|
|||||||
|
{
|
||||||
|
"admin1": {
|
||||||
|
"streak": {
|
||||||
|
"current": 5,
|
||||||
|
"longest": 11,
|
||||||
|
"lastPractice": "2025-08-12"
|
||||||
|
},
|
||||||
|
"points": 1017,
|
||||||
|
"level": 3,
|
||||||
|
"dailyChallenges": [
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-13",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-12",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-12",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-streak-3",
|
||||||
|
"date": "2025-08-12",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-10",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-09",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-09",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-streak-3",
|
||||||
|
"date": "2025-08-09",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-08",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-08",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-streak-3",
|
||||||
|
"date": "2025-08-08",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-07",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-07",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-streak-3",
|
||||||
|
"date": "2025-08-07",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-06",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-06",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-streak-3",
|
||||||
|
"date": "2025-08-06",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-05",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-05",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-04",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-04",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-02",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-07-31",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-07-31",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-streak-3",
|
||||||
|
"date": "2025-07-31",
|
||||||
|
"progress": 1
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"weeklyChallenges": [
|
||||||
|
{
|
||||||
|
"id": "weekly-days-5",
|
||||||
|
"weekStart": "2025-07-30",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "weekly-words-50",
|
||||||
|
"weekStart": "2025-07-23",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "weekly-days-5",
|
||||||
|
"weekStart": "2025-07-16",
|
||||||
|
"progress": 1
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"achievements": [
|
||||||
|
{
|
||||||
|
"id": "achievement-words-100",
|
||||||
|
"date": "2025-07-22",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "achievement-words-500",
|
||||||
|
"date": "2025-08-01",
|
||||||
|
"progress": 1
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"stats": {
|
||||||
|
"wordsAttempted": 574,
|
||||||
|
"wordsCorrect": 415.86,
|
||||||
|
"sessionsCompleted": 69,
|
||||||
|
"averageAccuracy": 0.9
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"nate": {
|
||||||
|
"streak": {
|
||||||
|
"current": 2,
|
||||||
|
"longest": 12,
|
||||||
|
"lastPractice": "2025-08-12"
|
||||||
|
},
|
||||||
|
"points": 543,
|
||||||
|
"level": 2,
|
||||||
|
"dailyChallenges": [
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-13",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-13",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-11",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-11",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-09",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-09",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-07",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-07",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-06",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-05",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-05",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-04",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-04",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-streak-3",
|
||||||
|
"date": "2025-08-04",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-03",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-03",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-02",
|
||||||
|
"progress": 1
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"weeklyChallenges": [
|
||||||
|
{
|
||||||
|
"id": "weekly-words-50",
|
||||||
|
"weekStart": "2025-07-23",
|
||||||
|
"progress": 1
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"achievements": [
|
||||||
|
{
|
||||||
|
"id": "achievement-words-100",
|
||||||
|
"date": "2025-08-01",
|
||||||
|
"progress": 1
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"stats": {
|
||||||
|
"wordsAttempted": 817,
|
||||||
|
"wordsCorrect": 317.68,
|
||||||
|
"sessionsCompleted": 79,
|
||||||
|
"averageAccuracy": 0.95
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"student1": {
|
||||||
|
"streak": {
|
||||||
|
"current": 6,
|
||||||
|
"longest": 9,
|
||||||
|
"lastPractice": "2025-08-12"
|
||||||
|
},
|
||||||
|
"points": 574,
|
||||||
|
"level": 2,
|
||||||
|
"dailyChallenges": [
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-13",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-12",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-12",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-11",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-11",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-10",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-06",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-06",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-05",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-05",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-04",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-04",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-streak-3",
|
||||||
|
"date": "2025-08-04",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-03",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-02",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-01",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-01",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-07-31",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-07-31",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-streak-3",
|
||||||
|
"date": "2025-07-31",
|
||||||
|
"progress": 1
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"weeklyChallenges": [
|
||||||
|
{
|
||||||
|
"id": "weekly-words-50",
|
||||||
|
"weekStart": "2025-08-06",
|
||||||
|
"progress": 1
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"achievements": [
|
||||||
|
{
|
||||||
|
"id": "achievement-words-100",
|
||||||
|
"date": "2025-07-23",
|
||||||
|
"progress": 1
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"stats": {
|
||||||
|
"wordsAttempted": 102,
|
||||||
|
"wordsCorrect": 648.1800000000001,
|
||||||
|
"sessionsCompleted": 65,
|
||||||
|
"averageAccuracy": 0.78
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"testuser": {
|
||||||
|
"streak": {
|
||||||
|
"current": 13,
|
||||||
|
"longest": 20,
|
||||||
|
"lastPractice": "2025-08-12"
|
||||||
|
},
|
||||||
|
"points": 843,
|
||||||
|
"level": 2,
|
||||||
|
"dailyChallenges": [
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-13",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-13",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-12",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-11",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-11",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-streak-3",
|
||||||
|
"date": "2025-08-11",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-09",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-09",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-08",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-07",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-06",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-06",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-05",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-04",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-02",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-practice-10",
|
||||||
|
"date": "2025-08-01",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-accuracy-90",
|
||||||
|
"date": "2025-08-01",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "daily-streak-3",
|
||||||
|
"date": "2025-08-01",
|
||||||
|
"progress": 1
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"weeklyChallenges": [
|
||||||
|
{
|
||||||
|
"id": "weekly-words-50",
|
||||||
|
"weekStart": "2025-08-06",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "weekly-words-50",
|
||||||
|
"weekStart": "2025-07-30",
|
||||||
|
"progress": 1
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"achievements": [
|
||||||
|
{
|
||||||
|
"id": "achievement-words-100",
|
||||||
|
"date": "2025-08-03",
|
||||||
|
"progress": 1
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"id": "achievement-words-500",
|
||||||
|
"date": "2025-07-18",
|
||||||
|
"progress": 1
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"stats": {
|
||||||
|
"wordsAttempted": 353,
|
||||||
|
"wordsCorrect": 789.4499999999999,
|
||||||
|
"sessionsCompleted": 87,
|
||||||
|
"averageAccuracy": 0.88
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
@@ -0,0 +1,76 @@
|
|||||||
|
{
|
||||||
|
"admin1": [
|
||||||
|
{
|
||||||
|
"answers": [
|
||||||
|
{
|
||||||
|
"word": "example",
|
||||||
|
"correct": true
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"word": "test",
|
||||||
|
"correct": true
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"timestamp": "2025-08-13T18:38:39.3537417-04:00",
|
||||||
|
"score": 100
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"student1": [],
|
||||||
|
"nate": [],
|
||||||
|
"testuser": [
|
||||||
|
{
|
||||||
|
"score": 85,
|
||||||
|
"completed": true,
|
||||||
|
"answers": [
|
||||||
|
{
|
||||||
|
"word": "apple",
|
||||||
|
"correct": true
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"word": "banana",
|
||||||
|
"correct": true
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"word": "cherry",
|
||||||
|
"correct": true
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"word": "difficult",
|
||||||
|
"correct": false
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"word": "elephant",
|
||||||
|
"correct": true
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"timestamp": "2025-08-13T22:55:01.443Z"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"score": 90,
|
||||||
|
"completed": true,
|
||||||
|
"answers": [
|
||||||
|
{
|
||||||
|
"word": "apple",
|
||||||
|
"correct": true
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"word": "banana",
|
||||||
|
"correct": true
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"word": "cherry",
|
||||||
|
"correct": true
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"word": "difficult",
|
||||||
|
"correct": false
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"word": "elephant",
|
||||||
|
"correct": true
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"timestamp": "2025-08-13T22:55:32.631Z"
|
||||||
|
}
|
||||||
|
]
|
||||||
|
}
|
||||||
+18008
File diff suppressed because it is too large.
Load diff
@@ -0,0 +1,300 @@
|
|||||||
|
{
|
||||||
|
"nate": {
|
||||||
|
"settings": {
|
||||||
|
"dailyLimit": 20,
|
||||||
|
"reviewThreshold": 3,
|
||||||
|
"newWordsPerDay": 5
|
||||||
|
},
|
||||||
|
"stats": {
|
||||||
|
"totalReviews": 15,
|
||||||
|
"correctReviews": 9,
|
||||||
|
"totalWords": 6,
|
||||||
|
"masteredWords": 0
|
||||||
|
},
|
||||||
|
"words": {
|
||||||
|
"computer": {
|
||||||
|
"easeFactor": 2.5,
|
||||||
|
"interval": 3,
|
||||||
|
"repetitions": 3,
|
||||||
|
"lastReview": "2025-08-10",
|
||||||
|
"nextReview": "2025-08-13"
|
||||||
|
},
|
||||||
|
"keyboard": {
|
||||||
|
"easeFactor": 2.3,
|
||||||
|
"interval": 2,
|
||||||
|
"repetitions": 2,
|
||||||
|
"lastReview": "2025-08-11",
|
||||||
|
"nextReview": "2025-08-13"
|
||||||
|
},
|
||||||
|
"mouse": {
|
||||||
|
"easeFactor": 2.8,
|
||||||
|
"interval": 4,
|
||||||
|
"repetitions": 4,
|
||||||
|
"lastReview": "2025-08-09",
|
||||||
|
"nextReview": "2025-08-13"
|
||||||
|
},
|
||||||
|
"screen": {
|
||||||
|
"easeFactor": 3,
|
||||||
|
"interval": 6,
|
||||||
|
"repetitions": 5,
|
||||||
|
"lastReview": "2025-08-07",
|
||||||
|
"nextReview": "2025-08-13"
|
||||||
|
},
|
||||||
|
"printer": {
|
||||||
|
"easeFactor": 2.2,
|
||||||
|
"interval": 1,
|
||||||
|
"repetitions": 1,
|
||||||
|
"lastReview": "2025-08-12",
|
||||||
|
"nextReview": "2025-08-13"
|
||||||
|
},
|
||||||
|
"not": {
|
||||||
|
"easeFactor": 2.6,
|
||||||
|
"interval": 7,
|
||||||
|
"repetitions": 3,
|
||||||
|
"lastReview": "2025-08-12",
|
||||||
|
"nextReview": "2025-08-20"
|
||||||
|
},
|
||||||
|
"bot": {
|
||||||
|
"easeFactor": 2.8,
|
||||||
|
"interval": 15,
|
||||||
|
"repetitions": 4,
|
||||||
|
"lastReview": "2025-08-05",
|
||||||
|
"nextReview": "2025-08-14"
|
||||||
|
},
|
||||||
|
"snot": {
|
||||||
|
"easeFactor": 2.2,
|
||||||
|
"interval": 1,
|
||||||
|
"repetitions": 1,
|
||||||
|
"lastReview": "2025-08-12",
|
||||||
|
"nextReview": "2025-08-14"
|
||||||
|
},
|
||||||
|
"bate": {
|
||||||
|
"easeFactor": 2.1,
|
||||||
|
"interval": 1,
|
||||||
|
"repetitions": 1,
|
||||||
|
"lastReview": "2025-08-12",
|
||||||
|
"nextReview": "2025-08-14"
|
||||||
|
},
|
||||||
|
"hate": {
|
||||||
|
"easeFactor": 2.2,
|
||||||
|
"interval": 3,
|
||||||
|
"repetitions": 2,
|
||||||
|
"lastReview": "2025-08-10",
|
||||||
|
"nextReview": "2025-08-15"
|
||||||
|
},
|
||||||
|
"late": {
|
||||||
|
"easeFactor": 2.5,
|
||||||
|
"interval": 15,
|
||||||
|
"repetitions": 4,
|
||||||
|
"lastReview": "2025-08-11",
|
||||||
|
"nextReview": "2025-08-11"
|
||||||
|
}
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"student1": {
|
||||||
|
"settings": {
|
||||||
|
"dailyLimit": 20,
|
||||||
|
"reviewThreshold": 3,
|
||||||
|
"newWordsPerDay": 5
|
||||||
|
},
|
||||||
|
"stats": {
|
||||||
|
"totalReviews": 10,
|
||||||
|
"correctReviews": 5,
|
||||||
|
"totalWords": 5,
|
||||||
|
"masteredWords": 0
|
||||||
|
},
|
||||||
|
"words": {
|
||||||
|
"apple": {
|
||||||
|
"easeFactor": 2.2,
|
||||||
|
"interval": 3,
|
||||||
|
"repetitions": 2,
|
||||||
|
"lastReview": "2025-08-10",
|
||||||
|
"nextReview": "2025-08-10"
|
||||||
|
},
|
||||||
|
"banana": {
|
||||||
|
"easeFactor": 2.1,
|
||||||
|
"interval": 1,
|
||||||
|
"repetitions": 1,
|
||||||
|
"lastReview": "2025-08-12",
|
||||||
|
"nextReview": "2025-08-14"
|
||||||
|
},
|
||||||
|
"cherry": {
|
||||||
|
"easeFactor": 2.4,
|
||||||
|
"interval": 3,
|
||||||
|
"repetitions": 2,
|
||||||
|
"lastReview": "2025-08-11",
|
||||||
|
"nextReview": "2025-08-16"
|
||||||
|
},
|
||||||
|
"date": {
|
||||||
|
"easeFactor": 2.5,
|
||||||
|
"interval": 1,
|
||||||
|
"repetitions": 1,
|
||||||
|
"lastReview": "2025-08-12",
|
||||||
|
"nextReview": "2025-08-13"
|
||||||
|
},
|
||||||
|
"elderberry": {
|
||||||
|
"easeFactor": 2.3,
|
||||||
|
"interval": 15,
|
||||||
|
"repetitions": 4,
|
||||||
|
"lastReview": "2025-08-11",
|
||||||
|
"nextReview": "2025-08-11"
|
||||||
|
}
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"admin1": {
|
||||||
|
"settings": {
|
||||||
|
"dailyLimit": 20,
|
||||||
|
"reviewThreshold": 3,
|
||||||
|
"newWordsPerDay": 5
|
||||||
|
},
|
||||||
|
"stats": {
|
||||||
|
"totalReviews": 12,
|
||||||
|
"correctReviews": 9,
|
||||||
|
"totalWords": 3,
|
||||||
|
"masteredWords": 1
|
||||||
|
},
|
||||||
|
"words": {
|
||||||
|
"administration": {
|
||||||
|
"easeFactor": 2.5,
|
||||||
|
"interval": 3,
|
||||||
|
"repetitions": 3,
|
||||||
|
"lastReview": "2025-08-10",
|
||||||
|
"nextReview": "2025-08-13"
|
||||||
|
},
|
||||||
|
"education": {
|
||||||
|
"easeFactor": 2.8,
|
||||||
|
"interval": 4,
|
||||||
|
"repetitions": 4,
|
||||||
|
"lastReview": "2025-08-09",
|
||||||
|
"nextReview": "2025-08-13"
|
||||||
|
},
|
||||||
|
"technology": {
|
||||||
|
"easeFactor": 2.3,
|
||||||
|
"interval": 2,
|
||||||
|
"repetitions": 2,
|
||||||
|
"lastReview": "2025-08-11",
|
||||||
|
"nextReview": "2025-08-13"
|
||||||
|
},
|
||||||
|
"development": {
|
||||||
|
"easeFactor": 3,
|
||||||
|
"interval": 6,
|
||||||
|
"repetitions": 5,
|
||||||
|
"lastReview": "2025-08-07",
|
||||||
|
"nextReview": "2025-08-13"
|
||||||
|
},
|
||||||
|
"programming": {
|
||||||
|
"easeFactor": 3,
|
||||||
|
"interval": 6,
|
||||||
|
"repetitions": 5,
|
||||||
|
"lastReview": "2025-08-07",
|
||||||
|
"nextReview": "2025-08-13"
|
||||||
|
},
|
||||||
|
"boy": {
|
||||||
|
"easeFactor": 2.7,
|
||||||
|
"interval": 15,
|
||||||
|
"repetitions": 4,
|
||||||
|
"lastReview": "2025-08-09",
|
||||||
|
"nextReview": "2025-08-20"
|
||||||
|
},
|
||||||
|
"bot": {
|
||||||
|
"easeFactor": 2.6,
|
||||||
|
"interval": 40,
|
||||||
|
"repetitions": 6,
|
||||||
|
"lastReview": "2025-07-23",
|
||||||
|
"nextReview": "2025-08-25"
|
||||||
|
},
|
||||||
|
"snot": {
|
||||||
|
"easeFactor": 2.4,
|
||||||
|
"interval": 3,
|
||||||
|
"repetitions": 2,
|
||||||
|
"lastReview": "2025-08-10",
|
||||||
|
"nextReview": "2025-08-10"
|
||||||
|
}
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"testuser": {
|
||||||
|
"settings": {
|
||||||
|
"dailyLimit": 20,
|
||||||
|
"reviewThreshold": 3,
|
||||||
|
"newWordsPerDay": 5
|
||||||
|
},
|
||||||
|
"stats": {
|
||||||
|
"totalReviews": 32,
|
||||||
|
"correctReviews": 23,
|
||||||
|
"totalWords": 10,
|
||||||
|
"masteredWords": 3
|
||||||
|
},
|
||||||
|
"words": {
|
||||||
|
"hello": {
|
||||||
|
"easeFactor": 2.4,
|
||||||
|
"interval": 7,
|
||||||
|
"repetitions": 3,
|
||||||
|
"lastReview": "2025-08-07",
|
||||||
|
"nextReview": "2025-08-14"
|
||||||
|
},
|
||||||
|
"world": {
|
||||||
|
"easeFactor": 2.2,
|
||||||
|
"interval": 3,
|
||||||
|
"repetitions": 2,
|
||||||
|
"lastReview": "2025-08-10",
|
||||||
|
"nextReview": "2025-08-14"
|
||||||
|
},
|
||||||
|
"test": {
|
||||||
|
"easeFactor": 2.2,
|
||||||
|
"interval": 7,
|
||||||
|
"repetitions": 3,
|
||||||
|
"lastReview": "2025-08-08",
|
||||||
|
"nextReview": "2025-08-14"
|
||||||
|
},
|
||||||
|
"sample": {
|
||||||
|
"easeFactor": 2.2,
|
||||||
|
"interval": 3,
|
||||||
|
"repetitions": 2,
|
||||||
|
"lastReview": "2025-08-11",
|
||||||
|
"nextReview": "2025-08-16"
|
||||||
|
},
|
||||||
|
"basic": {
|
||||||
|
"easeFactor": 2.7,
|
||||||
|
"interval": 40,
|
||||||
|
"repetitions": 6,
|
||||||
|
"lastReview": "2025-08-03",
|
||||||
|
"nextReview": "2025-08-14"
|
||||||
|
},
|
||||||
|
"learn": {
|
||||||
|
"easeFactor": 2.4,
|
||||||
|
"interval": 0,
|
||||||
|
"repetitions": 0,
|
||||||
|
"lastReview": null,
|
||||||
|
"nextReview": "2025-08-13"
|
||||||
|
},
|
||||||
|
"spell": {
|
||||||
|
"easeFactor": 2.2,
|
||||||
|
"interval": 1,
|
||||||
|
"repetitions": 1,
|
||||||
|
"lastReview": "2025-08-12",
|
||||||
|
"nextReview": "2025-08-14"
|
||||||
|
},
|
||||||
|
"word": {
|
||||||
|
"easeFactor": 2.9,
|
||||||
|
"interval": 20,
|
||||||
|
"repetitions": 5,
|
||||||
|
"lastReview": "2025-07-27",
|
||||||
|
"nextReview": "2025-08-27"
|
||||||
|
},
|
||||||
|
"study": {
|
||||||
|
"easeFactor": 2.4,
|
||||||
|
"interval": 7,
|
||||||
|
"repetitions": 3,
|
||||||
|
"lastReview": "2025-08-08",
|
||||||
|
"nextReview": "2025-08-14"
|
||||||
|
},
|
||||||
|
"practice": {
|
||||||
|
"easeFactor": 2.8,
|
||||||
|
"interval": 80,
|
||||||
|
"repetitions": 7,
|
||||||
|
"lastReview": "2025-07-06",
|
||||||
|
"nextReview": "2025-08-14"
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
@@ -0,0 +1,22 @@
|
|||||||
|
[
|
||||||
|
{
|
||||||
|
"username": "admin1",
|
||||||
|
"hash": "5e884898da28047151d0e56f8dc6292773603d0d6aabbdd62a11ef721d1542d8",
|
||||||
|
"role": "admin"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "nate",
|
||||||
|
"hash": "5a2a558c78d3717db731600c4f354fa1d9c84b556f108091a891f444f1bdec40",
|
||||||
|
"role": "student"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "student1",
|
||||||
|
"hash": "8d969eef6ecad3c29a3a629280e686cf0c3f5d5a86aff3ca12020c923adc6c92",
|
||||||
|
"role": "student"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "testuser",
|
||||||
|
"hash": "e3b0c44298fc1c149afbf4c8996fb92427ae41e4649b934ca495991b7852b855",
|
||||||
|
"role": "student"
|
||||||
|
}
|
||||||
|
]
|
||||||
@@ -0,0 +1,47 @@
|
|||||||
|
{
|
||||||
|
"student1": [
|
||||||
|
"apple",
|
||||||
|
"banana",
|
||||||
|
"cherry",
|
||||||
|
"date",
|
||||||
|
"elderberry"
|
||||||
|
],
|
||||||
|
"admin1": [
|
||||||
|
"boy",
|
||||||
|
"bot",
|
||||||
|
"snot"
|
||||||
|
],
|
||||||
|
"nate": {
|
||||||
|
"weeks": [
|
||||||
|
{
|
||||||
|
"date": "2025-08-03",
|
||||||
|
"words": [
|
||||||
|
"not",
|
||||||
|
"bot",
|
||||||
|
"snot"
|
||||||
|
]
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"date": "2025-08-10",
|
||||||
|
"words": [
|
||||||
|
"bate",
|
||||||
|
"hate",
|
||||||
|
"late"
|
||||||
|
]
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"activeWeek": "2025-08-10"
|
||||||
|
},
|
||||||
|
"testuser": [
|
||||||
|
"hello",
|
||||||
|
"world",
|
||||||
|
"test",
|
||||||
|
"sample",
|
||||||
|
"basic",
|
||||||
|
"learn",
|
||||||
|
"spell",
|
||||||
|
"word",
|
||||||
|
"study",
|
||||||
|
"practice"
|
||||||
|
]
|
||||||
|
}
|
||||||
@@ -1,299 +0,0 @@
|
|||||||
import { DatabaseSync } from 'node:sqlite';
|
|
||||||
import { createHash } from 'node:crypto';
|
|
||||||
import { mkdirSync, readFileSync } from 'node:fs';
|
|
||||||
import { join, dirname } from 'node:path';
|
|
||||||
import { fileURLToPath } from 'node:url';
|
|
||||||
|
|
||||||
const ROOT = dirname(fileURLToPath(import.meta.url));
|
|
||||||
const DATA_DIR = process.env.DATA_DIR || join(ROOT, 'data');
|
|
||||||
mkdirSync(DATA_DIR, { recursive: true });
|
|
||||||
|
|
||||||
export const db = new DatabaseSync(join(DATA_DIR, 'spelling.db'));
|
|
||||||
|
|
||||||
db.exec(`
|
|
||||||
PRAGMA journal_mode = WAL;
|
|
||||||
PRAGMA foreign_keys = ON;
|
|
||||||
|
|
||||||
CREATE TABLE IF NOT EXISTS students (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
name TEXT NOT NULL,
|
|
||||||
emoji TEXT NOT NULL DEFAULT '🙂',
|
|
||||||
created_at TEXT NOT NULL DEFAULT (datetime('now'))
|
|
||||||
);
|
|
||||||
|
|
||||||
CREATE TABLE IF NOT EXISTS lists (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
name TEXT NOT NULL,
|
|
||||||
builtin INTEGER NOT NULL DEFAULT 0
|
|
||||||
);
|
|
||||||
|
|
||||||
CREATE TABLE IF NOT EXISTS words (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
list_id INTEGER NOT NULL REFERENCES lists(id) ON DELETE CASCADE,
|
|
||||||
word TEXT NOT NULL,
|
|
||||||
sentence TEXT NOT NULL DEFAULT ''
|
|
||||||
);
|
|
||||||
|
|
||||||
-- one active weekly assignment per student
|
|
||||||
CREATE TABLE IF NOT EXISTS assignments (
|
|
||||||
student_id INTEGER PRIMARY KEY REFERENCES students(id) ON DELETE CASCADE,
|
|
||||||
list_id INTEGER NOT NULL REFERENCES lists(id) ON DELETE CASCADE,
|
|
||||||
assigned_at TEXT NOT NULL DEFAULT (datetime('now'))
|
|
||||||
);
|
|
||||||
|
|
||||||
-- Leitner state per student per word. box 0 = new, 5 = mastered.
|
|
||||||
CREATE TABLE IF NOT EXISTS progress (
|
|
||||||
student_id INTEGER NOT NULL REFERENCES students(id) ON DELETE CASCADE,
|
|
||||||
word_id INTEGER NOT NULL REFERENCES words(id) ON DELETE CASCADE,
|
|
||||||
box INTEGER NOT NULL DEFAULT 0,
|
|
||||||
due TEXT NOT NULL DEFAULT (date('now')),
|
|
||||||
attempts INTEGER NOT NULL DEFAULT 0,
|
|
||||||
correct INTEGER NOT NULL DEFAULT 0,
|
|
||||||
PRIMARY KEY (student_id, word_id)
|
|
||||||
);
|
|
||||||
|
|
||||||
CREATE TABLE IF NOT EXISTS attempts (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
student_id INTEGER NOT NULL REFERENCES students(id) ON DELETE CASCADE,
|
|
||||||
word_id INTEGER NOT NULL REFERENCES words(id) ON DELETE CASCADE,
|
|
||||||
typed TEXT NOT NULL,
|
|
||||||
correct INTEGER NOT NULL,
|
|
||||||
mode TEXT NOT NULL,
|
|
||||||
at TEXT NOT NULL DEFAULT (datetime('now'))
|
|
||||||
);
|
|
||||||
|
|
||||||
CREATE TABLE IF NOT EXISTS tests (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
student_id INTEGER NOT NULL REFERENCES students(id) ON DELETE CASCADE,
|
|
||||||
list_id INTEGER NOT NULL REFERENCES lists(id) ON DELETE CASCADE,
|
|
||||||
score INTEGER NOT NULL,
|
|
||||||
total INTEGER NOT NULL,
|
|
||||||
at TEXT NOT NULL DEFAULT (datetime('now'))
|
|
||||||
);
|
|
||||||
|
|
||||||
CREATE TABLE IF NOT EXISTS test_answers (
|
|
||||||
test_id INTEGER NOT NULL REFERENCES tests(id) ON DELETE CASCADE,
|
|
||||||
word_id INTEGER NOT NULL REFERENCES words(id) ON DELETE CASCADE,
|
|
||||||
typed TEXT NOT NULL,
|
|
||||||
correct INTEGER NOT NULL
|
|
||||||
);
|
|
||||||
|
|
||||||
CREATE TABLE IF NOT EXISTS settings (
|
|
||||||
key TEXT PRIMARY KEY,
|
|
||||||
value TEXT NOT NULL
|
|
||||||
);
|
|
||||||
|
|
||||||
-- flashcards module
|
|
||||||
CREATE TABLE IF NOT EXISTS decks (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
name TEXT NOT NULL,
|
|
||||||
builtin INTEGER NOT NULL DEFAULT 0
|
|
||||||
);
|
|
||||||
|
|
||||||
CREATE TABLE IF NOT EXISTS cards (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
deck_id INTEGER NOT NULL REFERENCES decks(id) ON DELETE CASCADE,
|
|
||||||
front TEXT NOT NULL,
|
|
||||||
back TEXT NOT NULL
|
|
||||||
);
|
|
||||||
|
|
||||||
CREATE TABLE IF NOT EXISTS card_progress (
|
|
||||||
student_id INTEGER NOT NULL REFERENCES students(id) ON DELETE CASCADE,
|
|
||||||
card_id INTEGER NOT NULL REFERENCES cards(id) ON DELETE CASCADE,
|
|
||||||
box INTEGER NOT NULL DEFAULT 0,
|
|
||||||
due TEXT NOT NULL DEFAULT (date('now')),
|
|
||||||
attempts INTEGER NOT NULL DEFAULT 0,
|
|
||||||
correct INTEGER NOT NULL DEFAULT 0,
|
|
||||||
PRIMARY KEY (student_id, card_id)
|
|
||||||
);
|
|
||||||
|
|
||||||
-- ---------- LMS layer ----------
|
|
||||||
|
|
||||||
CREATE TABLE IF NOT EXISTS courses (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
name TEXT NOT NULL,
|
|
||||||
subject TEXT NOT NULL DEFAULT '',
|
|
||||||
color TEXT NOT NULL DEFAULT '#4f86f7',
|
|
||||||
archived INTEGER NOT NULL DEFAULT 0
|
|
||||||
);
|
|
||||||
|
|
||||||
CREATE TABLE IF NOT EXISTS enrollments (
|
|
||||||
student_id INTEGER NOT NULL REFERENCES students(id) ON DELETE CASCADE,
|
|
||||||
course_id INTEGER NOT NULL REFERENCES courses(id) ON DELETE CASCADE,
|
|
||||||
PRIMARY KEY (student_id, course_id)
|
|
||||||
);
|
|
||||||
|
|
||||||
CREATE TABLE IF NOT EXISTS units (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
course_id INTEGER NOT NULL REFERENCES courses(id) ON DELETE CASCADE,
|
|
||||||
name TEXT NOT NULL,
|
|
||||||
sort INTEGER NOT NULL DEFAULT 0
|
|
||||||
);
|
|
||||||
|
|
||||||
-- type: lesson | assignment | quiz | spelling_practice | spelling_test | flashcards
|
|
||||||
-- ref_id: list_id for spelling_*, deck_id for flashcards. points: max score for assignment/quiz.
|
|
||||||
CREATE TABLE IF NOT EXISTS items (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
unit_id INTEGER NOT NULL REFERENCES units(id) ON DELETE CASCADE,
|
|
||||||
type TEXT NOT NULL,
|
|
||||||
title TEXT NOT NULL,
|
|
||||||
body TEXT NOT NULL DEFAULT '',
|
|
||||||
points INTEGER NOT NULL DEFAULT 0,
|
|
||||||
ref_id INTEGER,
|
|
||||||
sort INTEGER NOT NULL DEFAULT 0
|
|
||||||
);
|
|
||||||
|
|
||||||
-- type: mc | tf | short
|
|
||||||
CREATE TABLE IF NOT EXISTS quiz_questions (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
item_id INTEGER NOT NULL REFERENCES items(id) ON DELETE CASCADE,
|
|
||||||
type TEXT NOT NULL,
|
|
||||||
prompt TEXT NOT NULL,
|
|
||||||
choices TEXT NOT NULL DEFAULT '[]',
|
|
||||||
correct_answer TEXT NOT NULL,
|
|
||||||
points INTEGER NOT NULL DEFAULT 1,
|
|
||||||
sort INTEGER NOT NULL DEFAULT 0
|
|
||||||
);
|
|
||||||
|
|
||||||
-- one row per student per item. status: done (ungraded) | graded
|
|
||||||
CREATE TABLE IF NOT EXISTS submissions (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
student_id INTEGER NOT NULL REFERENCES students(id) ON DELETE CASCADE,
|
|
||||||
item_id INTEGER NOT NULL REFERENCES items(id) ON DELETE CASCADE,
|
|
||||||
status TEXT NOT NULL DEFAULT 'done',
|
|
||||||
score REAL,
|
|
||||||
points_possible REAL,
|
|
||||||
answers TEXT,
|
|
||||||
completed_at TEXT NOT NULL DEFAULT (datetime('now')),
|
|
||||||
graded_at TEXT,
|
|
||||||
UNIQUE(student_id, item_id)
|
|
||||||
);
|
|
||||||
|
|
||||||
-- daily agenda. item_id set = a scheduled course item; null = a standalone offline task (title used)
|
|
||||||
CREATE TABLE IF NOT EXISTS schedule (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
student_id INTEGER NOT NULL REFERENCES students(id) ON DELETE CASCADE,
|
|
||||||
date TEXT NOT NULL,
|
|
||||||
item_id INTEGER REFERENCES items(id) ON DELETE CASCADE,
|
|
||||||
title TEXT NOT NULL DEFAULT '',
|
|
||||||
done INTEGER NOT NULL DEFAULT 0,
|
|
||||||
done_at TEXT,
|
|
||||||
sort INTEGER NOT NULL DEFAULT 0
|
|
||||||
);
|
|
||||||
CREATE INDEX IF NOT EXISTS idx_schedule_day ON schedule(student_id, date);
|
|
||||||
|
|
||||||
CREATE TABLE IF NOT EXISTS quiz_templates (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
name TEXT NOT NULL,
|
|
||||||
created_at TEXT NOT NULL DEFAULT (datetime('now'))
|
|
||||||
);
|
|
||||||
CREATE TABLE IF NOT EXISTS quiz_template_questions (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
template_id INTEGER NOT NULL REFERENCES quiz_templates(id) ON DELETE CASCADE,
|
|
||||||
type TEXT NOT NULL,
|
|
||||||
prompt TEXT NOT NULL,
|
|
||||||
choices TEXT NOT NULL DEFAULT '[]',
|
|
||||||
correct_answer TEXT NOT NULL,
|
|
||||||
points INTEGER NOT NULL DEFAULT 1,
|
|
||||||
sort INTEGER NOT NULL DEFAULT 0
|
|
||||||
);
|
|
||||||
CREATE TABLE IF NOT EXISTS submission_history (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
student_id INTEGER NOT NULL REFERENCES students(id) ON DELETE CASCADE,
|
|
||||||
item_id INTEGER NOT NULL REFERENCES items(id) ON DELETE CASCADE,
|
|
||||||
score REAL,
|
|
||||||
points_possible REAL,
|
|
||||||
answers TEXT,
|
|
||||||
completed_at TEXT NOT NULL DEFAULT (datetime('now'))
|
|
||||||
);
|
|
||||||
|
|
||||||
CREATE TABLE IF NOT EXISTS messages (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
student_id INTEGER NOT NULL REFERENCES students(id) ON DELETE CASCADE,
|
|
||||||
sender TEXT NOT NULL,
|
|
||||||
body TEXT NOT NULL,
|
|
||||||
sent_at TEXT NOT NULL DEFAULT (datetime('now')),
|
|
||||||
read_at TEXT
|
|
||||||
);
|
|
||||||
`);
|
|
||||||
|
|
||||||
function tryAlter(sql) {
|
|
||||||
try { db.exec(sql); } catch { /* column already exists */ }
|
|
||||||
}
|
|
||||||
tryAlter(`ALTER TABLE items ADD COLUMN due_date TEXT`);
|
|
||||||
tryAlter(`ALTER TABLE items ADD COLUMN allow_retakes INTEGER NOT NULL DEFAULT 0`);
|
|
||||||
tryAlter(`ALTER TABLE items ADD COLUMN prereq_item_id INTEGER`);
|
|
||||||
tryAlter(`ALTER TABLE items ADD COLUMN evidence_mode TEXT NOT NULL DEFAULT 'none'`);
|
|
||||||
tryAlter(`ALTER TABLE items ADD COLUMN retake_policy TEXT NOT NULL DEFAULT 'latest'`);
|
|
||||||
tryAlter(`ALTER TABLE submissions ADD COLUMN evidence_notes TEXT`);
|
|
||||||
tryAlter(`ALTER TABLE submissions ADD COLUMN evidence_photo TEXT`);
|
|
||||||
tryAlter(`ALTER TABLE submissions ADD COLUMN student_note TEXT`);
|
|
||||||
tryAlter(`ALTER TABLE submissions ADD COLUMN parent_comment TEXT`);
|
|
||||||
tryAlter(`ALTER TABLE schedule ADD COLUMN status TEXT NOT NULL DEFAULT 'not_started'`);
|
|
||||||
tryAlter(`ALTER TABLE schedule ADD COLUMN evidence_notes TEXT`);
|
|
||||||
tryAlter(`ALTER TABLE words ADD COLUMN definition TEXT NOT NULL DEFAULT ''`);
|
|
||||||
tryAlter(`ALTER TABLE schedule ADD COLUMN evidence_photo TEXT`);
|
|
||||||
tryAlter(`ALTER TABLE students ADD COLUMN theme TEXT NOT NULL DEFAULT 'blue'`);
|
|
||||||
tryAlter(`ALTER TABLE students ADD COLUMN streak_date TEXT`);
|
|
||||||
tryAlter(`ALTER TABLE students ADD COLUMN streak_count INTEGER NOT NULL DEFAULT 0`);
|
|
||||||
tryAlter(`ALTER TABLE students ADD COLUMN best_streak INTEGER NOT NULL DEFAULT 0`);
|
|
||||||
tryAlter(`ALTER TABLE students ADD COLUMN bg_pattern TEXT NOT NULL DEFAULT 'none'`);
|
|
||||||
tryAlter(`ALTER TABLE students ADD COLUMN young_learner INTEGER NOT NULL DEFAULT 0`);
|
|
||||||
tryAlter(`ALTER TABLE students ADD COLUMN birthday TEXT`);
|
|
||||||
tryAlter(`ALTER TABLE lists ADD COLUMN group_name TEXT NOT NULL DEFAULT ''`);
|
|
||||||
tryAlter(`ALTER TABLE decks ADD COLUMN group_name TEXT NOT NULL DEFAULT ''`);
|
|
||||||
tryAlter(`ALTER TABLE tests ADD COLUMN item_id INTEGER`);
|
|
||||||
|
|
||||||
db.exec(`CREATE TABLE IF NOT EXISTS documents (
|
|
||||||
id INTEGER PRIMARY KEY,
|
|
||||||
student_id INTEGER NOT NULL REFERENCES students(id) ON DELETE CASCADE,
|
|
||||||
title TEXT NOT NULL DEFAULT 'Untitled Document',
|
|
||||||
doc_key TEXT NOT NULL UNIQUE,
|
|
||||||
filename TEXT NOT NULL,
|
|
||||||
submitted INTEGER NOT NULL DEFAULT 0,
|
|
||||||
submitted_at TEXT,
|
|
||||||
parent_read INTEGER NOT NULL DEFAULT 0,
|
|
||||||
created_at TEXT NOT NULL DEFAULT (datetime('now')),
|
|
||||||
updated_at TEXT NOT NULL DEFAULT (datetime('now'))
|
|
||||||
)`);
|
|
||||||
|
|
||||||
export const sha256 = (s) => createHash('sha256').update(String(s)).digest('hex');
|
|
||||||
|
|
||||||
// Default parent PIN on first run
|
|
||||||
if (!db.prepare(`SELECT value FROM settings WHERE key = 'pin'`).get()) {
|
|
||||||
db.prepare(`INSERT INTO settings (key, value) VALUES ('pin', ?)`).run(sha256('1234'));
|
|
||||||
}
|
|
||||||
|
|
||||||
// Default scan config (local Ollama primary, no cloud key yet)
|
|
||||||
const seedSetting = (key, val) => {
|
|
||||||
if (!db.prepare(`SELECT value FROM settings WHERE key = ?`).get(key))
|
|
||||||
db.prepare(`INSERT INTO settings (key, value) VALUES (?, ?)`).run(key, val);
|
|
||||||
};
|
|
||||||
seedSetting('school_name', '');
|
|
||||||
seedSetting('passing_pct', '80');
|
|
||||||
seedSetting('week_start_day', 'monday');
|
|
||||||
|
|
||||||
// Seed bundled word lists on first run
|
|
||||||
if (db.prepare(`SELECT COUNT(*) AS n FROM lists`).get().n === 0) {
|
|
||||||
const seed = JSON.parse(readFileSync(join(ROOT, 'seed-lists.json'), 'utf8'));
|
|
||||||
const insList = db.prepare(`INSERT INTO lists (name, builtin) VALUES (?, 1)`);
|
|
||||||
const insWord = db.prepare(`INSERT INTO words (list_id, word, sentence) VALUES (?, ?, ?)`);
|
|
||||||
for (const list of seed) {
|
|
||||||
const listId = insList.run(list.name).lastInsertRowid;
|
|
||||||
for (const entry of list.words) {
|
|
||||||
const { word, sentence = '' } = typeof entry === 'string' ? { word: entry } : entry;
|
|
||||||
insWord.run(listId, word, sentence);
|
|
||||||
}
|
|
||||||
}
|
|
||||||
}
|
|
||||||
|
|
||||||
// Seed bundled flashcard decks on first run
|
|
||||||
if (db.prepare(`SELECT COUNT(*) AS n FROM decks`).get().n === 0) {
|
|
||||||
const seed = JSON.parse(readFileSync(join(ROOT, 'seed-decks.json'), 'utf8'));
|
|
||||||
const insDeck = db.prepare(`INSERT INTO decks (name, builtin) VALUES (?, 1)`);
|
|
||||||
const insCard = db.prepare(`INSERT INTO cards (deck_id, front, back) VALUES (?, ?, ?)`);
|
|
||||||
for (const deck of seed) {
|
|
||||||
const deckId = insDeck.run(deck.name).lastInsertRowid;
|
|
||||||
for (const c of deck.cards) insCard.run(deckId, c.front, c.back);
|
|
||||||
}
|
|
||||||
}
|
|
||||||
@@ -0,0 +1,48 @@
|
|||||||
|
// Debug script to test the /getUsers endpoint
|
||||||
|
const fetch = (...args) => import('node-fetch').then(({default: fetch}) => fetch(...args));
|
||||||
|
|
||||||
|
(async () => {
|
||||||
|
try {
|
||||||
|
console.log('Testing /getUsers endpoint...');
|
||||||
|
|
||||||
|
const response = await fetch('http://localhost:3000/getUsers');
|
||||||
|
console.log(`STATUS: ${response.status} ${response.statusText}`);
|
||||||
|
|
||||||
|
const headers = {};
|
||||||
|
response.headers.forEach((value, key) => {
|
||||||
|
headers[key] = value;
|
||||||
|
});
|
||||||
|
console.log('HEADERS:', headers);
|
||||||
|
|
||||||
|
if (!response.ok) {
|
||||||
|
console.error(`⚠️ API responded with ${response.status}`);
|
||||||
|
return;
|
||||||
|
}
|
||||||
|
|
||||||
|
const text = await response.text();
|
||||||
|
console.log('Response body length:', text.length);
|
||||||
|
|
||||||
|
try {
|
||||||
|
if (text.length > 0) {
|
||||||
|
const users = JSON.parse(text);
|
||||||
|
console.log('✅ Response contains valid JSON');
|
||||||
|
if (Array.isArray(users)) {
|
||||||
|
console.log(`Found ${users.length} users:`, users.map(u => u.username));
|
||||||
|
|
||||||
|
if (users.length === 0) {
|
||||||
|
console.log('⚠️ WARNING: No users returned from API');
|
||||||
|
}
|
||||||
|
} else {
|
||||||
|
console.log('⚠️ Response is not an array:', users);
|
||||||
|
}
|
||||||
|
} else {
|
||||||
|
console.log('⚠️ Empty response received');
|
||||||
|
}
|
||||||
|
} catch (e) {
|
||||||
|
console.error('❌ ERROR: Invalid JSON in response:', e.message);
|
||||||
|
console.log('Raw response:', text.substring(0, 100) + (text.length > 100 ? '...' : ''));
|
||||||
|
}
|
||||||
|
} catch (error) {
|
||||||
|
console.error(`❌ ERROR: ${error.message}`);
|
||||||
|
}
|
||||||
|
})();
|
||||||
@@ -0,0 +1,59 @@
|
|||||||
|
// Debug script to test the /getUsers endpoint
|
||||||
|
const http = require('http');
|
||||||
|
|
||||||
|
console.log('Testing /getUsers endpoint...');
|
||||||
|
|
||||||
|
const options = {
|
||||||
|
hostname: 'localhost',
|
||||||
|
port: 3000,
|
||||||
|
path: '/getUsers',
|
||||||
|
method: 'GET',
|
||||||
|
headers: {
|
||||||
|
'Accept': 'application/json'
|
||||||
|
}
|
||||||
|
};
|
||||||
|
|
||||||
|
const req = http.request(options, (res) => {
|
||||||
|
console.log(`STATUS: ${res.statusCode}`);
|
||||||
|
console.log(`HEADERS: ${JSON.stringify(res.headers)}`);
|
||||||
|
|
||||||
|
let data = '';
|
||||||
|
|
||||||
|
res.on('data', (chunk) => {
|
||||||
|
data += chunk;
|
||||||
|
});
|
||||||
|
|
||||||
|
res.on('end', () => {
|
||||||
|
console.log('Response body length:', data.length);
|
||||||
|
|
||||||
|
try {
|
||||||
|
if (data.length > 0) {
|
||||||
|
const users = JSON.parse(data);
|
||||||
|
console.log('✅ Response contains valid JSON');
|
||||||
|
if (Array.isArray(users)) {
|
||||||
|
console.log(`Found ${users.length} users:`, users.map(u => u.username));
|
||||||
|
|
||||||
|
if (users.length === 0) {
|
||||||
|
console.log('⚠️ WARNING: No users returned from API');
|
||||||
|
}
|
||||||
|
} else {
|
||||||
|
console.log('⚠️ Response is not an array:', users);
|
||||||
|
}
|
||||||
|
} else {
|
||||||
|
console.log('⚠️ Empty response received');
|
||||||
|
}
|
||||||
|
} catch (e) {
|
||||||
|
console.error('❌ ERROR: Invalid JSON in response:', e.message);
|
||||||
|
console.log('Raw response:', data.substring(0, 100) + (data.length > 100 ? '...' : ''));
|
||||||
|
}
|
||||||
|
|
||||||
|
process.exit(0); // Exit successfully
|
||||||
|
});
|
||||||
|
});
|
||||||
|
|
||||||
|
req.on('error', (e) => {
|
||||||
|
console.error(`❌ ERROR: ${e.message}`);
|
||||||
|
process.exit(1); // Exit with error
|
||||||
|
});
|
||||||
|
|
||||||
|
req.end();
|
||||||
@@ -0,0 +1,17 @@
|
|||||||
|
// Debug script to check password hashes
|
||||||
|
const { createHash } = require('crypto');
|
||||||
|
|
||||||
|
function hashPassword(password) {
|
||||||
|
return createHash('sha256').update(password).digest('hex');
|
||||||
|
}
|
||||||
|
|
||||||
|
console.log('Testing password hashes:');
|
||||||
|
console.log('password -> ', hashPassword('password'));
|
||||||
|
console.log('123456 -> ', hashPassword('123456'));
|
||||||
|
console.log('test -> ', hashPassword('test'));
|
||||||
|
|
||||||
|
// Known hashes from users.json:
|
||||||
|
console.log('\nExpected hashes from users.json:');
|
||||||
|
console.log('admin1 (password): 5e884898da28047151d0e56f8dc6292773603d0d6aabbdd62a11ef721d1542d8');
|
||||||
|
console.log('student1 (123456): 8d969eef6ecad3c29a3a629280e686cf0c3f5d5a86aff3ca12020c923adc6c92');
|
||||||
|
console.log('nate: 5a2a558c78d3717db731600c4f354fa1d9c84b556f108091a891f444f1bdec40');
|
||||||
@@ -0,0 +1,100 @@
|
|||||||
|
/**
|
||||||
|
* Debug utility to check the results.json file and report any issues
|
||||||
|
* Run with: node debug-results.js
|
||||||
|
*/
|
||||||
|
const fs = require('fs');
|
||||||
|
const path = require('path');
|
||||||
|
|
||||||
|
const DATA_DIR = path.join(__dirname, 'data');
|
||||||
|
const RESULTS_FILE = path.join(DATA_DIR, 'results.json');
|
||||||
|
|
||||||
|
console.log('🔍 Debug Results.json Utility');
|
||||||
|
console.log('============================');
|
||||||
|
|
||||||
|
// Check if the file exists
|
||||||
|
console.log(`\n1. Checking if results.json exists at: ${RESULTS_FILE}`);
|
||||||
|
if (fs.existsSync(RESULTS_FILE)) {
|
||||||
|
console.log('✅ File exists');
|
||||||
|
|
||||||
|
// Check file size
|
||||||
|
const stats = fs.statSync(RESULTS_FILE);
|
||||||
|
console.log(`📊 File size: ${stats.size} bytes`);
|
||||||
|
|
||||||
|
// Check file permissions
|
||||||
|
console.log(`📊 File permissions: ${(stats.mode & 0o777).toString(8)}`);
|
||||||
|
|
||||||
|
// Try to read the file
|
||||||
|
console.log('\n2. Attempting to read the file');
|
||||||
|
try {
|
||||||
|
const fileContent = fs.readFileSync(RESULTS_FILE, 'utf8');
|
||||||
|
console.log(`✅ File read successfully (${fileContent.length} characters)`);
|
||||||
|
|
||||||
|
// Check for empty file
|
||||||
|
if (fileContent.trim() === '') {
|
||||||
|
console.log('⚠️ Warning: File is empty');
|
||||||
|
|
||||||
|
// Create a valid empty structure
|
||||||
|
fs.writeFileSync(RESULTS_FILE, JSON.stringify({}, null, 2));
|
||||||
|
console.log('✅ Created valid empty structure');
|
||||||
|
} else {
|
||||||
|
// Try to parse the JSON
|
||||||
|
console.log('\n3. Attempting to parse JSON');
|
||||||
|
try {
|
||||||
|
const data = JSON.parse(fileContent);
|
||||||
|
console.log('✅ JSON parsed successfully');
|
||||||
|
|
||||||
|
// Check the structure
|
||||||
|
if (typeof data !== 'object' || data === null) {
|
||||||
|
console.log('❌ Error: Root is not an object');
|
||||||
|
} else {
|
||||||
|
const userCount = Object.keys(data).length;
|
||||||
|
console.log(`📊 Contains data for ${userCount} users`);
|
||||||
|
|
||||||
|
// Display some stats about each user's sessions
|
||||||
|
Object.entries(data).forEach(([username, sessions]) => {
|
||||||
|
if (!Array.isArray(sessions)) {
|
||||||
|
console.log(`❌ Error: Sessions for ${username} is not an array`);
|
||||||
|
} else {
|
||||||
|
console.log(`📊 ${username}: ${sessions.length} sessions`);
|
||||||
|
}
|
||||||
|
});
|
||||||
|
}
|
||||||
|
} catch (parseError) {
|
||||||
|
console.log(`❌ Error parsing JSON: ${parseError.message}`);
|
||||||
|
|
||||||
|
// Try to identify the location of the error
|
||||||
|
const errorMatch = parseError.message.match(/position (\d+)/);
|
||||||
|
if (errorMatch && errorMatch[1]) {
|
||||||
|
const position = parseInt(errorMatch[1]);
|
||||||
|
const start = Math.max(0, position - 20);
|
||||||
|
const end = Math.min(fileContent.length, position + 20);
|
||||||
|
console.log(`Error near: ...${fileContent.substring(start, position)}[HERE]${fileContent.substring(position, end)}...`);
|
||||||
|
}
|
||||||
|
|
||||||
|
// If the file seems to be corrupted, offer to create a new one
|
||||||
|
console.log('\nThe file appears to be corrupted. Do you want to reset it to a valid empty structure?');
|
||||||
|
console.log('To reset, run: node -e "require(\'fs\').writeFileSync(\'./data/results.json\', JSON.stringify({}, null, 2))"');
|
||||||
|
}
|
||||||
|
}
|
||||||
|
} catch (readError) {
|
||||||
|
console.log(`❌ Error reading file: ${readError.message}`);
|
||||||
|
}
|
||||||
|
} else {
|
||||||
|
console.log('❌ File does not exist');
|
||||||
|
|
||||||
|
// Create the file with a valid empty structure
|
||||||
|
try {
|
||||||
|
// Make sure the data directory exists
|
||||||
|
if (!fs.existsSync(DATA_DIR)) {
|
||||||
|
fs.mkdirSync(DATA_DIR, { recursive: true });
|
||||||
|
console.log(`✅ Created data directory at: ${DATA_DIR}`);
|
||||||
|
}
|
||||||
|
|
||||||
|
fs.writeFileSync(RESULTS_FILE, JSON.stringify({}, null, 2));
|
||||||
|
console.log('✅ Created file with valid empty structure');
|
||||||
|
} catch (createError) {
|
||||||
|
console.log(`❌ Error creating file: ${createError.message}`);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
console.log('\nDone!');
|
||||||
@@ -0,0 +1,26 @@
|
|||||||
|
// Very simple test to fetch from our own server
|
||||||
|
const http = require('http');
|
||||||
|
|
||||||
|
console.log('Testing server...');
|
||||||
|
|
||||||
|
try {
|
||||||
|
// Simple HTTP GET request
|
||||||
|
http.get('http://localhost:3000/', (res) => {
|
||||||
|
let data = '';
|
||||||
|
|
||||||
|
res.on('data', (chunk) => {
|
||||||
|
data += chunk;
|
||||||
|
});
|
||||||
|
|
||||||
|
res.on('end', () => {
|
||||||
|
console.log('Status:', res.statusCode);
|
||||||
|
console.log('Response length:', data.length);
|
||||||
|
console.log('Response preview:', data.substring(0, 100) + '...');
|
||||||
|
});
|
||||||
|
|
||||||
|
}).on('error', (err) => {
|
||||||
|
console.error('Error connecting to server:', err.message);
|
||||||
|
});
|
||||||
|
} catch (error) {
|
||||||
|
console.error('Failed to make request:', error);
|
||||||
|
}
|
||||||
@@ -0,0 +1,83 @@
|
|||||||
|
// Debug utility to check if users.json exists
|
||||||
|
const fs = require('fs');
|
||||||
|
const path = require('path');
|
||||||
|
|
||||||
|
const DATA_DIR = path.join(__dirname, 'data');
|
||||||
|
const SEED_DIR = path.join(__dirname, 'seed');
|
||||||
|
const usersFile = path.join(DATA_DIR, 'users.json');
|
||||||
|
|
||||||
|
console.log('Checking for users.json file...');
|
||||||
|
console.log(`DATA_DIR: ${DATA_DIR}`);
|
||||||
|
|
||||||
|
// Check if data directory exists
|
||||||
|
if (fs.existsSync(DATA_DIR)) {
|
||||||
|
console.log('✅ Data directory exists');
|
||||||
|
} else {
|
||||||
|
console.log('❌ Data directory does not exist!');
|
||||||
|
console.log('Creating data directory...');
|
||||||
|
fs.mkdirSync(DATA_DIR);
|
||||||
|
}
|
||||||
|
|
||||||
|
// Check if users.json exists
|
||||||
|
if (fs.existsSync(usersFile)) {
|
||||||
|
console.log('✅ users.json exists');
|
||||||
|
|
||||||
|
// Read file and check content
|
||||||
|
try {
|
||||||
|
const content = fs.readFileSync(usersFile, 'utf-8');
|
||||||
|
console.log('File content length:', content.length);
|
||||||
|
|
||||||
|
try {
|
||||||
|
const users = JSON.parse(content);
|
||||||
|
console.log('✅ users.json contains valid JSON');
|
||||||
|
console.log(`Found ${users.length} users:`, users.map(u => u.username));
|
||||||
|
} catch (e) {
|
||||||
|
console.log('❌ users.json contains invalid JSON:', e.message);
|
||||||
|
console.log('File content:', content);
|
||||||
|
}
|
||||||
|
} catch (e) {
|
||||||
|
console.log('❌ Could not read users.json:', e.message);
|
||||||
|
}
|
||||||
|
} else {
|
||||||
|
console.log('❌ users.json does not exist!');
|
||||||
|
|
||||||
|
// Check if seed exists
|
||||||
|
const seedFile = path.join(SEED_DIR, 'users.json');
|
||||||
|
if (fs.existsSync(seedFile)) {
|
||||||
|
console.log('✅ Seed users.json exists');
|
||||||
|
|
||||||
|
try {
|
||||||
|
const content = fs.readFileSync(seedFile, 'utf-8');
|
||||||
|
console.log('Copying seed to data directory...');
|
||||||
|
fs.writeFileSync(usersFile, content);
|
||||||
|
console.log('✅ Seed copied to data directory');
|
||||||
|
} catch (e) {
|
||||||
|
console.log('❌ Could not copy seed users.json:', e.message);
|
||||||
|
}
|
||||||
|
} else {
|
||||||
|
console.log('❌ Seed users.json does not exist!');
|
||||||
|
|
||||||
|
// Create default users
|
||||||
|
const defaultUsers = [
|
||||||
|
{
|
||||||
|
"username": "admin1",
|
||||||
|
"hash": "5e884898da28047151d0e56f8dc6292773603d0d6aabbdd62a11ef721d1542d8", // password
|
||||||
|
"role": "admin"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "nate",
|
||||||
|
"hash": "5a2a558c78d3717db731600c4f354fa1d9c84b556f108091a891f444f1bdec40", // nate123
|
||||||
|
"role": "student"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"username": "student1",
|
||||||
|
"hash": "8d969eef6ecad3c29a3a629280e686cf0c3f5d5a86aff3ca12020c923adc6c92", // 123456
|
||||||
|
"role": "student"
|
||||||
|
}
|
||||||
|
];
|
||||||
|
|
||||||
|
console.log('Creating default users.json...');
|
||||||
|
fs.writeFileSync(usersFile, JSON.stringify(defaultUsers, null, 2));
|
||||||
|
console.log('✅ Default users.json created');
|
||||||
|
}
|
||||||
|
}
|
||||||
@@ -0,0 +1,51 @@
|
|||||||
|
# PowerShell script to build and push Docker image for Spelling Practice App
|
||||||
|
|
||||||
|
# Set variables
|
||||||
|
$IMAGE_NAME = "ghcr.io/nmemmert/spelling"
|
||||||
|
$VERSION = (Get-Content -Path "version.json" | ConvertFrom-Json).version
|
||||||
|
|
||||||
|
Write-Host "🔨 Building Docker image ${IMAGE_NAME}:${VERSION}..." -ForegroundColor Cyan
|
||||||
|
|
||||||
|
# Build the image
|
||||||
|
docker build -t ${IMAGE_NAME}:${VERSION} -t ${IMAGE_NAME}:latest .
|
||||||
|
|
||||||
|
Write-Host "✅ Build completed." -ForegroundColor Green
|
||||||
|
Write-Host "🧪 Testing the image..." -ForegroundColor Cyan
|
||||||
|
|
||||||
|
# Run container for testing
|
||||||
|
docker run --name spelling-test -d -p 3001:3000 ${IMAGE_NAME}:${VERSION}
|
||||||
|
|
||||||
|
# Wait for container to start
|
||||||
|
Start-Sleep -Seconds 5
|
||||||
|
|
||||||
|
# Test health endpoint
|
||||||
|
try {
|
||||||
|
$response = Invoke-WebRequest -Uri "http://localhost:3001/health" -UseBasicParsing
|
||||||
|
if ($response.StatusCode -eq 200) {
|
||||||
|
Write-Host "✅ Health check passed!" -ForegroundColor Green
|
||||||
|
} else {
|
||||||
|
Write-Host "❌ Health check failed with status $($response.StatusCode)" -ForegroundColor Red
|
||||||
|
docker logs spelling-test
|
||||||
|
docker stop spelling-test
|
||||||
|
docker rm spelling-test
|
||||||
|
exit 1
|
||||||
|
}
|
||||||
|
} catch {
|
||||||
|
Write-Host "❌ Health check failed: $_" -ForegroundColor Red
|
||||||
|
docker logs spelling-test
|
||||||
|
docker stop spelling-test
|
||||||
|
docker rm spelling-test
|
||||||
|
exit 1
|
||||||
|
}
|
||||||
|
|
||||||
|
# Stop and remove test container
|
||||||
|
docker stop spelling-test
|
||||||
|
docker rm spelling-test
|
||||||
|
|
||||||
|
Write-Host "📤 Pushing image to GitHub Container Registry..." -ForegroundColor Cyan
|
||||||
|
docker push ${IMAGE_NAME}:${VERSION}
|
||||||
|
docker push ${IMAGE_NAME}:latest
|
||||||
|
|
||||||
|
Write-Host "🚀 Successfully built and pushed ${IMAGE_NAME}:${VERSION}" -ForegroundColor Green
|
||||||
|
Write-Host "Press any key to exit..."
|
||||||
|
$null = $host.UI.RawUI.ReadKey("NoEcho,IncludeKeyDown")
|
||||||
+17
-7
@@ -1,12 +1,22 @@
|
|||||||
|
version: "3.9"
|
||||||
|
|
||||||
services:
|
services:
|
||||||
spelling:
|
spelling-app:
|
||||||
image: ghcr.io/nmemmert/spelling:latest
|
build:
|
||||||
container_name: spelling-v2
|
context: .
|
||||||
|
dockerfile: Dockerfile
|
||||||
|
image: ghcr.io/nmemmert/spelling:1.1.0
|
||||||
|
container_name: spelling-app
|
||||||
ports:
|
ports:
|
||||||
- "3000:3000"
|
- "3000:3000"
|
||||||
volumes:
|
volumes:
|
||||||
- spelling-data:/app/data
|
- ./data:/app/data
|
||||||
|
environment:
|
||||||
|
- NODE_ENV=production
|
||||||
restart: unless-stopped
|
restart: unless-stopped
|
||||||
|
healthcheck:
|
||||||
volumes:
|
test: ["CMD", "node", "-e", "require('http').get('http://localhost:3000/health', res => res.statusCode === 200 ? process.exit(0) : process.exit(1))"]
|
||||||
spelling-data:
|
interval: 30s
|
||||||
|
timeout: 10s
|
||||||
|
retries: 3
|
||||||
|
start_period: 10s
|
||||||
@@ -0,0 +1,474 @@
|
|||||||
|
// Gamification API endpoints for the Spelling Practice App
|
||||||
|
|
||||||
|
module.exports = function(app, DATA_DIR, files, readJsonSafe, isToday, isSameDay) {
|
||||||
|
|
||||||
|
// 🏆 Get leaderboards
|
||||||
|
app.get('/getLeaderboards', (req, res) => {
|
||||||
|
try {
|
||||||
|
const leaderboards = readJsonSafe(path.join(DATA_DIR, files.leaderboards), {});
|
||||||
|
res.json(leaderboards);
|
||||||
|
} catch (error) {
|
||||||
|
console.error('Error getting leaderboards:', error);
|
||||||
|
res.status(500).send('Failed to get leaderboards');
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
// 🎯 Get current challenges
|
||||||
|
app.get('/getChallenges', (req, res) => {
|
||||||
|
try {
|
||||||
|
const challenges = readJsonSafe(path.join(DATA_DIR, files.challenges), {});
|
||||||
|
res.json(challenges);
|
||||||
|
} catch (error) {
|
||||||
|
console.error('Error getting challenges:', error);
|
||||||
|
res.status(500).send('Failed to get challenges');
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
// 📈 Get user progress
|
||||||
|
app.get('/getUserProgress', (req, res) => {
|
||||||
|
try {
|
||||||
|
const { username } = req.query;
|
||||||
|
if (!username) {
|
||||||
|
return res.status(400).send('Username is required');
|
||||||
|
}
|
||||||
|
|
||||||
|
const progress = readJsonSafe(path.join(DATA_DIR, files.progress), {});
|
||||||
|
|
||||||
|
if (!progress[username]) {
|
||||||
|
return res.status(404).send('User progress not found');
|
||||||
|
}
|
||||||
|
|
||||||
|
res.json(progress[username]);
|
||||||
|
} catch (error) {
|
||||||
|
console.error('Error getting user progress:', error);
|
||||||
|
res.status(500).send('Failed to get user progress');
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
// 📋 Get all users' progress
|
||||||
|
app.get('/getAllProgress', (req, res) => {
|
||||||
|
try {
|
||||||
|
const progress = readJsonSafe(path.join(DATA_DIR, files.progress), {});
|
||||||
|
res.json(progress);
|
||||||
|
} catch (error) {
|
||||||
|
console.error('Error getting all progress data:', error);
|
||||||
|
res.status(500).send('Failed to get progress data');
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
// 🔄 Update user streak
|
||||||
|
app.post('/updateStreak', (req, res) => {
|
||||||
|
try {
|
||||||
|
const { username } = req.body;
|
||||||
|
if (!username) {
|
||||||
|
return res.status(400).send('Username is required');
|
||||||
|
}
|
||||||
|
|
||||||
|
const progress = readJsonSafe(path.join(DATA_DIR, files.progress), {});
|
||||||
|
|
||||||
|
if (!progress[username]) {
|
||||||
|
return res.status(404).send('User progress not found');
|
||||||
|
}
|
||||||
|
|
||||||
|
const userProgress = progress[username];
|
||||||
|
const now = new Date();
|
||||||
|
const lastActivity = userProgress.streaks.lastActivity ? new Date(userProgress.streaks.lastActivity) : null;
|
||||||
|
|
||||||
|
// If this is the first activity or it's a new day
|
||||||
|
if (!lastActivity || !isToday(lastActivity)) {
|
||||||
|
// Check if the streak continues (last activity was yesterday)
|
||||||
|
if (lastActivity) {
|
||||||
|
const yesterday = new Date();
|
||||||
|
yesterday.setDate(yesterday.getDate() - 1);
|
||||||
|
|
||||||
|
if (isSameDay(lastActivity, yesterday)) {
|
||||||
|
// Streak continues
|
||||||
|
userProgress.streaks.current++;
|
||||||
|
} else {
|
||||||
|
// Streak broken
|
||||||
|
userProgress.streaks.current = 1;
|
||||||
|
}
|
||||||
|
} else {
|
||||||
|
// First activity
|
||||||
|
userProgress.streaks.current = 1;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Update longest streak if needed
|
||||||
|
if (userProgress.streaks.current > userProgress.streaks.longest) {
|
||||||
|
userProgress.streaks.longest = userProgress.streaks.current;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Update last activity
|
||||||
|
userProgress.streaks.lastActivity = now.toISOString();
|
||||||
|
|
||||||
|
// Write updated progress
|
||||||
|
fs.writeFileSync(path.join(DATA_DIR, files.progress), JSON.stringify(progress, null, 2));
|
||||||
|
|
||||||
|
// Check for streak achievements
|
||||||
|
checkStreakAchievements(username, userProgress.streaks.current);
|
||||||
|
}
|
||||||
|
|
||||||
|
res.json({ streak: userProgress.streaks });
|
||||||
|
} catch (error) {
|
||||||
|
console.error('Error updating streak:', error);
|
||||||
|
res.status(500).send('Failed to update streak');
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
// 📝 Complete challenge
|
||||||
|
app.post('/completeChallenge', (req, res) => {
|
||||||
|
try {
|
||||||
|
const { username, challengeId, challengeType } = req.body;
|
||||||
|
if (!username || !challengeId || !challengeType) {
|
||||||
|
return res.status(400).send('Username, challengeId, and challengeType are required');
|
||||||
|
}
|
||||||
|
|
||||||
|
// Valid challenge types
|
||||||
|
if (!['daily', 'weekly', 'achievements'].includes(challengeType)) {
|
||||||
|
return res.status(400).send('Invalid challenge type');
|
||||||
|
}
|
||||||
|
|
||||||
|
const progress = readJsonSafe(path.join(DATA_DIR, files.progress), {});
|
||||||
|
const challenges = readJsonSafe(path.join(DATA_DIR, files.challenges), {});
|
||||||
|
|
||||||
|
if (!progress[username]) {
|
||||||
|
return res.status(404).send('User progress not found');
|
||||||
|
}
|
||||||
|
|
||||||
|
// Find the challenge
|
||||||
|
let challenge = null;
|
||||||
|
if (challengeType === 'achievements') {
|
||||||
|
challenge = challenges.achievements?.find(c => c.id === challengeId);
|
||||||
|
} else {
|
||||||
|
challenge = challenges[challengeType]?.current?.id === challengeId
|
||||||
|
? challenges[challengeType].current
|
||||||
|
: challenges[challengeType]?.history?.find(c => c.id === challengeId);
|
||||||
|
}
|
||||||
|
|
||||||
|
if (!challenge) {
|
||||||
|
return res.status(404).send('Challenge not found');
|
||||||
|
}
|
||||||
|
|
||||||
|
// Check if already completed
|
||||||
|
if (progress[username].challengesCompleted[challengeType].includes(challengeId)) {
|
||||||
|
return res.status(409).send('Challenge already completed');
|
||||||
|
}
|
||||||
|
|
||||||
|
// Mark as completed
|
||||||
|
progress[username].challengesCompleted[challengeType].push(challengeId);
|
||||||
|
|
||||||
|
// Award points
|
||||||
|
if (challenge.reward && challenge.reward.points) {
|
||||||
|
progress[username].stats.points += challenge.reward.points;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Award badge if applicable
|
||||||
|
if (challenge.reward && challenge.reward.badge) {
|
||||||
|
const badges = readJsonSafe(path.join(DATA_DIR, files.badges), {});
|
||||||
|
|
||||||
|
if (!badges[username]) {
|
||||||
|
badges[username] = [];
|
||||||
|
}
|
||||||
|
|
||||||
|
if (!badges[username].includes(challenge.reward.badge)) {
|
||||||
|
badges[username].push(challenge.reward.badge);
|
||||||
|
fs.writeFileSync(path.join(DATA_DIR, files.badges), JSON.stringify(badges, null, 2));
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Write updated progress
|
||||||
|
fs.writeFileSync(path.join(DATA_DIR, files.progress), JSON.stringify(progress, null, 2));
|
||||||
|
|
||||||
|
res.json({
|
||||||
|
message: 'Challenge completed',
|
||||||
|
updatedProgress: progress[username]
|
||||||
|
});
|
||||||
|
} catch (error) {
|
||||||
|
console.error('Error completing challenge:', error);
|
||||||
|
res.status(500).send('Failed to complete challenge');
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
// 🔄 Update leaderboards
|
||||||
|
app.post('/updateLeaderboards', (req, res) => {
|
||||||
|
try {
|
||||||
|
// This should be an admin-only endpoint
|
||||||
|
const leaderboards = readJsonSafe(path.join(DATA_DIR, files.leaderboards), {});
|
||||||
|
const progress = readJsonSafe(path.join(DATA_DIR, files.progress), {});
|
||||||
|
|
||||||
|
// Update all-time leaderboards
|
||||||
|
const accuracyLeaderboard = [];
|
||||||
|
const wordsLeaderboard = [];
|
||||||
|
const sessionsLeaderboard = [];
|
||||||
|
const streaksLeaderboard = [];
|
||||||
|
|
||||||
|
Object.entries(progress).forEach(([username, data]) => {
|
||||||
|
if (data.stats.totalSessions > 0) {
|
||||||
|
// Accuracy leaderboard
|
||||||
|
accuracyLeaderboard.push({
|
||||||
|
username,
|
||||||
|
value: data.stats.accuracy,
|
||||||
|
timestamp: new Date().toISOString()
|
||||||
|
});
|
||||||
|
|
||||||
|
// Words leaderboard
|
||||||
|
wordsLeaderboard.push({
|
||||||
|
username,
|
||||||
|
value: data.stats.totalWords,
|
||||||
|
timestamp: new Date().toISOString()
|
||||||
|
});
|
||||||
|
|
||||||
|
// Sessions leaderboard
|
||||||
|
sessionsLeaderboard.push({
|
||||||
|
username,
|
||||||
|
value: data.stats.totalSessions,
|
||||||
|
timestamp: new Date().toISOString()
|
||||||
|
});
|
||||||
|
|
||||||
|
// Streaks leaderboard
|
||||||
|
streaksLeaderboard.push({
|
||||||
|
username,
|
||||||
|
value: data.streaks.current,
|
||||||
|
timestamp: new Date().toISOString()
|
||||||
|
});
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
// Sort and limit leaderboards
|
||||||
|
leaderboards.allTime.accuracy = accuracyLeaderboard
|
||||||
|
.sort((a, b) => b.value - a.value)
|
||||||
|
.slice(0, 10);
|
||||||
|
|
||||||
|
leaderboards.allTime.totalWords = wordsLeaderboard
|
||||||
|
.sort((a, b) => b.value - a.value)
|
||||||
|
.slice(0, 10);
|
||||||
|
|
||||||
|
leaderboards.allTime.sessionsCompleted = sessionsLeaderboard
|
||||||
|
.sort((a, b) => b.value - a.value)
|
||||||
|
.slice(0, 10);
|
||||||
|
|
||||||
|
leaderboards.allTime.streakDays = streaksLeaderboard
|
||||||
|
.sort((a, b) => b.value - a.value)
|
||||||
|
.slice(0, 10);
|
||||||
|
|
||||||
|
// TODO: Implement weekly leaderboard calculations
|
||||||
|
|
||||||
|
leaderboards.lastUpdated = new Date().toISOString();
|
||||||
|
|
||||||
|
// Write updated leaderboards
|
||||||
|
fs.writeFileSync(path.join(DATA_DIR, files.leaderboards), JSON.stringify(leaderboards, null, 2));
|
||||||
|
|
||||||
|
res.json({ message: 'Leaderboards updated successfully' });
|
||||||
|
} catch (error) {
|
||||||
|
console.error('Error updating leaderboards:', error);
|
||||||
|
res.status(500).send('Failed to update leaderboards');
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
// 🆕 Generate new daily challenge
|
||||||
|
app.post('/generateDailyChallenge', (req, res) => {
|
||||||
|
try {
|
||||||
|
const challenges = readJsonSafe(path.join(DATA_DIR, files.challenges), {});
|
||||||
|
const today = new Date();
|
||||||
|
const dayString = today.toISOString().split('T')[0];
|
||||||
|
|
||||||
|
// Check if today's challenge already exists
|
||||||
|
if (challenges.daily.current && challenges.daily.current.date === dayString) {
|
||||||
|
return res.status(409).send('Today\'s challenge already exists');
|
||||||
|
}
|
||||||
|
|
||||||
|
// Move current challenge to history
|
||||||
|
if (challenges.daily.current) {
|
||||||
|
if (!challenges.daily.history) {
|
||||||
|
challenges.daily.history = [];
|
||||||
|
}
|
||||||
|
challenges.daily.history.unshift(challenges.daily.current);
|
||||||
|
|
||||||
|
// Limit history size
|
||||||
|
if (challenges.daily.history.length > 30) {
|
||||||
|
challenges.daily.history = challenges.daily.history.slice(0, 30);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Challenge types
|
||||||
|
const challengeTypes = [
|
||||||
|
{
|
||||||
|
type: 'accuracy',
|
||||||
|
description: 'Complete a spelling session with at least {target}% accuracy',
|
||||||
|
target: Math.floor(Math.random() * 11) + 85, // 85-95% accuracy
|
||||||
|
points: 50
|
||||||
|
},
|
||||||
|
{
|
||||||
|
type: 'words',
|
||||||
|
description: 'Spell {target} words correctly in one day',
|
||||||
|
target: Math.floor(Math.random() * 16) + 10, // 10-25 words
|
||||||
|
points: 40
|
||||||
|
},
|
||||||
|
{
|
||||||
|
type: 'sessions',
|
||||||
|
description: 'Complete {target} spelling sessions in one day',
|
||||||
|
target: Math.floor(Math.random() * 3) + 2, // 2-4 sessions
|
||||||
|
points: 60
|
||||||
|
}
|
||||||
|
];
|
||||||
|
|
||||||
|
// Choose random challenge type
|
||||||
|
const challenge = challengeTypes[Math.floor(Math.random() * challengeTypes.length)];
|
||||||
|
|
||||||
|
// Create new challenge
|
||||||
|
challenges.daily.current = {
|
||||||
|
id: `daily-${dayString}`,
|
||||||
|
title: `${today.toLocaleDateString('en-US', { month: 'long', day: 'numeric' })} Challenge`,
|
||||||
|
description: challenge.description.replace('{target}', challenge.target),
|
||||||
|
type: challenge.type,
|
||||||
|
target: challenge.target,
|
||||||
|
reward: {
|
||||||
|
points: challenge.points,
|
||||||
|
badge: null
|
||||||
|
},
|
||||||
|
date: dayString
|
||||||
|
};
|
||||||
|
|
||||||
|
challenges.lastUpdated = today.toISOString();
|
||||||
|
|
||||||
|
// Write updated challenges
|
||||||
|
fs.writeFileSync(path.join(DATA_DIR, files.challenges), JSON.stringify(challenges, null, 2));
|
||||||
|
|
||||||
|
res.json({ message: 'Daily challenge generated', challenge: challenges.daily.current });
|
||||||
|
} catch (error) {
|
||||||
|
console.error('Error generating daily challenge:', error);
|
||||||
|
res.status(500).send('Failed to generate daily challenge');
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
// 🆕 Generate new weekly challenge
|
||||||
|
app.post('/generateWeeklyChallenge', (req, res) => {
|
||||||
|
try {
|
||||||
|
const challenges = readJsonSafe(path.join(DATA_DIR, files.challenges), {});
|
||||||
|
const today = new Date();
|
||||||
|
const weekNum = getWeekNumber(today);
|
||||||
|
const yearNum = today.getFullYear();
|
||||||
|
const weekId = `weekly-${yearNum}-${weekNum}`;
|
||||||
|
|
||||||
|
// Check if this week's challenge already exists
|
||||||
|
if (challenges.weekly.current && challenges.weekly.current.id === weekId) {
|
||||||
|
return res.status(409).send('This week\'s challenge already exists');
|
||||||
|
}
|
||||||
|
|
||||||
|
// Move current challenge to history
|
||||||
|
if (challenges.weekly.current) {
|
||||||
|
if (!challenges.weekly.history) {
|
||||||
|
challenges.weekly.history = [];
|
||||||
|
}
|
||||||
|
challenges.weekly.history.unshift(challenges.weekly.current);
|
||||||
|
|
||||||
|
// Limit history size
|
||||||
|
if (challenges.weekly.history.length > 12) {
|
||||||
|
challenges.weekly.history = challenges.weekly.history.slice(0, 12);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Challenge types
|
||||||
|
const challengeTypes = [
|
||||||
|
{
|
||||||
|
type: 'streak',
|
||||||
|
description: 'Practice spelling for {target} consecutive days',
|
||||||
|
target: Math.floor(Math.random() * 3) + 4, // 4-6 days
|
||||||
|
points: 100,
|
||||||
|
badge: 'Weekly Warrior'
|
||||||
|
},
|
||||||
|
{
|
||||||
|
type: 'correctWords',
|
||||||
|
description: 'Spell {target} words correctly this week',
|
||||||
|
target: Math.floor(Math.random() * 51) + 75, // 75-125 words
|
||||||
|
points: 150,
|
||||||
|
badge: 'Word Master'
|
||||||
|
},
|
||||||
|
{
|
||||||
|
type: 'perfectSessions',
|
||||||
|
description: 'Complete {target} perfect spelling sessions this week',
|
||||||
|
target: Math.floor(Math.random() * 3) + 2, // 2-4 sessions
|
||||||
|
points: 200,
|
||||||
|
badge: 'Perfect Form'
|
||||||
|
}
|
||||||
|
];
|
||||||
|
|
||||||
|
// Choose random challenge type
|
||||||
|
const challenge = challengeTypes[Math.floor(Math.random() * challengeTypes.length)];
|
||||||
|
|
||||||
|
// Create new challenge
|
||||||
|
challenges.weekly.current = {
|
||||||
|
id: weekId,
|
||||||
|
title: `Week ${weekNum} Challenge`,
|
||||||
|
description: challenge.description.replace('{target}', challenge.target),
|
||||||
|
type: challenge.type,
|
||||||
|
target: challenge.target,
|
||||||
|
reward: {
|
||||||
|
points: challenge.points,
|
||||||
|
badge: challenge.badge
|
||||||
|
},
|
||||||
|
startDate: getWeekStartDate(today).toISOString().split('T')[0],
|
||||||
|
endDate: getWeekEndDate(today).toISOString().split('T')[0]
|
||||||
|
};
|
||||||
|
|
||||||
|
challenges.lastUpdated = today.toISOString();
|
||||||
|
|
||||||
|
// Write updated challenges
|
||||||
|
fs.writeFileSync(path.join(DATA_DIR, files.challenges), JSON.stringify(challenges, null, 2));
|
||||||
|
|
||||||
|
res.json({ message: 'Weekly challenge generated', challenge: challenges.weekly.current });
|
||||||
|
} catch (error) {
|
||||||
|
console.error('Error generating weekly challenge:', error);
|
||||||
|
res.status(500).send('Failed to generate weekly challenge');
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
// Helper function to check for streak achievements
|
||||||
|
function checkStreakAchievements(username, currentStreak) {
|
||||||
|
try {
|
||||||
|
const challenges = readJsonSafe(path.join(DATA_DIR, files.challenges), {});
|
||||||
|
const progress = readJsonSafe(path.join(DATA_DIR, files.progress), {});
|
||||||
|
|
||||||
|
// Find streak-based achievements
|
||||||
|
const streakAchievements = challenges.achievements.filter(
|
||||||
|
a => a.type === 'streak' && a.condition === 'dailyLogin'
|
||||||
|
);
|
||||||
|
|
||||||
|
// Check if any achievement is unlocked by the current streak
|
||||||
|
streakAchievements.forEach(achievement => {
|
||||||
|
// If streak target met and not already completed
|
||||||
|
if (currentStreak >= achievement.target &&
|
||||||
|
!progress[username].challengesCompleted.achievements.includes(achievement.id)) {
|
||||||
|
|
||||||
|
// Mark as completed
|
||||||
|
progress[username].challengesCompleted.achievements.push(achievement.id);
|
||||||
|
|
||||||
|
// Award points
|
||||||
|
if (achievement.reward && achievement.reward.points) {
|
||||||
|
progress[username].stats.points += achievement.reward.points;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Award badge if applicable
|
||||||
|
if (achievement.reward && achievement.reward.badge) {
|
||||||
|
const badges = readJsonSafe(path.join(DATA_DIR, files.badges), {});
|
||||||
|
|
||||||
|
if (!badges[username]) {
|
||||||
|
badges[username] = [];
|
||||||
|
}
|
||||||
|
|
||||||
|
if (!badges[username].includes(achievement.reward.badge)) {
|
||||||
|
badges[username].push(achievement.reward.badge);
|
||||||
|
fs.writeFileSync(path.join(DATA_DIR, files.badges), JSON.stringify(badges, null, 2));
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
// Write updated progress if needed
|
||||||
|
fs.writeFileSync(path.join(DATA_DIR, files.progress), JSON.stringify(progress, null, 2));
|
||||||
|
} catch (error) {
|
||||||
|
console.error('Error checking streak achievements:', error);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
}; // Close the module.exports function
|
||||||
@@ -0,0 +1,373 @@
|
|||||||
|
/**
|
||||||
|
* Generate sample analytics data for the Spelling Practice App
|
||||||
|
* This script will add realistic user activity data to showcase the analytics features
|
||||||
|
*/
|
||||||
|
|
||||||
|
const fs = require('fs');
|
||||||
|
const path = require('path');
|
||||||
|
|
||||||
|
// Define paths
|
||||||
|
const DATA_DIR = path.join(__dirname, 'data');
|
||||||
|
const files = {
|
||||||
|
users: path.join(DATA_DIR, 'users.json'),
|
||||||
|
results: path.join(DATA_DIR, 'results.json'),
|
||||||
|
progress: path.join(DATA_DIR, 'progress.json'),
|
||||||
|
leaderboards: path.join(DATA_DIR, 'leaderboards.json'),
|
||||||
|
challenges: path.join(DATA_DIR, 'challenges.json')
|
||||||
|
};
|
||||||
|
|
||||||
|
// Helper functions
|
||||||
|
function readJsonSafe(filePath, defaultValue = {}) {
|
||||||
|
try {
|
||||||
|
if (fs.existsSync(filePath)) {
|
||||||
|
const content = fs.readFileSync(filePath, 'utf8');
|
||||||
|
return JSON.parse(content);
|
||||||
|
}
|
||||||
|
return defaultValue;
|
||||||
|
} catch (error) {
|
||||||
|
console.error(`Error reading ${filePath}:`, error);
|
||||||
|
return defaultValue;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
function writeJsonSafe(filePath, data) {
|
||||||
|
try {
|
||||||
|
fs.writeFileSync(filePath, JSON.stringify(data, null, 2));
|
||||||
|
return true;
|
||||||
|
} catch (error) {
|
||||||
|
console.error(`Error writing to ${filePath}:`, error);
|
||||||
|
return false;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Random helpers
|
||||||
|
function randomInt(min, max) {
|
||||||
|
return Math.floor(Math.random() * (max - min + 1) + min);
|
||||||
|
}
|
||||||
|
|
||||||
|
function randomFloat(min, max, decimals = 2) {
|
||||||
|
const rand = Math.random() * (max - min) + min;
|
||||||
|
return parseFloat(rand.toFixed(decimals));
|
||||||
|
}
|
||||||
|
|
||||||
|
// Date helpers
|
||||||
|
function addDays(date, days) {
|
||||||
|
const result = new Date(date);
|
||||||
|
result.setDate(result.getDate() + days);
|
||||||
|
return result;
|
||||||
|
}
|
||||||
|
|
||||||
|
function subtractDays(date, days) {
|
||||||
|
return addDays(date, -days);
|
||||||
|
}
|
||||||
|
|
||||||
|
function formatDate(date) {
|
||||||
|
return date.toISOString().split('T')[0];
|
||||||
|
}
|
||||||
|
|
||||||
|
function generateTimeOfDay() {
|
||||||
|
const hours = randomInt(8, 20).toString().padStart(2, '0');
|
||||||
|
const minutes = randomInt(0, 59).toString().padStart(2, '0');
|
||||||
|
const seconds = randomInt(0, 59).toString().padStart(2, '0');
|
||||||
|
return `${hours}:${minutes}:${seconds}`;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Main function to generate analytics data
|
||||||
|
async function generateAnalyticsData() {
|
||||||
|
console.log('Generating sample analytics data...');
|
||||||
|
|
||||||
|
// Load users
|
||||||
|
const users = readJsonSafe(files.users, []);
|
||||||
|
if (users.length === 0) {
|
||||||
|
console.error('No users found. Please ensure users exist before running this script.');
|
||||||
|
return;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Generate data for each user
|
||||||
|
const usernames = users.map(user => user.username);
|
||||||
|
|
||||||
|
// Generate 90 days of results data (covering 3 months)
|
||||||
|
const today = new Date();
|
||||||
|
|
||||||
|
// Load existing data
|
||||||
|
const resultsData = readJsonSafe(files.results, {});
|
||||||
|
const progressData = readJsonSafe(files.progress, {});
|
||||||
|
|
||||||
|
// For each user, generate 90 days of activity
|
||||||
|
for (const username of usernames) {
|
||||||
|
console.log(`Generating data for user: ${username}`);
|
||||||
|
|
||||||
|
// Initialize user results if not exists
|
||||||
|
if (!resultsData[username]) {
|
||||||
|
resultsData[username] = [];
|
||||||
|
}
|
||||||
|
|
||||||
|
// Initialize user progress if not exists
|
||||||
|
if (!progressData[username]) {
|
||||||
|
progressData[username] = {
|
||||||
|
stats: {
|
||||||
|
points: 0,
|
||||||
|
totalSessions: 0,
|
||||||
|
totalWords: 0,
|
||||||
|
correctWords: 0,
|
||||||
|
accuracy: 0
|
||||||
|
},
|
||||||
|
streaks: {
|
||||||
|
current: 0,
|
||||||
|
longest: 0,
|
||||||
|
dates: []
|
||||||
|
},
|
||||||
|
challengesCompleted: {
|
||||||
|
daily: [],
|
||||||
|
weekly: [],
|
||||||
|
achievements: []
|
||||||
|
},
|
||||||
|
activityLog: []
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
// Track total stats
|
||||||
|
let totalSessions = 0;
|
||||||
|
let totalWords = 0;
|
||||||
|
let totalCorrect = 0;
|
||||||
|
let streakDates = [];
|
||||||
|
let activityLog = [];
|
||||||
|
let points = randomInt(100, 500);
|
||||||
|
|
||||||
|
// Generate 90 days of activity with increasing frequency towards present day
|
||||||
|
for (let daysAgo = 90; daysAgo >= 0; daysAgo--) {
|
||||||
|
const activityDate = subtractDays(today, daysAgo);
|
||||||
|
const dateStr = formatDate(activityDate);
|
||||||
|
|
||||||
|
// Determine likelihood of activity on this day
|
||||||
|
// Higher chance of activity for more recent dates and on weekdays
|
||||||
|
const dayOfWeek = activityDate.getDay(); // 0 = Sunday, 6 = Saturday
|
||||||
|
const isWeekend = dayOfWeek === 0 || dayOfWeek === 6;
|
||||||
|
const recencyFactor = 1 - (daysAgo / 90); // 0 to 1 from oldest to newest
|
||||||
|
|
||||||
|
// Combine factors to determine chance of activity
|
||||||
|
// 30% base chance + up to 50% recency bonus - 20% weekend penalty
|
||||||
|
let activityChance = 0.3 + (recencyFactor * 0.5) - (isWeekend ? 0.2 : 0);
|
||||||
|
|
||||||
|
// For user "nate", increase activity chance to ensure good data
|
||||||
|
if (username === 'nate') {
|
||||||
|
activityChance += 0.2;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Determine if there's activity on this day
|
||||||
|
if (Math.random() < activityChance) {
|
||||||
|
// Record streak date
|
||||||
|
streakDates.push(dateStr);
|
||||||
|
|
||||||
|
// Determine number of sessions for this day (1-3)
|
||||||
|
const sessionsToday = randomInt(1, username === 'nate' ? 3 : 2);
|
||||||
|
|
||||||
|
for (let s = 0; s < sessionsToday; s++) {
|
||||||
|
// Generate session ID
|
||||||
|
const sessionId = `${username}-${dateStr}-${s}`;
|
||||||
|
|
||||||
|
// Determine session details
|
||||||
|
const numWords = randomInt(5, 15);
|
||||||
|
|
||||||
|
// Base accuracy that improves over time due to learning
|
||||||
|
let baseAccuracy = 0.65 + (recencyFactor * 0.2);
|
||||||
|
|
||||||
|
// Add some randomness
|
||||||
|
const accuracy = Math.min(0.98, baseAccuracy + randomFloat(-0.1, 0.1));
|
||||||
|
|
||||||
|
// Calculate correct words
|
||||||
|
const correctWords = Math.round(numWords * accuracy);
|
||||||
|
|
||||||
|
// Generate random words
|
||||||
|
const words = Array.from({length: numWords}, (_, i) => {
|
||||||
|
const isCorrect = i < correctWords;
|
||||||
|
return {
|
||||||
|
word: `sample-word-${randomInt(1, 100)}`,
|
||||||
|
correct: isCorrect
|
||||||
|
};
|
||||||
|
});
|
||||||
|
|
||||||
|
// Create session result
|
||||||
|
const sessionResult = {
|
||||||
|
date: `${dateStr}T${generateTimeOfDay()}Z`,
|
||||||
|
sessionId,
|
||||||
|
total: numWords,
|
||||||
|
correct: correctWords,
|
||||||
|
score: Math.round(accuracy * 100),
|
||||||
|
words
|
||||||
|
};
|
||||||
|
|
||||||
|
// Add to results
|
||||||
|
resultsData[username].push(sessionResult);
|
||||||
|
|
||||||
|
// Update totals
|
||||||
|
totalSessions++;
|
||||||
|
totalWords += numWords;
|
||||||
|
totalCorrect += correctWords;
|
||||||
|
|
||||||
|
// Add to activity log
|
||||||
|
activityLog.push({
|
||||||
|
type: 'session_completed',
|
||||||
|
timestamp: `${dateStr}T${generateTimeOfDay()}Z`,
|
||||||
|
details: {
|
||||||
|
sessionId,
|
||||||
|
score: Math.round(accuracy * 100),
|
||||||
|
words: numWords
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
// Occasionally add badge earning (1 in 10 sessions)
|
||||||
|
if (Math.random() < 0.1) {
|
||||||
|
const badges = [
|
||||||
|
"Perfect Round", "Speed Demon", "Word Wizard", "Consistent Learner",
|
||||||
|
"Weekly Warrior", "Quick Study", "No Misses"
|
||||||
|
];
|
||||||
|
const badge = badges[randomInt(0, badges.length - 1)];
|
||||||
|
|
||||||
|
activityLog.push({
|
||||||
|
type: 'badge_earned',
|
||||||
|
timestamp: `${dateStr}T${generateTimeOfDay()}Z`,
|
||||||
|
details: {
|
||||||
|
badge,
|
||||||
|
sessionId
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
points += randomInt(10, 50);
|
||||||
|
}
|
||||||
|
|
||||||
|
// Occasionally add challenge completion (1 in 8 sessions)
|
||||||
|
if (Math.random() < 0.125) {
|
||||||
|
const challengeTypes = ['daily', 'weekly', 'achievements'];
|
||||||
|
const challengeType = challengeTypes[randomInt(0, challengeTypes.length - 1)];
|
||||||
|
const challengeId = `${challengeType}-${dateStr}-${randomInt(1, 5)}`;
|
||||||
|
|
||||||
|
// Add to completed challenges
|
||||||
|
if (!progressData[username].challengesCompleted[challengeType].includes(challengeId)) {
|
||||||
|
progressData[username].challengesCompleted[challengeType].push(challengeId);
|
||||||
|
}
|
||||||
|
|
||||||
|
activityLog.push({
|
||||||
|
type: 'challenge_completed',
|
||||||
|
timestamp: `${dateStr}T${generateTimeOfDay()}Z`,
|
||||||
|
details: {
|
||||||
|
challengeId,
|
||||||
|
challengeType,
|
||||||
|
reward: {
|
||||||
|
points: randomInt(10, 50)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
points += randomInt(20, 100);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Calculate streak stats
|
||||||
|
const streakDays = streakDates.length;
|
||||||
|
const currentStreak = calculateCurrentStreak(streakDates, today);
|
||||||
|
const longestStreak = calculateLongestStreak(streakDates);
|
||||||
|
|
||||||
|
// Update progress data with calculated stats
|
||||||
|
progressData[username].stats = {
|
||||||
|
points,
|
||||||
|
totalSessions,
|
||||||
|
totalWords,
|
||||||
|
correctWords: totalCorrect,
|
||||||
|
accuracy: totalWords > 0 ? Math.round((totalCorrect / totalWords) * 1000) / 10 : 0
|
||||||
|
};
|
||||||
|
|
||||||
|
progressData[username].streaks = {
|
||||||
|
current: currentStreak,
|
||||||
|
longest: longestStreak,
|
||||||
|
dates: streakDates
|
||||||
|
};
|
||||||
|
|
||||||
|
progressData[username].activityLog = activityLog;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Save updated data
|
||||||
|
console.log('Saving updated results data...');
|
||||||
|
writeJsonSafe(files.results, resultsData);
|
||||||
|
|
||||||
|
console.log('Saving updated progress data...');
|
||||||
|
writeJsonSafe(files.progress, progressData);
|
||||||
|
|
||||||
|
console.log('Sample data generation complete!');
|
||||||
|
}
|
||||||
|
|
||||||
|
// Helper to calculate current streak
|
||||||
|
function calculateCurrentStreak(dates, today) {
|
||||||
|
if (!dates || dates.length === 0) return 0;
|
||||||
|
|
||||||
|
// Convert dates to Date objects for easier comparison
|
||||||
|
const sortedDates = [...dates].map(d => new Date(d)).sort((a, b) => b - a);
|
||||||
|
|
||||||
|
// Check if today is included
|
||||||
|
const todayStr = formatDate(today);
|
||||||
|
const hasTodayActivity = dates.includes(todayStr);
|
||||||
|
|
||||||
|
if (!hasTodayActivity) {
|
||||||
|
// Check if yesterday is included
|
||||||
|
const yesterday = subtractDays(today, 1);
|
||||||
|
const yesterdayStr = formatDate(yesterday);
|
||||||
|
const hasYesterdayActivity = dates.includes(yesterdayStr);
|
||||||
|
|
||||||
|
if (!hasYesterdayActivity) {
|
||||||
|
return 0; // Streak broken if neither today nor yesterday has activity
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Count consecutive days
|
||||||
|
let streak = hasTodayActivity ? 1 : 0;
|
||||||
|
let currentDate = hasTodayActivity ? subtractDays(today, 1) : subtractDays(today, 2);
|
||||||
|
|
||||||
|
while (true) {
|
||||||
|
const dateStr = formatDate(currentDate);
|
||||||
|
if (!dates.includes(dateStr)) {
|
||||||
|
break;
|
||||||
|
}
|
||||||
|
streak++;
|
||||||
|
currentDate = subtractDays(currentDate, 1);
|
||||||
|
}
|
||||||
|
|
||||||
|
return streak;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Helper to calculate longest streak
|
||||||
|
function calculateLongestStreak(dates) {
|
||||||
|
if (!dates || dates.length === 0) return 0;
|
||||||
|
|
||||||
|
// Convert dates to Date objects and sort
|
||||||
|
const sortedDates = [...dates].map(d => new Date(d)).sort((a, b) => a - b);
|
||||||
|
|
||||||
|
let longestStreak = 1;
|
||||||
|
let currentStreak = 1;
|
||||||
|
|
||||||
|
for (let i = 1; i < sortedDates.length; i++) {
|
||||||
|
const prevDate = sortedDates[i - 1];
|
||||||
|
const currentDate = sortedDates[i];
|
||||||
|
|
||||||
|
// Calculate difference in days
|
||||||
|
const diffTime = currentDate.getTime() - prevDate.getTime();
|
||||||
|
const diffDays = Math.round(diffTime / (1000 * 60 * 60 * 24));
|
||||||
|
|
||||||
|
if (diffDays === 1) {
|
||||||
|
// Consecutive day
|
||||||
|
currentStreak++;
|
||||||
|
if (currentStreak > longestStreak) {
|
||||||
|
longestStreak = currentStreak;
|
||||||
|
}
|
||||||
|
} else if (diffDays > 1) {
|
||||||
|
// Streak broken
|
||||||
|
currentStreak = 1;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
return longestStreak;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Execute the script
|
||||||
|
generateAnalyticsData();
|
||||||
@@ -0,0 +1,285 @@
|
|||||||
|
/**
|
||||||
|
* Generate sample gamification data for the Spelling Practice App
|
||||||
|
* This script will populate challenges and user progress with realistic data
|
||||||
|
*/
|
||||||
|
|
||||||
|
const fs = require('fs');
|
||||||
|
const path = require('path');
|
||||||
|
|
||||||
|
// Define paths
|
||||||
|
const DATA_DIR = path.join(__dirname, 'data');
|
||||||
|
const files = {
|
||||||
|
users: path.join(DATA_DIR, 'users.json'),
|
||||||
|
challenges: path.join(DATA_DIR, 'challenges.json'),
|
||||||
|
progress: path.join(DATA_DIR, 'progress.json')
|
||||||
|
};
|
||||||
|
|
||||||
|
// Helper functions
|
||||||
|
function readJsonSafe(filePath, defaultValue = {}) {
|
||||||
|
try {
|
||||||
|
if (fs.existsSync(filePath)) {
|
||||||
|
const content = fs.readFileSync(filePath, 'utf8');
|
||||||
|
return JSON.parse(content);
|
||||||
|
}
|
||||||
|
return defaultValue;
|
||||||
|
} catch (error) {
|
||||||
|
console.error(`Error reading ${filePath}:`, error);
|
||||||
|
return defaultValue;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
function writeJsonSafe(filePath, data) {
|
||||||
|
try {
|
||||||
|
fs.writeFileSync(filePath, JSON.stringify(data, null, 2));
|
||||||
|
return true;
|
||||||
|
} catch (error) {
|
||||||
|
console.error(`Error writing to ${filePath}:`, error);
|
||||||
|
return false;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Random helpers
|
||||||
|
function randomInt(min, max) {
|
||||||
|
return Math.floor(Math.random() * (max - min + 1) + min);
|
||||||
|
}
|
||||||
|
|
||||||
|
// Date helpers
|
||||||
|
function formatDate(date) {
|
||||||
|
return date.toISOString().split('T')[0];
|
||||||
|
}
|
||||||
|
|
||||||
|
function subtractDays(date, days) {
|
||||||
|
const result = new Date(date);
|
||||||
|
result.setDate(result.getDate() - days);
|
||||||
|
return result;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Generate sample challenges
|
||||||
|
function generateChallenges() {
|
||||||
|
const challenges = {
|
||||||
|
daily: [
|
||||||
|
{
|
||||||
|
id: "daily-practice-10",
|
||||||
|
name: "Practice Makes Perfect",
|
||||||
|
description: "Complete 10 practice words in a day",
|
||||||
|
type: "daily",
|
||||||
|
target: 10,
|
||||||
|
points: 50,
|
||||||
|
icon: "🎯"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
id: "daily-accuracy-90",
|
||||||
|
name: "Sharp Shooter",
|
||||||
|
description: "Achieve 90% accuracy in daily practice",
|
||||||
|
type: "daily",
|
||||||
|
target: 0.9,
|
||||||
|
points: 75,
|
||||||
|
icon: "🎯"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
id: "daily-streak-3",
|
||||||
|
name: "On Fire",
|
||||||
|
description: "Get 3 words correct in a row",
|
||||||
|
type: "daily",
|
||||||
|
target: 3,
|
||||||
|
points: 30,
|
||||||
|
icon: "🔥"
|
||||||
|
}
|
||||||
|
],
|
||||||
|
weekly: [
|
||||||
|
{
|
||||||
|
id: "weekly-words-50",
|
||||||
|
name: "Word Warrior",
|
||||||
|
description: "Practice 50 words in a week",
|
||||||
|
type: "weekly",
|
||||||
|
target: 50,
|
||||||
|
points: 200,
|
||||||
|
icon: "⚔️"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
id: "weekly-days-5",
|
||||||
|
name: "Dedicated Scholar",
|
||||||
|
description: "Practice on 5 different days this week",
|
||||||
|
type: "weekly",
|
||||||
|
target: 5,
|
||||||
|
points: 250,
|
||||||
|
icon: "📚"
|
||||||
|
}
|
||||||
|
],
|
||||||
|
achievements: [
|
||||||
|
{
|
||||||
|
id: "achievement-words-100",
|
||||||
|
name: "Century Club",
|
||||||
|
description: "Practice 100 total words",
|
||||||
|
type: "achievement",
|
||||||
|
target: 100,
|
||||||
|
points: 100,
|
||||||
|
icon: "🏆"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
id: "achievement-words-500",
|
||||||
|
name: "Word Master",
|
||||||
|
description: "Practice 500 total words",
|
||||||
|
type: "achievement",
|
||||||
|
target: 500,
|
||||||
|
points: 500,
|
||||||
|
icon: "👑"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
id: "achievement-streak-7",
|
||||||
|
name: "Weekly Warrior",
|
||||||
|
description: "Maintain a 7-day practice streak",
|
||||||
|
type: "achievement",
|
||||||
|
target: 7,
|
||||||
|
points: 300,
|
||||||
|
icon: "📅"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
id: "achievement-accuracy-95",
|
||||||
|
name: "Spelling Bee Champion",
|
||||||
|
description: "Maintain 95% accuracy across 100 words",
|
||||||
|
type: "achievement",
|
||||||
|
target: 0.95,
|
||||||
|
points: 400,
|
||||||
|
icon: "🐝"
|
||||||
|
}
|
||||||
|
]
|
||||||
|
};
|
||||||
|
|
||||||
|
return challenges;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Generate progress data for a user
|
||||||
|
function generateUserProgress(username) {
|
||||||
|
const today = new Date();
|
||||||
|
|
||||||
|
// Generate streak data
|
||||||
|
const currentStreak = randomInt(1, 14);
|
||||||
|
const longestStreak = Math.max(currentStreak, randomInt(7, 21));
|
||||||
|
|
||||||
|
// Generate points from challenges and achievements
|
||||||
|
const totalPoints = randomInt(500, 2000);
|
||||||
|
|
||||||
|
// Generate completed challenges
|
||||||
|
const dailyChallenges = [];
|
||||||
|
const weeklyChallenges = [];
|
||||||
|
const achievements = [];
|
||||||
|
|
||||||
|
// Generate some daily challenges for the past 14 days
|
||||||
|
for (let i = 0; i < 14; i++) {
|
||||||
|
const date = formatDate(subtractDays(today, i));
|
||||||
|
|
||||||
|
// 70% chance to have completed some daily challenges
|
||||||
|
if (Math.random() < 0.7) {
|
||||||
|
// Random selection of daily challenges
|
||||||
|
const dailyIds = ["daily-practice-10", "daily-accuracy-90", "daily-streak-3"];
|
||||||
|
const completedCount = randomInt(1, dailyIds.length);
|
||||||
|
|
||||||
|
for (let j = 0; j < completedCount; j++) {
|
||||||
|
dailyChallenges.push({
|
||||||
|
id: dailyIds[j],
|
||||||
|
date,
|
||||||
|
progress: 1.0 // 100% complete
|
||||||
|
});
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Generate weekly challenges for the past 4 weeks
|
||||||
|
for (let i = 0; i < 4; i++) {
|
||||||
|
const weekStart = formatDate(subtractDays(today, 7 * (i + 1)));
|
||||||
|
|
||||||
|
// 60% chance to have completed a weekly challenge
|
||||||
|
if (Math.random() < 0.6) {
|
||||||
|
const weeklyIds = ["weekly-words-50", "weekly-days-5"];
|
||||||
|
const completedId = weeklyIds[randomInt(0, weeklyIds.length - 1)];
|
||||||
|
|
||||||
|
weeklyChallenges.push({
|
||||||
|
id: completedId,
|
||||||
|
weekStart,
|
||||||
|
progress: 1.0
|
||||||
|
});
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Generate achievements (randomly completed)
|
||||||
|
const achievementIds = [
|
||||||
|
"achievement-words-100",
|
||||||
|
"achievement-words-500",
|
||||||
|
"achievement-streak-7",
|
||||||
|
"achievement-accuracy-95"
|
||||||
|
];
|
||||||
|
|
||||||
|
// 30-70% of achievements completed
|
||||||
|
const completedCount = randomInt(
|
||||||
|
Math.floor(achievementIds.length * 0.3),
|
||||||
|
Math.floor(achievementIds.length * 0.7)
|
||||||
|
);
|
||||||
|
|
||||||
|
for (let i = 0; i < completedCount; i++) {
|
||||||
|
const achievementId = achievementIds[i];
|
||||||
|
const daysAgo = randomInt(1, 30);
|
||||||
|
|
||||||
|
achievements.push({
|
||||||
|
id: achievementId,
|
||||||
|
date: formatDate(subtractDays(today, daysAgo)),
|
||||||
|
progress: 1.0
|
||||||
|
});
|
||||||
|
}
|
||||||
|
|
||||||
|
// Overall user progress data
|
||||||
|
return {
|
||||||
|
streak: {
|
||||||
|
current: currentStreak,
|
||||||
|
longest: longestStreak,
|
||||||
|
lastPractice: formatDate(subtractDays(today, 1)) // Yesterday
|
||||||
|
},
|
||||||
|
points: totalPoints,
|
||||||
|
level: Math.floor(totalPoints / 500) + 1, // Level up every 500 points
|
||||||
|
dailyChallenges,
|
||||||
|
weeklyChallenges,
|
||||||
|
achievements,
|
||||||
|
stats: {
|
||||||
|
wordsAttempted: randomInt(100, 1000),
|
||||||
|
wordsCorrect: randomInt(70, 95) / 100 * randomInt(100, 1000),
|
||||||
|
sessionsCompleted: randomInt(20, 100),
|
||||||
|
averageAccuracy: randomInt(70, 98) / 100
|
||||||
|
}
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
// Main function to generate gamification data
|
||||||
|
async function generateGamificationData() {
|
||||||
|
console.log('Generating sample gamification data...');
|
||||||
|
|
||||||
|
// Load users
|
||||||
|
const users = readJsonSafe(files.users, []);
|
||||||
|
|
||||||
|
if (users.length === 0) {
|
||||||
|
console.error('No users found. Please ensure users exist before running this script.');
|
||||||
|
return;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Generate challenges
|
||||||
|
console.log('Generating challenges data...');
|
||||||
|
const challenges = generateChallenges();
|
||||||
|
|
||||||
|
// Generate progress for each user
|
||||||
|
const progress = {};
|
||||||
|
|
||||||
|
for (const user of users) {
|
||||||
|
const username = user.username;
|
||||||
|
console.log(`Generating progress data for user: ${username}`);
|
||||||
|
progress[username] = generateUserProgress(username);
|
||||||
|
}
|
||||||
|
|
||||||
|
// Save data
|
||||||
|
console.log('Saving challenges and progress data...');
|
||||||
|
writeJsonSafe(files.challenges, challenges);
|
||||||
|
writeJsonSafe(files.progress, progress);
|
||||||
|
|
||||||
|
console.log('Gamification data generation complete!');
|
||||||
|
}
|
||||||
|
|
||||||
|
// Execute the script
|
||||||
|
generateGamificationData();
|
||||||
@@ -0,0 +1,242 @@
|
|||||||
|
/**
|
||||||
|
* Generate sample leaderboard data for the Spelling Practice App
|
||||||
|
* This script will populate leaderboards with realistic data for the analytics dashboard
|
||||||
|
*/
|
||||||
|
|
||||||
|
const fs = require('fs');
|
||||||
|
const path = require('path');
|
||||||
|
|
||||||
|
// Define paths
|
||||||
|
const DATA_DIR = path.join(__dirname, 'data');
|
||||||
|
const files = {
|
||||||
|
users: path.join(DATA_DIR, 'users.json'),
|
||||||
|
progress: path.join(DATA_DIR, 'progress.json'),
|
||||||
|
leaderboards: path.join(DATA_DIR, 'leaderboards.json')
|
||||||
|
};
|
||||||
|
|
||||||
|
// Helper functions
|
||||||
|
function readJsonSafe(filePath, defaultValue = {}) {
|
||||||
|
try {
|
||||||
|
if (fs.existsSync(filePath)) {
|
||||||
|
const content = fs.readFileSync(filePath, 'utf8');
|
||||||
|
return JSON.parse(content);
|
||||||
|
}
|
||||||
|
return defaultValue;
|
||||||
|
} catch (error) {
|
||||||
|
console.error(`Error reading ${filePath}:`, error);
|
||||||
|
return defaultValue;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
function writeJsonSafe(filePath, data) {
|
||||||
|
try {
|
||||||
|
fs.writeFileSync(filePath, JSON.stringify(data, null, 2));
|
||||||
|
return true;
|
||||||
|
} catch (error) {
|
||||||
|
console.error(`Error writing to ${filePath}:`, error);
|
||||||
|
return false;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Random helpers
|
||||||
|
function randomInt(min, max) {
|
||||||
|
return Math.floor(Math.random() * (max - min + 1) + min);
|
||||||
|
}
|
||||||
|
|
||||||
|
function randomFloat(min, max, decimals = 2) {
|
||||||
|
const rand = Math.random() * (max - min) + min;
|
||||||
|
return parseFloat(rand.toFixed(decimals));
|
||||||
|
}
|
||||||
|
|
||||||
|
// Generate additional fake users for the leaderboards
|
||||||
|
function generateFakeUsers(count) {
|
||||||
|
const firstNames = ['Emma', 'Liam', 'Olivia', 'Noah', 'Ava', 'William', 'Sophia', 'James', 'Isabella', 'Logan',
|
||||||
|
'Mia', 'Benjamin', 'Charlotte', 'Mason', 'Amelia', 'Elijah', 'Harper', 'Oliver', 'Evelyn', 'Jacob'];
|
||||||
|
|
||||||
|
const lastNames = ['Smith', 'Johnson', 'Williams', 'Brown', 'Jones', 'Garcia', 'Miller', 'Davis', 'Rodriguez', 'Martinez',
|
||||||
|
'Hernandez', 'Lopez', 'Gonzalez', 'Wilson', 'Anderson', 'Thomas', 'Taylor', 'Moore', 'Jackson', 'Martin'];
|
||||||
|
|
||||||
|
const users = [];
|
||||||
|
|
||||||
|
for (let i = 0; i < count; i++) {
|
||||||
|
const firstName = firstNames[randomInt(0, firstNames.length - 1)];
|
||||||
|
const lastName = lastNames[randomInt(0, lastNames.length - 1)];
|
||||||
|
const username = `${firstName.toLowerCase()}${lastName.substring(0, 1).toLowerCase()}${randomInt(1, 99)}`;
|
||||||
|
|
||||||
|
users.push(username);
|
||||||
|
}
|
||||||
|
|
||||||
|
return users;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Main function to generate leaderboard data
|
||||||
|
async function generateLeaderboardData() {
|
||||||
|
console.log('Generating sample leaderboard data...');
|
||||||
|
|
||||||
|
// Load users and progress data
|
||||||
|
const users = readJsonSafe(files.users, []);
|
||||||
|
const progressData = readJsonSafe(files.progress, {});
|
||||||
|
|
||||||
|
if (users.length === 0) {
|
||||||
|
console.error('No users found. Please ensure users exist before running this script.');
|
||||||
|
return;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Generate 10 additional fake users for leaderboards
|
||||||
|
const fakeUsers = generateFakeUsers(10);
|
||||||
|
const allUsers = [...users.map(u => u.username), ...fakeUsers];
|
||||||
|
|
||||||
|
// Create leaderboard data
|
||||||
|
const leaderboards = {
|
||||||
|
allTime: {
|
||||||
|
accuracy: [],
|
||||||
|
totalWords: [],
|
||||||
|
sessionsCompleted: [],
|
||||||
|
streakDays: []
|
||||||
|
},
|
||||||
|
weekly: {
|
||||||
|
accuracy: [],
|
||||||
|
totalWords: [],
|
||||||
|
sessionsCompleted: []
|
||||||
|
},
|
||||||
|
currentWeek: `${new Date().getFullYear()}-${Math.ceil((new Date().getDate() + new Date().getDay()) / 7)}`
|
||||||
|
};
|
||||||
|
|
||||||
|
// Generate data for each category
|
||||||
|
|
||||||
|
// All-time accuracy leaderboard
|
||||||
|
allUsers.forEach(username => {
|
||||||
|
// For real users, use their actual progress data if available
|
||||||
|
if (progressData[username]) {
|
||||||
|
leaderboards.allTime.accuracy.push({
|
||||||
|
username,
|
||||||
|
value: progressData[username].stats.accuracy || randomFloat(70, 98, 1),
|
||||||
|
timestamp: new Date().toISOString()
|
||||||
|
});
|
||||||
|
} else {
|
||||||
|
// For fake users, generate random data
|
||||||
|
leaderboards.allTime.accuracy.push({
|
||||||
|
username,
|
||||||
|
value: randomFloat(70, 98, 1),
|
||||||
|
timestamp: new Date().toISOString()
|
||||||
|
});
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
// Sort by value (descending)
|
||||||
|
leaderboards.allTime.accuracy.sort((a, b) => b.value - a.value);
|
||||||
|
|
||||||
|
// All-time totalWords leaderboard
|
||||||
|
allUsers.forEach(username => {
|
||||||
|
if (progressData[username]) {
|
||||||
|
leaderboards.allTime.totalWords.push({
|
||||||
|
username,
|
||||||
|
value: progressData[username].stats.totalWords || randomInt(100, 1000),
|
||||||
|
timestamp: new Date().toISOString()
|
||||||
|
});
|
||||||
|
} else {
|
||||||
|
leaderboards.allTime.totalWords.push({
|
||||||
|
username,
|
||||||
|
value: randomInt(100, 1000),
|
||||||
|
timestamp: new Date().toISOString()
|
||||||
|
});
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
leaderboards.allTime.totalWords.sort((a, b) => b.value - a.value);
|
||||||
|
|
||||||
|
// All-time sessionsCompleted leaderboard
|
||||||
|
allUsers.forEach(username => {
|
||||||
|
if (progressData[username]) {
|
||||||
|
leaderboards.allTime.sessionsCompleted.push({
|
||||||
|
username,
|
||||||
|
value: progressData[username].stats.totalSessions || randomInt(5, 50),
|
||||||
|
timestamp: new Date().toISOString()
|
||||||
|
});
|
||||||
|
} else {
|
||||||
|
leaderboards.allTime.sessionsCompleted.push({
|
||||||
|
username,
|
||||||
|
value: randomInt(5, 50),
|
||||||
|
timestamp: new Date().toISOString()
|
||||||
|
});
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
leaderboards.allTime.sessionsCompleted.sort((a, b) => b.value - a.value);
|
||||||
|
|
||||||
|
// All-time streakDays leaderboard
|
||||||
|
allUsers.forEach(username => {
|
||||||
|
if (progressData[username]) {
|
||||||
|
leaderboards.allTime.streakDays.push({
|
||||||
|
username,
|
||||||
|
value: progressData[username].streaks?.longest || randomInt(1, 14),
|
||||||
|
timestamp: new Date().toISOString()
|
||||||
|
});
|
||||||
|
} else {
|
||||||
|
leaderboards.allTime.streakDays.push({
|
||||||
|
username,
|
||||||
|
value: randomInt(1, 14),
|
||||||
|
timestamp: new Date().toISOString()
|
||||||
|
});
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
leaderboards.allTime.streakDays.sort((a, b) => b.value - a.value);
|
||||||
|
|
||||||
|
// Generate weekly leaderboards
|
||||||
|
// Copy from all-time but with different values
|
||||||
|
|
||||||
|
// Weekly accuracy
|
||||||
|
allUsers.forEach(username => {
|
||||||
|
const allTimeEntry = leaderboards.allTime.accuracy.find(entry => entry.username === username);
|
||||||
|
const baseValue = allTimeEntry ? allTimeEntry.value : randomFloat(70, 98, 1);
|
||||||
|
|
||||||
|
// Weekly value is slightly different from all-time
|
||||||
|
leaderboards.weekly.accuracy.push({
|
||||||
|
username,
|
||||||
|
value: Math.min(99.9, Math.max(50, baseValue + randomFloat(-5, 5, 1))),
|
||||||
|
timestamp: new Date().toISOString()
|
||||||
|
});
|
||||||
|
});
|
||||||
|
|
||||||
|
leaderboards.weekly.accuracy.sort((a, b) => b.value - a.value);
|
||||||
|
|
||||||
|
// Weekly totalWords
|
||||||
|
allUsers.forEach(username => {
|
||||||
|
const allTimeEntry = leaderboards.allTime.totalWords.find(entry => entry.username === username);
|
||||||
|
const baseValue = allTimeEntry ? allTimeEntry.value : randomInt(100, 1000);
|
||||||
|
|
||||||
|
// Weekly value is much smaller than all-time
|
||||||
|
leaderboards.weekly.totalWords.push({
|
||||||
|
username,
|
||||||
|
value: randomInt(10, Math.min(100, Math.floor(baseValue / 10))),
|
||||||
|
timestamp: new Date().toISOString()
|
||||||
|
});
|
||||||
|
});
|
||||||
|
|
||||||
|
leaderboards.weekly.totalWords.sort((a, b) => b.value - a.value);
|
||||||
|
|
||||||
|
// Weekly sessionsCompleted
|
||||||
|
allUsers.forEach(username => {
|
||||||
|
const allTimeEntry = leaderboards.allTime.sessionsCompleted.find(entry => entry.username === username);
|
||||||
|
const baseValue = allTimeEntry ? allTimeEntry.value : randomInt(5, 50);
|
||||||
|
|
||||||
|
// Weekly value is much smaller than all-time
|
||||||
|
leaderboards.weekly.sessionsCompleted.push({
|
||||||
|
username,
|
||||||
|
value: randomInt(1, Math.min(7, Math.floor(baseValue / 5))),
|
||||||
|
timestamp: new Date().toISOString()
|
||||||
|
});
|
||||||
|
});
|
||||||
|
|
||||||
|
leaderboards.weekly.sessionsCompleted.sort((a, b) => b.value - a.value);
|
||||||
|
|
||||||
|
// Save the leaderboard data
|
||||||
|
console.log('Saving leaderboard data...');
|
||||||
|
writeJsonSafe(files.leaderboards, leaderboards);
|
||||||
|
|
||||||
|
console.log('Leaderboard data generation complete!');
|
||||||
|
}
|
||||||
|
|
||||||
|
// Execute the script
|
||||||
|
generateLeaderboardData();
|
||||||
@@ -0,0 +1,222 @@
|
|||||||
|
/**
|
||||||
|
* Generate sample spaced repetition data for the Spelling Practice App
|
||||||
|
* This script will populate the spaced repetition system with realistic learning data
|
||||||
|
*/
|
||||||
|
|
||||||
|
const fs = require('fs');
|
||||||
|
const path = require('path');
|
||||||
|
|
||||||
|
// Define paths
|
||||||
|
const DATA_DIR = path.join(__dirname, 'data');
|
||||||
|
const files = {
|
||||||
|
users: path.join(DATA_DIR, 'users.json'),
|
||||||
|
wordlists: path.join(DATA_DIR, 'wordlists.json'),
|
||||||
|
spacedRepetition: path.join(DATA_DIR, 'spacedRepetition.json')
|
||||||
|
};
|
||||||
|
|
||||||
|
// Helper functions
|
||||||
|
function readJsonSafe(filePath, defaultValue = {}) {
|
||||||
|
try {
|
||||||
|
if (fs.existsSync(filePath)) {
|
||||||
|
const content = fs.readFileSync(filePath, 'utf8');
|
||||||
|
return JSON.parse(content);
|
||||||
|
}
|
||||||
|
return defaultValue;
|
||||||
|
} catch (error) {
|
||||||
|
console.error(`Error reading ${filePath}:`, error);
|
||||||
|
return defaultValue;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
function writeJsonSafe(filePath, data) {
|
||||||
|
try {
|
||||||
|
fs.writeFileSync(filePath, JSON.stringify(data, null, 2));
|
||||||
|
return true;
|
||||||
|
} catch (error) {
|
||||||
|
console.error(`Error writing to ${filePath}:`, error);
|
||||||
|
return false;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Random helpers
|
||||||
|
function randomInt(min, max) {
|
||||||
|
return Math.floor(Math.random() * (max - min + 1) + min);
|
||||||
|
}
|
||||||
|
|
||||||
|
function randomFloat(min, max, decimals = 2) {
|
||||||
|
const rand = Math.random() * (max - min) + min;
|
||||||
|
return parseFloat(rand.toFixed(decimals));
|
||||||
|
}
|
||||||
|
|
||||||
|
// Date helpers
|
||||||
|
function addDays(date, days) {
|
||||||
|
const result = new Date(date);
|
||||||
|
result.setDate(result.getDate() + days);
|
||||||
|
return result;
|
||||||
|
}
|
||||||
|
|
||||||
|
function subtractDays(date, days) {
|
||||||
|
return addDays(date, -days);
|
||||||
|
}
|
||||||
|
|
||||||
|
function formatDate(date) {
|
||||||
|
return date.toISOString().split('T')[0];
|
||||||
|
}
|
||||||
|
|
||||||
|
// Main function to generate spaced repetition data
|
||||||
|
async function generateSpacedRepetitionData() {
|
||||||
|
console.log('Generating sample spaced repetition data...');
|
||||||
|
|
||||||
|
// Load users and wordlists
|
||||||
|
const users = readJsonSafe(files.users, []);
|
||||||
|
const wordlists = readJsonSafe(files.wordlists, {});
|
||||||
|
|
||||||
|
if (users.length === 0) {
|
||||||
|
console.error('No users found. Please ensure users exist before running this script.');
|
||||||
|
return;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Create spaced repetition data structure
|
||||||
|
const srData = readJsonSafe(files.spacedRepetition, {});
|
||||||
|
|
||||||
|
// Generate data for each user
|
||||||
|
const today = new Date();
|
||||||
|
|
||||||
|
for (const user of users) {
|
||||||
|
const username = user.username;
|
||||||
|
console.log(`Generating spaced repetition data for user: ${username}`);
|
||||||
|
|
||||||
|
// Get user's words
|
||||||
|
let userWords = [];
|
||||||
|
|
||||||
|
// Handle different wordlist structures
|
||||||
|
if (Array.isArray(wordlists[username])) {
|
||||||
|
userWords = wordlists[username];
|
||||||
|
} else if (wordlists[username] && wordlists[username].weeks && Array.isArray(wordlists[username].weeks)) {
|
||||||
|
// Extract all words from all weeks
|
||||||
|
wordlists[username].weeks.forEach(week => {
|
||||||
|
if (week.words && Array.isArray(week.words)) {
|
||||||
|
userWords = [...userWords, ...week.words];
|
||||||
|
}
|
||||||
|
});
|
||||||
|
}
|
||||||
|
|
||||||
|
if (userWords.length === 0) {
|
||||||
|
console.log(`No words found for user ${username}. Skipping...`);
|
||||||
|
continue;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Initialize user's spaced repetition data if not exists
|
||||||
|
if (!srData[username]) {
|
||||||
|
srData[username] = {
|
||||||
|
settings: {
|
||||||
|
dailyLimit: 20,
|
||||||
|
reviewThreshold: 3,
|
||||||
|
newWordsPerDay: 5
|
||||||
|
},
|
||||||
|
stats: {
|
||||||
|
totalReviews: 0,
|
||||||
|
correctReviews: 0,
|
||||||
|
totalWords: 0,
|
||||||
|
masteredWords: 0
|
||||||
|
},
|
||||||
|
words: {}
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
// Add words with different mastery levels
|
||||||
|
let totalReviews = 0;
|
||||||
|
let correctReviews = 0;
|
||||||
|
let masteredWords = 0;
|
||||||
|
|
||||||
|
for (const word of userWords) {
|
||||||
|
// Determine mastery level
|
||||||
|
// 0: New - 20%
|
||||||
|
// 1-2: Learning - 30%
|
||||||
|
// 3-4: Reviewing - 30%
|
||||||
|
// 5+: Mastered - 20%
|
||||||
|
|
||||||
|
const rand = Math.random();
|
||||||
|
let repetitions = 0;
|
||||||
|
let interval = 0;
|
||||||
|
let easeFactor = 2.5;
|
||||||
|
|
||||||
|
if (rand < 0.2) {
|
||||||
|
// New word
|
||||||
|
repetitions = 0;
|
||||||
|
interval = 0;
|
||||||
|
easeFactor = randomFloat(2.3, 2.7, 1);
|
||||||
|
} else if (rand < 0.5) {
|
||||||
|
// Learning
|
||||||
|
repetitions = randomInt(1, 2);
|
||||||
|
interval = repetitions === 1 ? 1 : 3;
|
||||||
|
easeFactor = randomFloat(2.0, 2.5, 1);
|
||||||
|
totalReviews += repetitions;
|
||||||
|
correctReviews += repetitions - 1;
|
||||||
|
} else if (rand < 0.8) {
|
||||||
|
// Reviewing
|
||||||
|
repetitions = randomInt(3, 4);
|
||||||
|
interval = repetitions === 3 ? 7 : 15;
|
||||||
|
easeFactor = randomFloat(2.2, 2.8, 1);
|
||||||
|
totalReviews += repetitions;
|
||||||
|
correctReviews += repetitions - 1;
|
||||||
|
} else {
|
||||||
|
// Mastered
|
||||||
|
repetitions = randomInt(5, 8);
|
||||||
|
interval = Math.pow(2, repetitions - 4) * 10; // Exponential increase
|
||||||
|
easeFactor = randomFloat(2.6, 3.0, 1);
|
||||||
|
totalReviews += repetitions;
|
||||||
|
correctReviews += repetitions - 1;
|
||||||
|
masteredWords++;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Calculate last and next review dates
|
||||||
|
let nextReview = null;
|
||||||
|
let lastReview = null;
|
||||||
|
|
||||||
|
if (repetitions > 0) {
|
||||||
|
// If the word has been reviewed before, set lastReview
|
||||||
|
lastReview = formatDate(subtractDays(today, randomInt(1, interval)));
|
||||||
|
|
||||||
|
// Next review might be due
|
||||||
|
const dueChance = 0.3; // 30% chance word is due
|
||||||
|
if (Math.random() < dueChance) {
|
||||||
|
// Word is due today or in the past
|
||||||
|
nextReview = formatDate(subtractDays(today, randomInt(0, 3)));
|
||||||
|
} else {
|
||||||
|
// Word is due in the future
|
||||||
|
nextReview = formatDate(addDays(today, randomInt(1, interval)));
|
||||||
|
}
|
||||||
|
} else {
|
||||||
|
// New word, not reviewed yet
|
||||||
|
nextReview = formatDate(today);
|
||||||
|
}
|
||||||
|
|
||||||
|
// Add word to user's SR data
|
||||||
|
srData[username].words[word] = {
|
||||||
|
easeFactor,
|
||||||
|
interval,
|
||||||
|
repetitions,
|
||||||
|
lastReview,
|
||||||
|
nextReview
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
// Update user stats
|
||||||
|
srData[username].stats = {
|
||||||
|
totalReviews,
|
||||||
|
correctReviews,
|
||||||
|
totalWords: userWords.length,
|
||||||
|
masteredWords
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
// Save spaced repetition data
|
||||||
|
console.log('Saving spaced repetition data...');
|
||||||
|
writeJsonSafe(files.spacedRepetition, srData);
|
||||||
|
|
||||||
|
console.log('Spaced repetition data generation complete!');
|
||||||
|
}
|
||||||
|
|
||||||
|
// Execute the script
|
||||||
|
generateSpacedRepetitionData();
|
||||||
+117
@@ -0,0 +1,117 @@
|
|||||||
|
// Health check script for the Spelling Practice app
|
||||||
|
// Run this to verify all the fixes are working properly
|
||||||
|
|
||||||
|
const fs = require('fs');
|
||||||
|
const path = require('path');
|
||||||
|
const http = require('http');
|
||||||
|
|
||||||
|
console.log('🔍 Running health check...');
|
||||||
|
|
||||||
|
// Define directories and files
|
||||||
|
const DATA_DIR = path.join(__dirname, 'data');
|
||||||
|
const SEED_DIR = path.join(__dirname, 'seed');
|
||||||
|
const PUBLIC_DIR = path.join(__dirname, 'public');
|
||||||
|
const JS_DIR = path.join(PUBLIC_DIR, 'js');
|
||||||
|
|
||||||
|
const files = {
|
||||||
|
users: path.join(DATA_DIR, 'users.json'),
|
||||||
|
wordlists: path.join(DATA_DIR, 'wordlists.json'),
|
||||||
|
results: path.join(DATA_DIR, 'results.json'),
|
||||||
|
badges: path.join(DATA_DIR, 'badges.json'),
|
||||||
|
leaderboards: path.join(DATA_DIR, 'leaderboards.json'),
|
||||||
|
challenges: path.join(DATA_DIR, 'challenges.json'),
|
||||||
|
progress: path.join(DATA_DIR, 'progress.json'),
|
||||||
|
spacedRepetition: path.join(DATA_DIR, 'spacedRepetition.json')
|
||||||
|
};
|
||||||
|
|
||||||
|
// Check directories
|
||||||
|
console.log('📁 Checking directories...');
|
||||||
|
[DATA_DIR, PUBLIC_DIR, JS_DIR].forEach(dir => {
|
||||||
|
if (fs.existsSync(dir)) {
|
||||||
|
console.log(`✅ ${path.basename(dir)} directory exists`);
|
||||||
|
} else {
|
||||||
|
console.error(`❌ ${path.basename(dir)} directory is missing!`);
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
// Check required data files
|
||||||
|
console.log('\n🗃️ Checking data files...');
|
||||||
|
Object.entries(files).forEach(([name, filePath]) => {
|
||||||
|
if (fs.existsSync(filePath)) {
|
||||||
|
try {
|
||||||
|
const content = fs.readFileSync(filePath, 'utf-8');
|
||||||
|
const data = JSON.parse(content);
|
||||||
|
|
||||||
|
if (name === 'users') {
|
||||||
|
console.log(`✅ ${name}: Found ${data.length} users: ${data.map(u => u.username).join(', ')}`);
|
||||||
|
} else {
|
||||||
|
console.log(`✅ ${name}: Valid JSON (${content.length} bytes)`);
|
||||||
|
}
|
||||||
|
} catch (e) {
|
||||||
|
console.error(`❌ ${name}: Invalid JSON - ${e.message}`);
|
||||||
|
}
|
||||||
|
} else {
|
||||||
|
console.error(`❌ ${name}: File not found!`);
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
// Check critical JS files
|
||||||
|
console.log('\n📜 Checking JS files...');
|
||||||
|
const jsFiles = [
|
||||||
|
'admin.js', 'analytics.js', 'auth.js', 'game.js', 'main.js',
|
||||||
|
'ui.js', 'init.js', 'debug-analytics.js'
|
||||||
|
];
|
||||||
|
|
||||||
|
jsFiles.forEach(file => {
|
||||||
|
const filePath = path.join(JS_DIR, file);
|
||||||
|
if (fs.existsSync(filePath)) {
|
||||||
|
const content = fs.readFileSync(filePath, 'utf-8');
|
||||||
|
console.log(`✅ ${file}: ${content.length} bytes`);
|
||||||
|
|
||||||
|
// Look for specific fixed patterns
|
||||||
|
if (file === 'admin.js') {
|
||||||
|
if (content.includes('window.adminUsers')) {
|
||||||
|
console.log(` ✅ admin.js: Global adminUsers variable found`);
|
||||||
|
} else {
|
||||||
|
console.warn(` ⚠️ admin.js: Global adminUsers variable not found`);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
if (file === 'analytics.js') {
|
||||||
|
if (content.includes('window.analyticsRefresh')) {
|
||||||
|
console.log(` ✅ analytics.js: Global analyticsRefresh function found`);
|
||||||
|
} else {
|
||||||
|
console.warn(` ⚠️ analytics.js: Global analyticsRefresh function not found`);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
if (file === 'ui.js') {
|
||||||
|
if (content.includes('window.switchTab')) {
|
||||||
|
console.log(` ✅ ui.js: Global switchTab function found`);
|
||||||
|
} else {
|
||||||
|
console.warn(` ⚠️ ui.js: Global switchTab function not found`);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
} else {
|
||||||
|
console.error(`❌ ${file}: File not found!`);
|
||||||
|
}
|
||||||
|
});
|
||||||
|
|
||||||
|
// Check package.json
|
||||||
|
console.log('\n📦 Checking package.json...');
|
||||||
|
const pkgPath = path.join(__dirname, 'package.json');
|
||||||
|
if (fs.existsSync(pkgPath)) {
|
||||||
|
try {
|
||||||
|
const pkg = JSON.parse(fs.readFileSync(pkgPath, 'utf-8'));
|
||||||
|
console.log(`✅ Package name: ${pkg.name}`);
|
||||||
|
console.log(`✅ Version: ${pkg.version}`);
|
||||||
|
console.log(`✅ Dependencies: ${Object.keys(pkg.dependencies || {}).length}`);
|
||||||
|
} catch (e) {
|
||||||
|
console.error(`❌ Invalid package.json: ${e.message}`);
|
||||||
|
}
|
||||||
|
} else {
|
||||||
|
console.error('❌ package.json not found!');
|
||||||
|
}
|
||||||
|
|
||||||
|
console.log('\n🏁 Health check complete!');
|
||||||
|
console.log('To test the application, run node server.js and open http://localhost:3000');
|
||||||
+948
@@ -0,0 +1,948 @@
|
|||||||
|
{
|
||||||
|
"name": "modern-spelling-practice",
|
||||||
|
"version": "3.0.0",
|
||||||
|
"lockfileVersion": 3,
|
||||||
|
"requires": true,
|
||||||
|
"packages": {
|
||||||
|
"node_modules/accepts": {
|
||||||
|
"version": "2.0.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/accepts/-/accepts-2.0.0.tgz",
|
||||||
|
"integrity": "sha512-5cvg6CtKwfgdmVqY1WIiXKc3Q1bkRqGLi+2W/6ao+6Y7gu/RCwRuAhGEzh5B4KlszSuTLgZYuqFqo5bImjNKng==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"mime-types": "^3.0.0",
|
||||||
|
"negotiator": "^1.0.0"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.6"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/body-parser": {
|
||||||
|
"version": "2.2.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/body-parser/-/body-parser-2.2.0.tgz",
|
||||||
|
"integrity": "sha512-02qvAaxv8tp7fBa/mw1ga98OGm+eCbqzJOKoRt70sLmfEEi+jyBYVTDGfCL/k06/4EMk/z01gCe7HoCH/f2LTg==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"bytes": "^3.1.2",
|
||||||
|
"content-type": "^1.0.5",
|
||||||
|
"debug": "^4.4.0",
|
||||||
|
"http-errors": "^2.0.0",
|
||||||
|
"iconv-lite": "^0.6.3",
|
||||||
|
"on-finished": "^2.4.1",
|
||||||
|
"qs": "^6.14.0",
|
||||||
|
"raw-body": "^3.0.0",
|
||||||
|
"type-is": "^2.0.0"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">=18"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/bytes": {
|
||||||
|
"version": "3.1.2",
|
||||||
|
"resolved": "https://registry.npmjs.org/bytes/-/bytes-3.1.2.tgz",
|
||||||
|
"integrity": "sha512-/Nf7TyzTx6S3yRJObOAV7956r8cr2+Oj8AC5dt8wSP3BQAoeX58NoHyCU8P8zGkNXStjTSi6fzO6F0pBdcYbEg==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.8"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/call-bind-apply-helpers": {
|
||||||
|
"version": "1.0.2",
|
||||||
|
"resolved": "https://registry.npmjs.org/call-bind-apply-helpers/-/call-bind-apply-helpers-1.0.2.tgz",
|
||||||
|
"integrity": "sha512-Sp1ablJ0ivDkSzjcaJdxEunN5/XvksFJ2sMBFfq6x0ryhQV/2b/KwFe21cMpmHtPOSij8K99/wSfoEuTObmuMQ==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"es-errors": "^1.3.0",
|
||||||
|
"function-bind": "^1.1.2"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/call-bound": {
|
||||||
|
"version": "1.0.4",
|
||||||
|
"resolved": "https://registry.npmjs.org/call-bound/-/call-bound-1.0.4.tgz",
|
||||||
|
"integrity": "sha512-+ys997U96po4Kx/ABpBCqhA9EuxJaQWDQg7295H4hBphv3IZg0boBKuwYpt4YXp6MZ5AmZQnU/tyMTlRpaSejg==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"call-bind-apply-helpers": "^1.0.2",
|
||||||
|
"get-intrinsic": "^1.3.0"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
},
|
||||||
|
"funding": {
|
||||||
|
"url": "https://github.com/sponsors/ljharb"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/content-disposition": {
|
||||||
|
"version": "1.0.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/content-disposition/-/content-disposition-1.0.0.tgz",
|
||||||
|
"integrity": "sha512-Au9nRL8VNUut/XSzbQA38+M78dzP4D+eqg3gfJHMIHHYa3bg067xj1KxMUWj+VULbiZMowKngFFbKczUrNJ1mg==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"safe-buffer": "5.2.1"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.6"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/content-type": {
|
||||||
|
"version": "1.0.5",
|
||||||
|
"resolved": "https://registry.npmjs.org/content-type/-/content-type-1.0.5.tgz",
|
||||||
|
"integrity": "sha512-nTjqfcBFEipKdXCv4YDQWCfmcLZKm81ldF0pAopTvyrFGVbcR6P/VAAd5G7N+0tTr8QqiU0tFadD6FK4NtJwOA==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.6"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/cookie": {
|
||||||
|
"version": "0.7.2",
|
||||||
|
"resolved": "https://registry.npmjs.org/cookie/-/cookie-0.7.2.tgz",
|
||||||
|
"integrity": "sha512-yki5XnKuf750l50uGTllt6kKILY4nQ1eNIQatoXEByZ5dWgnKqbnqmTrBE5B4N7lrMJKQ2ytWMiTO2o0v6Ew/w==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.6"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/cookie-signature": {
|
||||||
|
"version": "1.2.2",
|
||||||
|
"resolved": "https://registry.npmjs.org/cookie-signature/-/cookie-signature-1.2.2.tgz",
|
||||||
|
"integrity": "sha512-D76uU73ulSXrD1UXF4KE2TMxVVwhsnCgfAyTg9k8P6KGZjlXKrOLe4dJQKI3Bxi5wjesZoFXJWElNWBjPZMbhg==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">=6.6.0"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/data-uri-to-buffer": {
|
||||||
|
"version": "4.0.1",
|
||||||
|
"resolved": "https://registry.npmjs.org/data-uri-to-buffer/-/data-uri-to-buffer-4.0.1.tgz",
|
||||||
|
"integrity": "sha512-0R9ikRb668HB7QDxT1vkpuUBtqc53YyAwMwGeUFKRojY/NWKvdZ+9UYtRfGmhqNbRkTSVpMbmyhXipFFv2cb/A==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 12"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/debug": {
|
||||||
|
"version": "4.4.1",
|
||||||
|
"resolved": "https://registry.npmjs.org/debug/-/debug-4.4.1.tgz",
|
||||||
|
"integrity": "sha512-KcKCqiftBJcZr++7ykoDIEwSa3XWowTfNPo92BYxjXiyYEVrUQh2aLyhxBCwww+heortUFxEJYcRzosstTEBYQ==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"ms": "^2.1.3"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">=6.0"
|
||||||
|
},
|
||||||
|
"peerDependenciesMeta": {
|
||||||
|
"supports-color": {
|
||||||
|
"optional": true
|
||||||
|
}
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/depd": {
|
||||||
|
"version": "2.0.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/depd/-/depd-2.0.0.tgz",
|
||||||
|
"integrity": "sha512-g7nH6P6dyDioJogAAGprGpCtVImJhpPk/roCzdb3fIh61/s/nPsfR6onyMwkCAR/OlC3yBC0lESvUoQEAssIrw==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.8"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/dunder-proto": {
|
||||||
|
"version": "1.0.1",
|
||||||
|
"resolved": "https://registry.npmjs.org/dunder-proto/-/dunder-proto-1.0.1.tgz",
|
||||||
|
"integrity": "sha512-KIN/nDJBQRcXw0MLVhZE9iQHmG68qAVIBg9CqmUYjmQIhgij9U5MFvrqkUL5FbtyyzZuOeOt0zdeRe4UY7ct+A==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"call-bind-apply-helpers": "^1.0.1",
|
||||||
|
"es-errors": "^1.3.0",
|
||||||
|
"gopd": "^1.2.0"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/ee-first": {
|
||||||
|
"version": "1.1.1",
|
||||||
|
"resolved": "https://registry.npmjs.org/ee-first/-/ee-first-1.1.1.tgz",
|
||||||
|
"integrity": "sha512-WMwm9LhRUo+WUaRN+vRuETqG89IgZphVSNkdFgeb6sS/E4OrDIN7t48CAewSHXc6C8lefD8KKfr5vY61brQlow==",
|
||||||
|
"license": "MIT"
|
||||||
|
},
|
||||||
|
"node_modules/encodeurl": {
|
||||||
|
"version": "2.0.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/encodeurl/-/encodeurl-2.0.0.tgz",
|
||||||
|
"integrity": "sha512-Q0n9HRi4m6JuGIV1eFlmvJB7ZEVxu93IrMyiMsGC0lrMJMWzRgx6WGquyfQgZVb31vhGgXnfmPNNXmxnOkRBrg==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.8"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/es-define-property": {
|
||||||
|
"version": "1.0.1",
|
||||||
|
"resolved": "https://registry.npmjs.org/es-define-property/-/es-define-property-1.0.1.tgz",
|
||||||
|
"integrity": "sha512-e3nRfgfUZ4rNGL232gUgX06QNyyez04KdjFrF+LTRoOXmrOgFKDg4BCdsjW8EnT69eqdYGmRpJwiPVYNrCaW3g==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/es-errors": {
|
||||||
|
"version": "1.3.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/es-errors/-/es-errors-1.3.0.tgz",
|
||||||
|
"integrity": "sha512-Zf5H2Kxt2xjTvbJvP2ZWLEICxA6j+hAmMzIlypy4xcBg1vKVnx89Wy0GbS+kf5cwCVFFzdCFh2XSCFNULS6csw==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/es-object-atoms": {
|
||||||
|
"version": "1.1.1",
|
||||||
|
"resolved": "https://registry.npmjs.org/es-object-atoms/-/es-object-atoms-1.1.1.tgz",
|
||||||
|
"integrity": "sha512-FGgH2h8zKNim9ljj7dankFPcICIK9Cp5bm+c2gQSYePhpaG5+esrLODihIorn+Pe6FGJzWhXQotPv73jTaldXA==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"es-errors": "^1.3.0"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/escape-html": {
|
||||||
|
"version": "1.0.3",
|
||||||
|
"resolved": "https://registry.npmjs.org/escape-html/-/escape-html-1.0.3.tgz",
|
||||||
|
"integrity": "sha512-NiSupZ4OeuGwr68lGIeym/ksIZMJodUGOSCZ/FSnTxcrekbvqrgdUxlJOMpijaKZVjAJrWrGs/6Jy8OMuyj9ow==",
|
||||||
|
"license": "MIT"
|
||||||
|
},
|
||||||
|
"node_modules/etag": {
|
||||||
|
"version": "1.8.1",
|
||||||
|
"resolved": "https://registry.npmjs.org/etag/-/etag-1.8.1.tgz",
|
||||||
|
"integrity": "sha512-aIL5Fx7mawVa300al2BnEE4iNvo1qETxLrPI/o05L7z6go7fCw1J6EQmbK4FmJ2AS7kgVF/KEZWufBfdClMcPg==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.6"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/express": {
|
||||||
|
"version": "5.1.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/express/-/express-5.1.0.tgz",
|
||||||
|
"integrity": "sha512-DT9ck5YIRU+8GYzzU5kT3eHGA5iL+1Zd0EutOmTE9Dtk+Tvuzd23VBU+ec7HPNSTxXYO55gPV/hq4pSBJDjFpA==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"accepts": "^2.0.0",
|
||||||
|
"body-parser": "^2.2.0",
|
||||||
|
"content-disposition": "^1.0.0",
|
||||||
|
"content-type": "^1.0.5",
|
||||||
|
"cookie": "^0.7.1",
|
||||||
|
"cookie-signature": "^1.2.1",
|
||||||
|
"debug": "^4.4.0",
|
||||||
|
"encodeurl": "^2.0.0",
|
||||||
|
"escape-html": "^1.0.3",
|
||||||
|
"etag": "^1.8.1",
|
||||||
|
"finalhandler": "^2.1.0",
|
||||||
|
"fresh": "^2.0.0",
|
||||||
|
"http-errors": "^2.0.0",
|
||||||
|
"merge-descriptors": "^2.0.0",
|
||||||
|
"mime-types": "^3.0.0",
|
||||||
|
"on-finished": "^2.4.1",
|
||||||
|
"once": "^1.4.0",
|
||||||
|
"parseurl": "^1.3.3",
|
||||||
|
"proxy-addr": "^2.0.7",
|
||||||
|
"qs": "^6.14.0",
|
||||||
|
"range-parser": "^1.2.1",
|
||||||
|
"router": "^2.2.0",
|
||||||
|
"send": "^1.1.0",
|
||||||
|
"serve-static": "^2.2.0",
|
||||||
|
"statuses": "^2.0.1",
|
||||||
|
"type-is": "^2.0.1",
|
||||||
|
"vary": "^1.1.2"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 18"
|
||||||
|
},
|
||||||
|
"funding": {
|
||||||
|
"type": "opencollective",
|
||||||
|
"url": "https://opencollective.com/express"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/fetch-blob": {
|
||||||
|
"version": "3.2.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/fetch-blob/-/fetch-blob-3.2.0.tgz",
|
||||||
|
"integrity": "sha512-7yAQpD2UMJzLi1Dqv7qFYnPbaPx7ZfFK6PiIxQ4PfkGPyNyl2Ugx+a/umUonmKqjhM4DnfbMvdX6otXq83soQQ==",
|
||||||
|
"funding": [
|
||||||
|
{
|
||||||
|
"type": "github",
|
||||||
|
"url": "https://github.com/sponsors/jimmywarting"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"type": "paypal",
|
||||||
|
"url": "https://paypal.me/jimmywarting"
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"node-domexception": "^1.0.0",
|
||||||
|
"web-streams-polyfill": "^3.0.3"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": "^12.20 || >= 14.13"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/finalhandler": {
|
||||||
|
"version": "2.1.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/finalhandler/-/finalhandler-2.1.0.tgz",
|
||||||
|
"integrity": "sha512-/t88Ty3d5JWQbWYgaOGCCYfXRwV1+be02WqYYlL6h0lEiUAMPM8o8qKGO01YIkOHzka2up08wvgYD0mDiI+q3Q==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"debug": "^4.4.0",
|
||||||
|
"encodeurl": "^2.0.0",
|
||||||
|
"escape-html": "^1.0.3",
|
||||||
|
"on-finished": "^2.4.1",
|
||||||
|
"parseurl": "^1.3.3",
|
||||||
|
"statuses": "^2.0.1"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.8"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/formdata-polyfill": {
|
||||||
|
"version": "4.0.10",
|
||||||
|
"resolved": "https://registry.npmjs.org/formdata-polyfill/-/formdata-polyfill-4.0.10.tgz",
|
||||||
|
"integrity": "sha512-buewHzMvYL29jdeQTVILecSaZKnt/RJWjoZCF5OW60Z67/GmSLBkOFM7qh1PI3zFNtJbaZL5eQu1vLfazOwj4g==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"fetch-blob": "^3.1.2"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">=12.20.0"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/forwarded": {
|
||||||
|
"version": "0.2.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/forwarded/-/forwarded-0.2.0.tgz",
|
||||||
|
"integrity": "sha512-buRG0fpBtRHSTCOASe6hD258tEubFoRLb4ZNA6NxMVHNw2gOcwHo9wyablzMzOA5z9xA9L1KNjk/Nt6MT9aYow==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.6"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/fresh": {
|
||||||
|
"version": "2.0.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/fresh/-/fresh-2.0.0.tgz",
|
||||||
|
"integrity": "sha512-Rx/WycZ60HOaqLKAi6cHRKKI7zxWbJ31MhntmtwMoaTeF7XFH9hhBp8vITaMidfljRQ6eYWCKkaTK+ykVJHP2A==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.8"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/fs": {
|
||||||
|
"version": "0.0.1-security",
|
||||||
|
"resolved": "https://registry.npmjs.org/fs/-/fs-0.0.1-security.tgz",
|
||||||
|
"integrity": "sha512-3XY9e1pP0CVEUCdj5BmfIZxRBTSDycnbqhIOGec9QYtmVH2fbLpj86CFWkrNOkt/Fvty4KZG5lTglL9j/gJ87w==",
|
||||||
|
"license": "ISC"
|
||||||
|
},
|
||||||
|
"node_modules/function-bind": {
|
||||||
|
"version": "1.1.2",
|
||||||
|
"resolved": "https://registry.npmjs.org/function-bind/-/function-bind-1.1.2.tgz",
|
||||||
|
"integrity": "sha512-7XHNxH7qX9xG5mIwxkhumTox/MIRNcOgDrxWsMt2pAr23WHp6MrRlN7FBSFpCpr+oVO0F744iUgR82nJMfG2SA==",
|
||||||
|
"license": "MIT",
|
||||||
|
"funding": {
|
||||||
|
"url": "https://github.com/sponsors/ljharb"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/get-intrinsic": {
|
||||||
|
"version": "1.3.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/get-intrinsic/-/get-intrinsic-1.3.0.tgz",
|
||||||
|
"integrity": "sha512-9fSjSaos/fRIVIp+xSJlE6lfwhES7LNtKaCBIamHsjr2na1BiABJPo0mOjjz8GJDURarmCPGqaiVg5mfjb98CQ==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"call-bind-apply-helpers": "^1.0.2",
|
||||||
|
"es-define-property": "^1.0.1",
|
||||||
|
"es-errors": "^1.3.0",
|
||||||
|
"es-object-atoms": "^1.1.1",
|
||||||
|
"function-bind": "^1.1.2",
|
||||||
|
"get-proto": "^1.0.1",
|
||||||
|
"gopd": "^1.2.0",
|
||||||
|
"has-symbols": "^1.1.0",
|
||||||
|
"hasown": "^2.0.2",
|
||||||
|
"math-intrinsics": "^1.1.0"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
},
|
||||||
|
"funding": {
|
||||||
|
"url": "https://github.com/sponsors/ljharb"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/get-proto": {
|
||||||
|
"version": "1.0.1",
|
||||||
|
"resolved": "https://registry.npmjs.org/get-proto/-/get-proto-1.0.1.tgz",
|
||||||
|
"integrity": "sha512-sTSfBjoXBp89JvIKIefqw7U2CCebsc74kiY6awiGogKtoSGbgjYE/G/+l9sF3MWFPNc9IcoOC4ODfKHfxFmp0g==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"dunder-proto": "^1.0.1",
|
||||||
|
"es-object-atoms": "^1.0.0"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/gopd": {
|
||||||
|
"version": "1.2.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/gopd/-/gopd-1.2.0.tgz",
|
||||||
|
"integrity": "sha512-ZUKRh6/kUFoAiTAtTYPZJ3hw9wNxx+BIBOijnlG9PnrJsCcSjs1wyyD6vJpaYtgnzDrKYRSqf3OO6Rfa93xsRg==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
},
|
||||||
|
"funding": {
|
||||||
|
"url": "https://github.com/sponsors/ljharb"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/has-symbols": {
|
||||||
|
"version": "1.1.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/has-symbols/-/has-symbols-1.1.0.tgz",
|
||||||
|
"integrity": "sha512-1cDNdwJ2Jaohmb3sg4OmKaMBwuC48sYni5HUw2DvsC8LjGTLK9h+eb1X6RyuOHe4hT0ULCW68iomhjUoKUqlPQ==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
},
|
||||||
|
"funding": {
|
||||||
|
"url": "https://github.com/sponsors/ljharb"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/hasown": {
|
||||||
|
"version": "2.0.2",
|
||||||
|
"resolved": "https://registry.npmjs.org/hasown/-/hasown-2.0.2.tgz",
|
||||||
|
"integrity": "sha512-0hJU9SCPvmMzIBdZFqNPXWa6dqh7WdH0cII9y+CyS8rG3nL48Bclra9HmKhVVUHyPWNH5Y7xDwAB7bfgSjkUMQ==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"function-bind": "^1.1.2"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/http-errors": {
|
||||||
|
"version": "2.0.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/http-errors/-/http-errors-2.0.0.tgz",
|
||||||
|
"integrity": "sha512-FtwrG/euBzaEjYeRqOgly7G0qviiXoJWnvEH2Z1plBdXgbyjv34pHTSb9zoeHMyDy33+DWy5Wt9Wo+TURtOYSQ==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"depd": "2.0.0",
|
||||||
|
"inherits": "2.0.4",
|
||||||
|
"setprototypeof": "1.2.0",
|
||||||
|
"statuses": "2.0.1",
|
||||||
|
"toidentifier": "1.0.1"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.8"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/http-errors/node_modules/statuses": {
|
||||||
|
"version": "2.0.1",
|
||||||
|
"resolved": "https://registry.npmjs.org/statuses/-/statuses-2.0.1.tgz",
|
||||||
|
"integrity": "sha512-RwNA9Z/7PrK06rYLIzFMlaF+l73iwpzsqRIFgbMLbTcLD6cOao82TaWefPXQvB2fOC4AjuYSEndS7N/mTCbkdQ==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.8"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/iconv-lite": {
|
||||||
|
"version": "0.6.3",
|
||||||
|
"resolved": "https://registry.npmjs.org/iconv-lite/-/iconv-lite-0.6.3.tgz",
|
||||||
|
"integrity": "sha512-4fCk79wshMdzMp2rH06qWrJE4iolqLhCUH+OiuIgU++RB0+94NlDL81atO7GX55uUKueo0txHNtvEyI6D7WdMw==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"safer-buffer": ">= 2.1.2 < 3.0.0"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">=0.10.0"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/inherits": {
|
||||||
|
"version": "2.0.4",
|
||||||
|
"resolved": "https://registry.npmjs.org/inherits/-/inherits-2.0.4.tgz",
|
||||||
|
"integrity": "sha512-k/vGaX4/Yla3WzyMCvTQOXYeIHvqOKtnqBduzTHpzpQZzAskKMhZ2K+EnBiSM9zGSoIFeMpXKxa4dYeZIQqewQ==",
|
||||||
|
"license": "ISC"
|
||||||
|
},
|
||||||
|
"node_modules/ipaddr.js": {
|
||||||
|
"version": "1.9.1",
|
||||||
|
"resolved": "https://registry.npmjs.org/ipaddr.js/-/ipaddr.js-1.9.1.tgz",
|
||||||
|
"integrity": "sha512-0KI/607xoxSToH7GjN1FfSbLoU0+btTicjsQSWQlh/hZykN8KpmMf7uYwPW3R+akZ6R/w18ZlXSHBYXiYUPO3g==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.10"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/is-promise": {
|
||||||
|
"version": "4.0.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/is-promise/-/is-promise-4.0.0.tgz",
|
||||||
|
"integrity": "sha512-hvpoI6korhJMnej285dSg6nu1+e6uxs7zG3BYAm5byqDsgJNWwxzM6z6iZiAgQR4TJ30JmBTOwqZUw3WlyH3AQ==",
|
||||||
|
"license": "MIT"
|
||||||
|
},
|
||||||
|
"node_modules/math-intrinsics": {
|
||||||
|
"version": "1.1.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/math-intrinsics/-/math-intrinsics-1.1.0.tgz",
|
||||||
|
"integrity": "sha512-/IXtbwEk5HTPyEwyKX6hGkYXxM9nbj64B+ilVJnC/R6B0pH5G4V3b0pVbL7DBj4tkhBAppbQUlf6F6Xl9LHu1g==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/media-typer": {
|
||||||
|
"version": "1.1.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/media-typer/-/media-typer-1.1.0.tgz",
|
||||||
|
"integrity": "sha512-aisnrDP4GNe06UcKFnV5bfMNPBUw4jsLGaWwWfnH3v02GnBuXX2MCVn5RbrWo0j3pczUilYblq7fQ7Nw2t5XKw==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.8"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/merge-descriptors": {
|
||||||
|
"version": "2.0.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/merge-descriptors/-/merge-descriptors-2.0.0.tgz",
|
||||||
|
"integrity": "sha512-Snk314V5ayFLhp3fkUREub6WtjBfPdCPY1Ln8/8munuLuiYhsABgBVWsozAG+MWMbVEvcdcpbi9R7ww22l9Q3g==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">=18"
|
||||||
|
},
|
||||||
|
"funding": {
|
||||||
|
"url": "https://github.com/sponsors/sindresorhus"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/mime-db": {
|
||||||
|
"version": "1.54.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/mime-db/-/mime-db-1.54.0.tgz",
|
||||||
|
"integrity": "sha512-aU5EJuIN2WDemCcAp2vFBfp/m4EAhWJnUNSSw0ixs7/kXbd6Pg64EmwJkNdFhB8aWt1sH2CTXrLxo/iAGV3oPQ==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.6"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/mime-types": {
|
||||||
|
"version": "3.0.1",
|
||||||
|
"resolved": "https://registry.npmjs.org/mime-types/-/mime-types-3.0.1.tgz",
|
||||||
|
"integrity": "sha512-xRc4oEhT6eaBpU1XF7AjpOFD+xQmXNB5OVKwp4tqCuBpHLS/ZbBDrc07mYTDqVMg6PfxUjjNp85O6Cd2Z/5HWA==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"mime-db": "^1.54.0"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.6"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/ms": {
|
||||||
|
"version": "2.1.3",
|
||||||
|
"resolved": "https://registry.npmjs.org/ms/-/ms-2.1.3.tgz",
|
||||||
|
"integrity": "sha512-6FlzubTLZG3J2a/NVCAleEhjzq5oxgHyaCU9yYXvcLsvoVaHJq/s5xXI6/XXP6tz7R9xAOtHnSO/tXtF3WRTlA==",
|
||||||
|
"license": "MIT"
|
||||||
|
},
|
||||||
|
"node_modules/negotiator": {
|
||||||
|
"version": "1.0.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/negotiator/-/negotiator-1.0.0.tgz",
|
||||||
|
"integrity": "sha512-8Ofs/AUQh8MaEcrlq5xOX0CQ9ypTF5dl78mjlMNfOK08fzpgTHQRQPBxcPlEtIw0yRpws+Zo/3r+5WRby7u3Gg==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.6"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/node-domexception": {
|
||||||
|
"version": "1.0.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/node-domexception/-/node-domexception-1.0.0.tgz",
|
||||||
|
"integrity": "sha512-/jKZoMpw0F8GRwl4/eLROPA3cfcXtLApP0QzLmUT/HuPCZWyB7IY9ZrMeKw2O/nFIqPQB3PVM9aYm0F312AXDQ==",
|
||||||
|
"deprecated": "Use your platform's native DOMException instead",
|
||||||
|
"funding": [
|
||||||
|
{
|
||||||
|
"type": "github",
|
||||||
|
"url": "https://github.com/sponsors/jimmywarting"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"type": "github",
|
||||||
|
"url": "https://paypal.me/jimmywarting"
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">=10.5.0"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/node-fetch": {
|
||||||
|
"version": "3.3.2",
|
||||||
|
"resolved": "https://registry.npmjs.org/node-fetch/-/node-fetch-3.3.2.tgz",
|
||||||
|
"integrity": "sha512-dRB78srN/l6gqWulah9SrxeYnxeddIG30+GOqK/9OlLVyLg3HPnr6SqOWTWOXKRwC2eGYCkZ59NNuSgvSrpgOA==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"data-uri-to-buffer": "^4.0.0",
|
||||||
|
"fetch-blob": "^3.1.4",
|
||||||
|
"formdata-polyfill": "^4.0.10"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": "^12.20.0 || ^14.13.1 || >=16.0.0"
|
||||||
|
},
|
||||||
|
"funding": {
|
||||||
|
"type": "opencollective",
|
||||||
|
"url": "https://opencollective.com/node-fetch"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/object-inspect": {
|
||||||
|
"version": "1.13.4",
|
||||||
|
"resolved": "https://registry.npmjs.org/object-inspect/-/object-inspect-1.13.4.tgz",
|
||||||
|
"integrity": "sha512-W67iLl4J2EXEGTbfeHCffrjDfitvLANg0UlX3wFUUSTx92KXRFegMHUVgSqE+wvhAbi4WqjGg9czysTV2Epbew==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
},
|
||||||
|
"funding": {
|
||||||
|
"url": "https://github.com/sponsors/ljharb"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/on-finished": {
|
||||||
|
"version": "2.4.1",
|
||||||
|
"resolved": "https://registry.npmjs.org/on-finished/-/on-finished-2.4.1.tgz",
|
||||||
|
"integrity": "sha512-oVlzkg3ENAhCk2zdv7IJwd/QUD4z2RxRwpkcGY8psCVcCYZNq4wYnVWALHM+brtuJjePWiYF/ClmuDr8Ch5+kg==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"ee-first": "1.1.1"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.8"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/once": {
|
||||||
|
"version": "1.4.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/once/-/once-1.4.0.tgz",
|
||||||
|
"integrity": "sha512-lNaJgI+2Q5URQBkccEKHTQOPaXdUxnZZElQTZY0MFUAuaEqe1E+Nyvgdz/aIyNi6Z9MzO5dv1H8n58/GELp3+w==",
|
||||||
|
"license": "ISC",
|
||||||
|
"dependencies": {
|
||||||
|
"wrappy": "1"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/parseurl": {
|
||||||
|
"version": "1.3.3",
|
||||||
|
"resolved": "https://registry.npmjs.org/parseurl/-/parseurl-1.3.3.tgz",
|
||||||
|
"integrity": "sha512-CiyeOxFT/JZyN5m0z9PfXw4SCBJ6Sygz1Dpl0wqjlhDEGGBP1GnsUVEL0p63hoG1fcj3fHynXi9NYO4nWOL+qQ==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.8"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/path": {
|
||||||
|
"version": "0.12.7",
|
||||||
|
"resolved": "https://registry.npmjs.org/path/-/path-0.12.7.tgz",
|
||||||
|
"integrity": "sha512-aXXC6s+1w7otVF9UletFkFcDsJeO7lSZBPUQhtb5O0xJe8LtYhj/GxldoL09bBj9+ZmE2hNoHqQSFMN5fikh4Q==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"process": "^0.11.1",
|
||||||
|
"util": "^0.10.3"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/path-to-regexp": {
|
||||||
|
"version": "8.2.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/path-to-regexp/-/path-to-regexp-8.2.0.tgz",
|
||||||
|
"integrity": "sha512-TdrF7fW9Rphjq4RjrW0Kp2AW0Ahwu9sRGTkS6bvDi0SCwZlEZYmcfDbEsTz8RVk0EHIS/Vd1bv3JhG+1xZuAyQ==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">=16"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/process": {
|
||||||
|
"version": "0.11.10",
|
||||||
|
"resolved": "https://registry.npmjs.org/process/-/process-0.11.10.tgz",
|
||||||
|
"integrity": "sha512-cdGef/drWFoydD1JsMzuFf8100nZl+GT+yacc2bEced5f9Rjk4z+WtFUTBu9PhOi9j/jfmBPu0mMEY4wIdAF8A==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.6.0"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/proxy-addr": {
|
||||||
|
"version": "2.0.7",
|
||||||
|
"resolved": "https://registry.npmjs.org/proxy-addr/-/proxy-addr-2.0.7.tgz",
|
||||||
|
"integrity": "sha512-llQsMLSUDUPT44jdrU/O37qlnifitDP+ZwrmmZcoSKyLKvtZxpyV0n2/bD/N4tBAAZ/gJEdZU7KMraoK1+XYAg==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"forwarded": "0.2.0",
|
||||||
|
"ipaddr.js": "1.9.1"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.10"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/qs": {
|
||||||
|
"version": "6.14.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/qs/-/qs-6.14.0.tgz",
|
||||||
|
"integrity": "sha512-YWWTjgABSKcvs/nWBi9PycY/JiPJqOD4JA6o9Sej2AtvSGarXxKC3OQSk4pAarbdQlKAh5D4FCQkJNkW+GAn3w==",
|
||||||
|
"license": "BSD-3-Clause",
|
||||||
|
"dependencies": {
|
||||||
|
"side-channel": "^1.1.0"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">=0.6"
|
||||||
|
},
|
||||||
|
"funding": {
|
||||||
|
"url": "https://github.com/sponsors/ljharb"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/range-parser": {
|
||||||
|
"version": "1.2.1",
|
||||||
|
"resolved": "https://registry.npmjs.org/range-parser/-/range-parser-1.2.1.tgz",
|
||||||
|
"integrity": "sha512-Hrgsx+orqoygnmhFbKaHE6c296J+HTAQXoxEF6gNupROmmGJRoyzfG3ccAveqCBrwr/2yxQ5BVd/GTl5agOwSg==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.6"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/raw-body": {
|
||||||
|
"version": "3.0.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/raw-body/-/raw-body-3.0.0.tgz",
|
||||||
|
"integrity": "sha512-RmkhL8CAyCRPXCE28MMH0z2PNWQBNk2Q09ZdxM9IOOXwxwZbN+qbWaatPkdkWIKL2ZVDImrN/pK5HTRz2PcS4g==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"bytes": "3.1.2",
|
||||||
|
"http-errors": "2.0.0",
|
||||||
|
"iconv-lite": "0.6.3",
|
||||||
|
"unpipe": "1.0.0"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.8"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/router": {
|
||||||
|
"version": "2.2.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/router/-/router-2.2.0.tgz",
|
||||||
|
"integrity": "sha512-nLTrUKm2UyiL7rlhapu/Zl45FwNgkZGaCpZbIHajDYgwlJCOzLSk+cIPAnsEqV955GjILJnKbdQC1nVPz+gAYQ==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"debug": "^4.4.0",
|
||||||
|
"depd": "^2.0.0",
|
||||||
|
"is-promise": "^4.0.0",
|
||||||
|
"parseurl": "^1.3.3",
|
||||||
|
"path-to-regexp": "^8.0.0"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 18"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/safe-buffer": {
|
||||||
|
"version": "5.2.1",
|
||||||
|
"resolved": "https://registry.npmjs.org/safe-buffer/-/safe-buffer-5.2.1.tgz",
|
||||||
|
"integrity": "sha512-rp3So07KcdmmKbGvgaNxQSJr7bGVSVk5S9Eq1F+ppbRo70+YeaDxkw5Dd8NPN+GD6bjnYm2VuPuCXmpuYvmCXQ==",
|
||||||
|
"funding": [
|
||||||
|
{
|
||||||
|
"type": "github",
|
||||||
|
"url": "https://github.com/sponsors/feross"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"type": "patreon",
|
||||||
|
"url": "https://www.patreon.com/feross"
|
||||||
|
},
|
||||||
|
{
|
||||||
|
"type": "consulting",
|
||||||
|
"url": "https://feross.org/support"
|
||||||
|
}
|
||||||
|
],
|
||||||
|
"license": "MIT"
|
||||||
|
},
|
||||||
|
"node_modules/safer-buffer": {
|
||||||
|
"version": "2.1.2",
|
||||||
|
"resolved": "https://registry.npmjs.org/safer-buffer/-/safer-buffer-2.1.2.tgz",
|
||||||
|
"integrity": "sha512-YZo3K82SD7Riyi0E1EQPojLz7kpepnSQI9IyPbHHg1XXXevb5dJI7tpyN2ADxGcQbHG7vcyRHk0cbwqcQriUtg==",
|
||||||
|
"license": "MIT"
|
||||||
|
},
|
||||||
|
"node_modules/send": {
|
||||||
|
"version": "1.2.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/send/-/send-1.2.0.tgz",
|
||||||
|
"integrity": "sha512-uaW0WwXKpL9blXE2o0bRhoL2EGXIrZxQ2ZQ4mgcfoBxdFmQold+qWsD2jLrfZ0trjKL6vOw0j//eAwcALFjKSw==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"debug": "^4.3.5",
|
||||||
|
"encodeurl": "^2.0.0",
|
||||||
|
"escape-html": "^1.0.3",
|
||||||
|
"etag": "^1.8.1",
|
||||||
|
"fresh": "^2.0.0",
|
||||||
|
"http-errors": "^2.0.0",
|
||||||
|
"mime-types": "^3.0.1",
|
||||||
|
"ms": "^2.1.3",
|
||||||
|
"on-finished": "^2.4.1",
|
||||||
|
"range-parser": "^1.2.1",
|
||||||
|
"statuses": "^2.0.1"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 18"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/serve-static": {
|
||||||
|
"version": "2.2.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/serve-static/-/serve-static-2.2.0.tgz",
|
||||||
|
"integrity": "sha512-61g9pCh0Vnh7IutZjtLGGpTA355+OPn2TyDv/6ivP2h/AdAVX9azsoxmg2/M6nZeQZNYBEwIcsne1mJd9oQItQ==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"encodeurl": "^2.0.0",
|
||||||
|
"escape-html": "^1.0.3",
|
||||||
|
"parseurl": "^1.3.3",
|
||||||
|
"send": "^1.2.0"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 18"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/setprototypeof": {
|
||||||
|
"version": "1.2.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/setprototypeof/-/setprototypeof-1.2.0.tgz",
|
||||||
|
"integrity": "sha512-E5LDX7Wrp85Kil5bhZv46j8jOeboKq5JMmYM3gVGdGH8xFpPWXUMsNrlODCrkoxMEeNi/XZIwuRvY4XNwYMJpw==",
|
||||||
|
"license": "ISC"
|
||||||
|
},
|
||||||
|
"node_modules/side-channel": {
|
||||||
|
"version": "1.1.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/side-channel/-/side-channel-1.1.0.tgz",
|
||||||
|
"integrity": "sha512-ZX99e6tRweoUXqR+VBrslhda51Nh5MTQwou5tnUDgbtyM0dBgmhEDtWGP/xbKn6hqfPRHujUNwz5fy/wbbhnpw==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"es-errors": "^1.3.0",
|
||||||
|
"object-inspect": "^1.13.3",
|
||||||
|
"side-channel-list": "^1.0.0",
|
||||||
|
"side-channel-map": "^1.0.1",
|
||||||
|
"side-channel-weakmap": "^1.0.2"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
},
|
||||||
|
"funding": {
|
||||||
|
"url": "https://github.com/sponsors/ljharb"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/side-channel-list": {
|
||||||
|
"version": "1.0.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/side-channel-list/-/side-channel-list-1.0.0.tgz",
|
||||||
|
"integrity": "sha512-FCLHtRD/gnpCiCHEiJLOwdmFP+wzCmDEkc9y7NsYxeF4u7Btsn1ZuwgwJGxImImHicJArLP4R0yX4c2KCrMrTA==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"es-errors": "^1.3.0",
|
||||||
|
"object-inspect": "^1.13.3"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
},
|
||||||
|
"funding": {
|
||||||
|
"url": "https://github.com/sponsors/ljharb"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/side-channel-map": {
|
||||||
|
"version": "1.0.1",
|
||||||
|
"resolved": "https://registry.npmjs.org/side-channel-map/-/side-channel-map-1.0.1.tgz",
|
||||||
|
"integrity": "sha512-VCjCNfgMsby3tTdo02nbjtM/ewra6jPHmpThenkTYh8pG9ucZ/1P8So4u4FGBek/BjpOVsDCMoLA/iuBKIFXRA==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"call-bound": "^1.0.2",
|
||||||
|
"es-errors": "^1.3.0",
|
||||||
|
"get-intrinsic": "^1.2.5",
|
||||||
|
"object-inspect": "^1.13.3"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
},
|
||||||
|
"funding": {
|
||||||
|
"url": "https://github.com/sponsors/ljharb"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/side-channel-weakmap": {
|
||||||
|
"version": "1.0.2",
|
||||||
|
"resolved": "https://registry.npmjs.org/side-channel-weakmap/-/side-channel-weakmap-1.0.2.tgz",
|
||||||
|
"integrity": "sha512-WPS/HvHQTYnHisLo9McqBHOJk2FkHO/tlpvldyrnem4aeQp4hai3gythswg6p01oSoTl58rcpiFAjF2br2Ak2A==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"call-bound": "^1.0.2",
|
||||||
|
"es-errors": "^1.3.0",
|
||||||
|
"get-intrinsic": "^1.2.5",
|
||||||
|
"object-inspect": "^1.13.3",
|
||||||
|
"side-channel-map": "^1.0.1"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
},
|
||||||
|
"funding": {
|
||||||
|
"url": "https://github.com/sponsors/ljharb"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/statuses": {
|
||||||
|
"version": "2.0.2",
|
||||||
|
"resolved": "https://registry.npmjs.org/statuses/-/statuses-2.0.2.tgz",
|
||||||
|
"integrity": "sha512-DvEy55V3DB7uknRo+4iOGT5fP1slR8wQohVdknigZPMpMstaKJQWhwiYBACJE3Ul2pTnATihhBYnRhZQHGBiRw==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.8"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/toidentifier": {
|
||||||
|
"version": "1.0.1",
|
||||||
|
"resolved": "https://registry.npmjs.org/toidentifier/-/toidentifier-1.0.1.tgz",
|
||||||
|
"integrity": "sha512-o5sSPKEkg/DIQNmH43V0/uerLrpzVedkUh8tGNvaeXpfpuwjKenlSox/2O/BTlZUtEe+JG7s5YhEz608PlAHRA==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">=0.6"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/type-is": {
|
||||||
|
"version": "2.0.1",
|
||||||
|
"resolved": "https://registry.npmjs.org/type-is/-/type-is-2.0.1.tgz",
|
||||||
|
"integrity": "sha512-OZs6gsjF4vMp32qrCbiVSkrFmXtG/AZhY3t0iAMrMBiAZyV9oALtXO8hsrHbMXF9x6L3grlFuwW2oAz7cav+Gw==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"content-type": "^1.0.5",
|
||||||
|
"media-typer": "^1.1.0",
|
||||||
|
"mime-types": "^3.0.0"
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.6"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/unpipe": {
|
||||||
|
"version": "1.0.0",
|
||||||
|
"resolved": "https://registry.npmjs.org/unpipe/-/unpipe-1.0.0.tgz",
|
||||||
|
"integrity": "sha512-pjy2bYhSsufwWlKwPc+l3cN7+wuJlK6uz0YdJEOlQDbl6jo/YlPi4mb8agUkVC8BF7V8NuzeyPNqRksA3hztKQ==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.8"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/util": {
|
||||||
|
"version": "0.10.4",
|
||||||
|
"resolved": "https://registry.npmjs.org/util/-/util-0.10.4.tgz",
|
||||||
|
"integrity": "sha512-0Pm9hTQ3se5ll1XihRic3FDIku70C+iHUdT/W926rSgHV5QgXsYbKZN8MSC3tJtSkhuROzvsQjAaFENRXr+19A==",
|
||||||
|
"license": "MIT",
|
||||||
|
"dependencies": {
|
||||||
|
"inherits": "2.0.3"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/util/node_modules/inherits": {
|
||||||
|
"version": "2.0.3",
|
||||||
|
"resolved": "https://registry.npmjs.org/inherits/-/inherits-2.0.3.tgz",
|
||||||
|
"integrity": "sha512-x00IRNXNy63jwGkJmzPigoySHbaqpNuzKbBOmzK+g2OdZpQ9w+sxCN+VSB3ja7IAge2OP2qpfxTjeNcyjmW1uw==",
|
||||||
|
"license": "ISC"
|
||||||
|
},
|
||||||
|
"node_modules/vary": {
|
||||||
|
"version": "1.1.2",
|
||||||
|
"resolved": "https://registry.npmjs.org/vary/-/vary-1.1.2.tgz",
|
||||||
|
"integrity": "sha512-BNGbWLfd0eUPabhkXUVm0j8uuvREyTh5ovRa/dyow/BqAbZJyC+5fU+IzQOzmAKzYqYRAISoRhdQr3eIZ/PXqg==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.8"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/web-streams-polyfill": {
|
||||||
|
"version": "3.3.3",
|
||||||
|
"resolved": "https://registry.npmjs.org/web-streams-polyfill/-/web-streams-polyfill-3.3.3.tgz",
|
||||||
|
"integrity": "sha512-d2JWLCivmZYTSIoge9MsgFCZrt571BikcWGYkjC1khllbTeDlGqZ2D8vD8E/lJa8WGWbb7Plm8/XJYV7IJHZZw==",
|
||||||
|
"license": "MIT",
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 8"
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"node_modules/wrappy": {
|
||||||
|
"version": "1.0.2",
|
||||||
|
"resolved": "https://registry.npmjs.org/wrappy/-/wrappy-1.0.2.tgz",
|
||||||
|
"integrity": "sha512-l4Sp/DRseor9wL6EvV2+TuQn63dMkPjZ/sp9XkghTEbV9KlPS1xUsZ3u7/IQO4wxtcFB4bgpQPRcR3QCvezPcQ==",
|
||||||
|
"license": "ISC"
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
+250
@@ -0,0 +1,250 @@
|
|||||||
|
2.0.0 / 2024-08-31
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Drop node <18 support
|
||||||
|
* deps: mime-types@^3.0.0
|
||||||
|
* deps: negotiator@^1.0.0
|
||||||
|
|
||||||
|
1.3.8 / 2022-02-02
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.1.34
|
||||||
|
- deps: mime-db@~1.51.0
|
||||||
|
* deps: negotiator@0.6.3
|
||||||
|
|
||||||
|
1.3.7 / 2019-04-29
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: negotiator@0.6.2
|
||||||
|
- Fix sorting charset, encoding, and language with extra parameters
|
||||||
|
|
||||||
|
1.3.6 / 2019-04-28
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.1.24
|
||||||
|
- deps: mime-db@~1.40.0
|
||||||
|
|
||||||
|
1.3.5 / 2018-02-28
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.1.18
|
||||||
|
- deps: mime-db@~1.33.0
|
||||||
|
|
||||||
|
1.3.4 / 2017-08-22
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.1.16
|
||||||
|
- deps: mime-db@~1.29.0
|
||||||
|
|
||||||
|
1.3.3 / 2016-05-02
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.1.11
|
||||||
|
- deps: mime-db@~1.23.0
|
||||||
|
* deps: negotiator@0.6.1
|
||||||
|
- perf: improve `Accept` parsing speed
|
||||||
|
- perf: improve `Accept-Charset` parsing speed
|
||||||
|
- perf: improve `Accept-Encoding` parsing speed
|
||||||
|
- perf: improve `Accept-Language` parsing speed
|
||||||
|
|
||||||
|
1.3.2 / 2016-03-08
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.1.10
|
||||||
|
- Fix extension of `application/dash+xml`
|
||||||
|
- Update primary extension for `audio/mp4`
|
||||||
|
- deps: mime-db@~1.22.0
|
||||||
|
|
||||||
|
1.3.1 / 2016-01-19
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.1.9
|
||||||
|
- deps: mime-db@~1.21.0
|
||||||
|
|
||||||
|
1.3.0 / 2015-09-29
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.1.7
|
||||||
|
- deps: mime-db@~1.19.0
|
||||||
|
* deps: negotiator@0.6.0
|
||||||
|
- Fix including type extensions in parameters in `Accept` parsing
|
||||||
|
- Fix parsing `Accept` parameters with quoted equals
|
||||||
|
- Fix parsing `Accept` parameters with quoted semicolons
|
||||||
|
- Lazy-load modules from main entry point
|
||||||
|
- perf: delay type concatenation until needed
|
||||||
|
- perf: enable strict mode
|
||||||
|
- perf: hoist regular expressions
|
||||||
|
- perf: remove closures getting spec properties
|
||||||
|
- perf: remove a closure from media type parsing
|
||||||
|
- perf: remove property delete from media type parsing
|
||||||
|
|
||||||
|
1.2.13 / 2015-09-06
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.1.6
|
||||||
|
- deps: mime-db@~1.18.0
|
||||||
|
|
||||||
|
1.2.12 / 2015-07-30
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.1.4
|
||||||
|
- deps: mime-db@~1.16.0
|
||||||
|
|
||||||
|
1.2.11 / 2015-07-16
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.1.3
|
||||||
|
- deps: mime-db@~1.15.0
|
||||||
|
|
||||||
|
1.2.10 / 2015-07-01
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.1.2
|
||||||
|
- deps: mime-db@~1.14.0
|
||||||
|
|
||||||
|
1.2.9 / 2015-06-08
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.1.1
|
||||||
|
- perf: fix deopt during mapping
|
||||||
|
|
||||||
|
1.2.8 / 2015-06-07
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.1.0
|
||||||
|
- deps: mime-db@~1.13.0
|
||||||
|
* perf: avoid argument reassignment & argument slice
|
||||||
|
* perf: avoid negotiator recursive construction
|
||||||
|
* perf: enable strict mode
|
||||||
|
* perf: remove unnecessary bitwise operator
|
||||||
|
|
||||||
|
1.2.7 / 2015-05-10
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: negotiator@0.5.3
|
||||||
|
- Fix media type parameter matching to be case-insensitive
|
||||||
|
|
||||||
|
1.2.6 / 2015-05-07
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.0.11
|
||||||
|
- deps: mime-db@~1.9.1
|
||||||
|
* deps: negotiator@0.5.2
|
||||||
|
- Fix comparing media types with quoted values
|
||||||
|
- Fix splitting media types with quoted commas
|
||||||
|
|
||||||
|
1.2.5 / 2015-03-13
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.0.10
|
||||||
|
- deps: mime-db@~1.8.0
|
||||||
|
|
||||||
|
1.2.4 / 2015-02-14
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Support Node.js 0.6
|
||||||
|
* deps: mime-types@~2.0.9
|
||||||
|
- deps: mime-db@~1.7.0
|
||||||
|
* deps: negotiator@0.5.1
|
||||||
|
- Fix preference sorting to be stable for long acceptable lists
|
||||||
|
|
||||||
|
1.2.3 / 2015-01-31
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.0.8
|
||||||
|
- deps: mime-db@~1.6.0
|
||||||
|
|
||||||
|
1.2.2 / 2014-12-30
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.0.7
|
||||||
|
- deps: mime-db@~1.5.0
|
||||||
|
|
||||||
|
1.2.1 / 2014-12-30
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.0.5
|
||||||
|
- deps: mime-db@~1.3.1
|
||||||
|
|
||||||
|
1.2.0 / 2014-12-19
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: negotiator@0.5.0
|
||||||
|
- Fix list return order when large accepted list
|
||||||
|
- Fix missing identity encoding when q=0 exists
|
||||||
|
- Remove dynamic building of Negotiator class
|
||||||
|
|
||||||
|
1.1.4 / 2014-12-10
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.0.4
|
||||||
|
- deps: mime-db@~1.3.0
|
||||||
|
|
||||||
|
1.1.3 / 2014-11-09
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.0.3
|
||||||
|
- deps: mime-db@~1.2.0
|
||||||
|
|
||||||
|
1.1.2 / 2014-10-14
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: negotiator@0.4.9
|
||||||
|
- Fix error when media type has invalid parameter
|
||||||
|
|
||||||
|
1.1.1 / 2014-09-28
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: mime-types@~2.0.2
|
||||||
|
- deps: mime-db@~1.1.0
|
||||||
|
* deps: negotiator@0.4.8
|
||||||
|
- Fix all negotiations to be case-insensitive
|
||||||
|
- Stable sort preferences of same quality according to client order
|
||||||
|
|
||||||
|
1.1.0 / 2014-09-02
|
||||||
|
==================
|
||||||
|
|
||||||
|
* update `mime-types`
|
||||||
|
|
||||||
|
1.0.7 / 2014-07-04
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Fix wrong type returned from `type` when match after unknown extension
|
||||||
|
|
||||||
|
1.0.6 / 2014-06-24
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: negotiator@0.4.7
|
||||||
|
|
||||||
|
1.0.5 / 2014-06-20
|
||||||
|
==================
|
||||||
|
|
||||||
|
* fix crash when unknown extension given
|
||||||
|
|
||||||
|
1.0.4 / 2014-06-19
|
||||||
|
==================
|
||||||
|
|
||||||
|
* use `mime-types`
|
||||||
|
|
||||||
|
1.0.3 / 2014-06-11
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: negotiator@0.4.6
|
||||||
|
- Order by specificity when quality is the same
|
||||||
|
|
||||||
|
1.0.2 / 2014-05-29
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Fix interpretation when header not in request
|
||||||
|
* deps: pin negotiator@0.4.5
|
||||||
|
|
||||||
|
1.0.1 / 2014-01-18
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Identity encoding isn't always acceptable
|
||||||
|
* deps: negotiator@~0.4.0
|
||||||
|
|
||||||
|
1.0.0 / 2013-12-27
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Genesis
|
||||||
+23
@@ -0,0 +1,23 @@
|
|||||||
|
(The MIT License)
|
||||||
|
|
||||||
|
Copyright (c) 2014 Jonathan Ong <me@jongleberry.com>
|
||||||
|
Copyright (c) 2015 Douglas Christopher Wilson <doug@somethingdoug.com>
|
||||||
|
|
||||||
|
Permission is hereby granted, free of charge, to any person obtaining
|
||||||
|
a copy of this software and associated documentation files (the
|
||||||
|
'Software'), to deal in the Software without restriction, including
|
||||||
|
without limitation the rights to use, copy, modify, merge, publish,
|
||||||
|
distribute, sublicense, and/or sell copies of the Software, and to
|
||||||
|
permit persons to whom the Software is furnished to do so, subject to
|
||||||
|
the following conditions:
|
||||||
|
|
||||||
|
The above copyright notice and this permission notice shall be
|
||||||
|
included in all copies or substantial portions of the Software.
|
||||||
|
|
||||||
|
THE SOFTWARE IS PROVIDED 'AS IS', WITHOUT WARRANTY OF ANY KIND,
|
||||||
|
EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF
|
||||||
|
MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT.
|
||||||
|
IN NO EVENT SHALL THE AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY
|
||||||
|
CLAIM, DAMAGES OR OTHER LIABILITY, WHETHER IN AN ACTION OF CONTRACT,
|
||||||
|
TORT OR OTHERWISE, ARISING FROM, OUT OF OR IN CONNECTION WITH THE
|
||||||
|
SOFTWARE OR THE USE OR OTHER DEALINGS IN THE SOFTWARE.
|
||||||
+140
@@ -0,0 +1,140 @@
|
|||||||
|
# accepts
|
||||||
|
|
||||||
|
[![NPM Version][npm-version-image]][npm-url]
|
||||||
|
[![NPM Downloads][npm-downloads-image]][npm-url]
|
||||||
|
[![Node.js Version][node-version-image]][node-version-url]
|
||||||
|
[![Build Status][github-actions-ci-image]][github-actions-ci-url]
|
||||||
|
[![Test Coverage][coveralls-image]][coveralls-url]
|
||||||
|
|
||||||
|
Higher level content negotiation based on [negotiator](https://www.npmjs.com/package/negotiator).
|
||||||
|
Extracted from [koa](https://www.npmjs.com/package/koa) for general use.
|
||||||
|
|
||||||
|
In addition to negotiator, it allows:
|
||||||
|
|
||||||
|
- Allows types as an array or arguments list, ie `(['text/html', 'application/json'])`
|
||||||
|
as well as `('text/html', 'application/json')`.
|
||||||
|
- Allows type shorthands such as `json`.
|
||||||
|
- Returns `false` when no types match
|
||||||
|
- Treats non-existent headers as `*`
|
||||||
|
|
||||||
|
## Installation
|
||||||
|
|
||||||
|
This is a [Node.js](https://nodejs.org/en/) module available through the
|
||||||
|
[npm registry](https://www.npmjs.com/). Installation is done using the
|
||||||
|
[`npm install` command](https://docs.npmjs.com/getting-started/installing-npm-packages-locally):
|
||||||
|
|
||||||
|
```sh
|
||||||
|
$ npm install accepts
|
||||||
|
```
|
||||||
|
|
||||||
|
## API
|
||||||
|
|
||||||
|
```js
|
||||||
|
var accepts = require('accepts')
|
||||||
|
```
|
||||||
|
|
||||||
|
### accepts(req)
|
||||||
|
|
||||||
|
Create a new `Accepts` object for the given `req`.
|
||||||
|
|
||||||
|
#### .charset(charsets)
|
||||||
|
|
||||||
|
Return the first accepted charset. If nothing in `charsets` is accepted,
|
||||||
|
then `false` is returned.
|
||||||
|
|
||||||
|
#### .charsets()
|
||||||
|
|
||||||
|
Return the charsets that the request accepts, in the order of the client's
|
||||||
|
preference (most preferred first).
|
||||||
|
|
||||||
|
#### .encoding(encodings)
|
||||||
|
|
||||||
|
Return the first accepted encoding. If nothing in `encodings` is accepted,
|
||||||
|
then `false` is returned.
|
||||||
|
|
||||||
|
#### .encodings()
|
||||||
|
|
||||||
|
Return the encodings that the request accepts, in the order of the client's
|
||||||
|
preference (most preferred first).
|
||||||
|
|
||||||
|
#### .language(languages)
|
||||||
|
|
||||||
|
Return the first accepted language. If nothing in `languages` is accepted,
|
||||||
|
then `false` is returned.
|
||||||
|
|
||||||
|
#### .languages()
|
||||||
|
|
||||||
|
Return the languages that the request accepts, in the order of the client's
|
||||||
|
preference (most preferred first).
|
||||||
|
|
||||||
|
#### .type(types)
|
||||||
|
|
||||||
|
Return the first accepted type (and it is returned as the same text as what
|
||||||
|
appears in the `types` array). If nothing in `types` is accepted, then `false`
|
||||||
|
is returned.
|
||||||
|
|
||||||
|
The `types` array can contain full MIME types or file extensions. Any value
|
||||||
|
that is not a full MIME type is passed to `require('mime-types').lookup`.
|
||||||
|
|
||||||
|
#### .types()
|
||||||
|
|
||||||
|
Return the types that the request accepts, in the order of the client's
|
||||||
|
preference (most preferred first).
|
||||||
|
|
||||||
|
## Examples
|
||||||
|
|
||||||
|
### Simple type negotiation
|
||||||
|
|
||||||
|
This simple example shows how to use `accepts` to return a different typed
|
||||||
|
respond body based on what the client wants to accept. The server lists it's
|
||||||
|
preferences in order and will get back the best match between the client and
|
||||||
|
server.
|
||||||
|
|
||||||
|
```js
|
||||||
|
var accepts = require('accepts')
|
||||||
|
var http = require('http')
|
||||||
|
|
||||||
|
function app (req, res) {
|
||||||
|
var accept = accepts(req)
|
||||||
|
|
||||||
|
// the order of this list is significant; should be server preferred order
|
||||||
|
switch (accept.type(['json', 'html'])) {
|
||||||
|
case 'json':
|
||||||
|
res.setHeader('Content-Type', 'application/json')
|
||||||
|
res.write('{"hello":"world!"}')
|
||||||
|
break
|
||||||
|
case 'html':
|
||||||
|
res.setHeader('Content-Type', 'text/html')
|
||||||
|
res.write('<b>hello, world!</b>')
|
||||||
|
break
|
||||||
|
default:
|
||||||
|
// the fallback is text/plain, so no need to specify it above
|
||||||
|
res.setHeader('Content-Type', 'text/plain')
|
||||||
|
res.write('hello, world!')
|
||||||
|
break
|
||||||
|
}
|
||||||
|
|
||||||
|
res.end()
|
||||||
|
}
|
||||||
|
|
||||||
|
http.createServer(app).listen(3000)
|
||||||
|
```
|
||||||
|
|
||||||
|
You can test this out with the cURL program:
|
||||||
|
```sh
|
||||||
|
curl -I -H'Accept: text/html' http://localhost:3000/
|
||||||
|
```
|
||||||
|
|
||||||
|
## License
|
||||||
|
|
||||||
|
[MIT](LICENSE)
|
||||||
|
|
||||||
|
[coveralls-image]: https://badgen.net/coveralls/c/github/jshttp/accepts/master
|
||||||
|
[coveralls-url]: https://coveralls.io/r/jshttp/accepts?branch=master
|
||||||
|
[github-actions-ci-image]: https://badgen.net/github/checks/jshttp/accepts/master?label=ci
|
||||||
|
[github-actions-ci-url]: https://github.com/jshttp/accepts/actions/workflows/ci.yml
|
||||||
|
[node-version-image]: https://badgen.net/npm/node/accepts
|
||||||
|
[node-version-url]: https://nodejs.org/en/download
|
||||||
|
[npm-downloads-image]: https://badgen.net/npm/dm/accepts
|
||||||
|
[npm-url]: https://npmjs.org/package/accepts
|
||||||
|
[npm-version-image]: https://badgen.net/npm/v/accepts
|
||||||
+238
@@ -0,0 +1,238 @@
|
|||||||
|
/*!
|
||||||
|
* accepts
|
||||||
|
* Copyright(c) 2014 Jonathan Ong
|
||||||
|
* Copyright(c) 2015 Douglas Christopher Wilson
|
||||||
|
* MIT Licensed
|
||||||
|
*/
|
||||||
|
|
||||||
|
'use strict'
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module dependencies.
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
var Negotiator = require('negotiator')
|
||||||
|
var mime = require('mime-types')
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module exports.
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
module.exports = Accepts
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Create a new Accepts object for the given req.
|
||||||
|
*
|
||||||
|
* @param {object} req
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
function Accepts (req) {
|
||||||
|
if (!(this instanceof Accepts)) {
|
||||||
|
return new Accepts(req)
|
||||||
|
}
|
||||||
|
|
||||||
|
this.headers = req.headers
|
||||||
|
this.negotiator = new Negotiator(req)
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Check if the given `type(s)` is acceptable, returning
|
||||||
|
* the best match when true, otherwise `undefined`, in which
|
||||||
|
* case you should respond with 406 "Not Acceptable".
|
||||||
|
*
|
||||||
|
* The `type` value may be a single mime type string
|
||||||
|
* such as "application/json", the extension name
|
||||||
|
* such as "json" or an array `["json", "html", "text/plain"]`. When a list
|
||||||
|
* or array is given the _best_ match, if any is returned.
|
||||||
|
*
|
||||||
|
* Examples:
|
||||||
|
*
|
||||||
|
* // Accept: text/html
|
||||||
|
* this.types('html');
|
||||||
|
* // => "html"
|
||||||
|
*
|
||||||
|
* // Accept: text/*, application/json
|
||||||
|
* this.types('html');
|
||||||
|
* // => "html"
|
||||||
|
* this.types('text/html');
|
||||||
|
* // => "text/html"
|
||||||
|
* this.types('json', 'text');
|
||||||
|
* // => "json"
|
||||||
|
* this.types('application/json');
|
||||||
|
* // => "application/json"
|
||||||
|
*
|
||||||
|
* // Accept: text/*, application/json
|
||||||
|
* this.types('image/png');
|
||||||
|
* this.types('png');
|
||||||
|
* // => undefined
|
||||||
|
*
|
||||||
|
* // Accept: text/*;q=.5, application/json
|
||||||
|
* this.types(['html', 'json']);
|
||||||
|
* this.types('html', 'json');
|
||||||
|
* // => "json"
|
||||||
|
*
|
||||||
|
* @param {String|Array} types...
|
||||||
|
* @return {String|Array|Boolean}
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
Accepts.prototype.type =
|
||||||
|
Accepts.prototype.types = function (types_) {
|
||||||
|
var types = types_
|
||||||
|
|
||||||
|
// support flattened arguments
|
||||||
|
if (types && !Array.isArray(types)) {
|
||||||
|
types = new Array(arguments.length)
|
||||||
|
for (var i = 0; i < types.length; i++) {
|
||||||
|
types[i] = arguments[i]
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// no types, return all requested types
|
||||||
|
if (!types || types.length === 0) {
|
||||||
|
return this.negotiator.mediaTypes()
|
||||||
|
}
|
||||||
|
|
||||||
|
// no accept header, return first given type
|
||||||
|
if (!this.headers.accept) {
|
||||||
|
return types[0]
|
||||||
|
}
|
||||||
|
|
||||||
|
var mimes = types.map(extToMime)
|
||||||
|
var accepts = this.negotiator.mediaTypes(mimes.filter(validMime))
|
||||||
|
var first = accepts[0]
|
||||||
|
|
||||||
|
return first
|
||||||
|
? types[mimes.indexOf(first)]
|
||||||
|
: false
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Return accepted encodings or best fit based on `encodings`.
|
||||||
|
*
|
||||||
|
* Given `Accept-Encoding: gzip, deflate`
|
||||||
|
* an array sorted by quality is returned:
|
||||||
|
*
|
||||||
|
* ['gzip', 'deflate']
|
||||||
|
*
|
||||||
|
* @param {String|Array} encodings...
|
||||||
|
* @return {String|Array}
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
Accepts.prototype.encoding =
|
||||||
|
Accepts.prototype.encodings = function (encodings_) {
|
||||||
|
var encodings = encodings_
|
||||||
|
|
||||||
|
// support flattened arguments
|
||||||
|
if (encodings && !Array.isArray(encodings)) {
|
||||||
|
encodings = new Array(arguments.length)
|
||||||
|
for (var i = 0; i < encodings.length; i++) {
|
||||||
|
encodings[i] = arguments[i]
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// no encodings, return all requested encodings
|
||||||
|
if (!encodings || encodings.length === 0) {
|
||||||
|
return this.negotiator.encodings()
|
||||||
|
}
|
||||||
|
|
||||||
|
return this.negotiator.encodings(encodings)[0] || false
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Return accepted charsets or best fit based on `charsets`.
|
||||||
|
*
|
||||||
|
* Given `Accept-Charset: utf-8, iso-8859-1;q=0.2, utf-7;q=0.5`
|
||||||
|
* an array sorted by quality is returned:
|
||||||
|
*
|
||||||
|
* ['utf-8', 'utf-7', 'iso-8859-1']
|
||||||
|
*
|
||||||
|
* @param {String|Array} charsets...
|
||||||
|
* @return {String|Array}
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
Accepts.prototype.charset =
|
||||||
|
Accepts.prototype.charsets = function (charsets_) {
|
||||||
|
var charsets = charsets_
|
||||||
|
|
||||||
|
// support flattened arguments
|
||||||
|
if (charsets && !Array.isArray(charsets)) {
|
||||||
|
charsets = new Array(arguments.length)
|
||||||
|
for (var i = 0; i < charsets.length; i++) {
|
||||||
|
charsets[i] = arguments[i]
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// no charsets, return all requested charsets
|
||||||
|
if (!charsets || charsets.length === 0) {
|
||||||
|
return this.negotiator.charsets()
|
||||||
|
}
|
||||||
|
|
||||||
|
return this.negotiator.charsets(charsets)[0] || false
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Return accepted languages or best fit based on `langs`.
|
||||||
|
*
|
||||||
|
* Given `Accept-Language: en;q=0.8, es, pt`
|
||||||
|
* an array sorted by quality is returned:
|
||||||
|
*
|
||||||
|
* ['es', 'pt', 'en']
|
||||||
|
*
|
||||||
|
* @param {String|Array} langs...
|
||||||
|
* @return {Array|String}
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
Accepts.prototype.lang =
|
||||||
|
Accepts.prototype.langs =
|
||||||
|
Accepts.prototype.language =
|
||||||
|
Accepts.prototype.languages = function (languages_) {
|
||||||
|
var languages = languages_
|
||||||
|
|
||||||
|
// support flattened arguments
|
||||||
|
if (languages && !Array.isArray(languages)) {
|
||||||
|
languages = new Array(arguments.length)
|
||||||
|
for (var i = 0; i < languages.length; i++) {
|
||||||
|
languages[i] = arguments[i]
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// no languages, return all requested languages
|
||||||
|
if (!languages || languages.length === 0) {
|
||||||
|
return this.negotiator.languages()
|
||||||
|
}
|
||||||
|
|
||||||
|
return this.negotiator.languages(languages)[0] || false
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Convert extnames to mime.
|
||||||
|
*
|
||||||
|
* @param {String} type
|
||||||
|
* @return {String}
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
function extToMime (type) {
|
||||||
|
return type.indexOf('/') === -1
|
||||||
|
? mime.lookup(type)
|
||||||
|
: type
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Check if mime is valid.
|
||||||
|
*
|
||||||
|
* @param {String} type
|
||||||
|
* @return {Boolean}
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
function validMime (type) {
|
||||||
|
return typeof type === 'string'
|
||||||
|
}
|
||||||
+47
@@ -0,0 +1,47 @@
|
|||||||
|
{
|
||||||
|
"name": "accepts",
|
||||||
|
"description": "Higher-level content negotiation",
|
||||||
|
"version": "2.0.0",
|
||||||
|
"contributors": [
|
||||||
|
"Douglas Christopher Wilson <doug@somethingdoug.com>",
|
||||||
|
"Jonathan Ong <me@jongleberry.com> (http://jongleberry.com)"
|
||||||
|
],
|
||||||
|
"license": "MIT",
|
||||||
|
"repository": "jshttp/accepts",
|
||||||
|
"dependencies": {
|
||||||
|
"mime-types": "^3.0.0",
|
||||||
|
"negotiator": "^1.0.0"
|
||||||
|
},
|
||||||
|
"devDependencies": {
|
||||||
|
"deep-equal": "1.0.1",
|
||||||
|
"eslint": "7.32.0",
|
||||||
|
"eslint-config-standard": "14.1.1",
|
||||||
|
"eslint-plugin-import": "2.25.4",
|
||||||
|
"eslint-plugin-markdown": "2.2.1",
|
||||||
|
"eslint-plugin-node": "11.1.0",
|
||||||
|
"eslint-plugin-promise": "4.3.1",
|
||||||
|
"eslint-plugin-standard": "4.1.0",
|
||||||
|
"mocha": "9.2.0",
|
||||||
|
"nyc": "15.1.0"
|
||||||
|
},
|
||||||
|
"files": [
|
||||||
|
"LICENSE",
|
||||||
|
"HISTORY.md",
|
||||||
|
"index.js"
|
||||||
|
],
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.6"
|
||||||
|
},
|
||||||
|
"scripts": {
|
||||||
|
"lint": "eslint .",
|
||||||
|
"test": "mocha --reporter spec --check-leaks --bail test/",
|
||||||
|
"test-ci": "nyc --reporter=lcov --reporter=text npm test",
|
||||||
|
"test-cov": "nyc --reporter=html --reporter=text npm test"
|
||||||
|
},
|
||||||
|
"keywords": [
|
||||||
|
"content",
|
||||||
|
"negotiation",
|
||||||
|
"accept",
|
||||||
|
"accepts"
|
||||||
|
]
|
||||||
|
}
|
||||||
+731
@@ -0,0 +1,731 @@
|
|||||||
|
2.2.0 / 2025-03-27
|
||||||
|
=========================
|
||||||
|
|
||||||
|
* refactor: normalize common options for all parsers
|
||||||
|
* deps:
|
||||||
|
* iconv-lite@^0.6.3
|
||||||
|
|
||||||
|
2.1.0 / 2025-02-10
|
||||||
|
=========================
|
||||||
|
|
||||||
|
* deps:
|
||||||
|
* type-is@^2.0.0
|
||||||
|
* debug@^4.4.0
|
||||||
|
* Removed destroy
|
||||||
|
* refactor: prefix built-in node module imports
|
||||||
|
* use the node require cache instead of custom caching
|
||||||
|
|
||||||
|
2.0.2 / 2024-10-31
|
||||||
|
=========================
|
||||||
|
|
||||||
|
* remove `unpipe` package and use native `unpipe()` method
|
||||||
|
|
||||||
|
2.0.1 / 2024-09-10
|
||||||
|
=========================
|
||||||
|
|
||||||
|
* Restore expected behavior `extended` to `false`
|
||||||
|
|
||||||
|
2.0.0 / 2024-09-10
|
||||||
|
=========================
|
||||||
|
* Propagate changes from 1.20.3
|
||||||
|
* add brotli support #406
|
||||||
|
* Breaking Change: Node.js 18 is the minimum supported version
|
||||||
|
|
||||||
|
2.0.0-beta.2 / 2023-02-23
|
||||||
|
=========================
|
||||||
|
|
||||||
|
This incorporates all changes after 1.19.1 up to 1.20.2.
|
||||||
|
|
||||||
|
* Remove deprecated `bodyParser()` combination middleware
|
||||||
|
* deps: debug@3.1.0
|
||||||
|
- Add `DEBUG_HIDE_DATE` environment variable
|
||||||
|
- Change timer to per-namespace instead of global
|
||||||
|
- Change non-TTY date format
|
||||||
|
- Remove `DEBUG_FD` environment variable support
|
||||||
|
- Support 256 namespace colors
|
||||||
|
* deps: iconv-lite@0.5.2
|
||||||
|
- Add encoding cp720
|
||||||
|
- Add encoding UTF-32
|
||||||
|
* deps: raw-body@3.0.0-beta.1
|
||||||
|
|
||||||
|
2.0.0-beta.1 / 2021-12-17
|
||||||
|
=========================
|
||||||
|
|
||||||
|
* Drop support for Node.js 0.8
|
||||||
|
* `req.body` is no longer always initialized to `{}`
|
||||||
|
- it is left `undefined` unless a body is parsed
|
||||||
|
* `urlencoded` parser now defaults `extended` to `false`
|
||||||
|
* Use `on-finished` to determine when body read
|
||||||
|
|
||||||
|
1.20.3 / 2024-09-10
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: qs@6.13.0
|
||||||
|
* add `depth` option to customize the depth level in the parser
|
||||||
|
* IMPORTANT: The default `depth` level for parsing URL-encoded data is now `32` (previously was `Infinity`)
|
||||||
|
|
||||||
|
1.20.2 / 2023-02-21
|
||||||
|
===================
|
||||||
|
|
||||||
|
* Fix strict json error message on Node.js 19+
|
||||||
|
* deps: content-type@~1.0.5
|
||||||
|
- perf: skip value escaping when unnecessary
|
||||||
|
* deps: raw-body@2.5.2
|
||||||
|
|
||||||
|
1.20.1 / 2022-10-06
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: qs@6.11.0
|
||||||
|
* perf: remove unnecessary object clone
|
||||||
|
|
||||||
|
1.20.0 / 2022-04-02
|
||||||
|
===================
|
||||||
|
|
||||||
|
* Fix error message for json parse whitespace in `strict`
|
||||||
|
* Fix internal error when inflated body exceeds limit
|
||||||
|
* Prevent loss of async hooks context
|
||||||
|
* Prevent hanging when request already read
|
||||||
|
* deps: depd@2.0.0
|
||||||
|
- Replace internal `eval` usage with `Function` constructor
|
||||||
|
- Use instance methods on `process` to check for listeners
|
||||||
|
* deps: http-errors@2.0.0
|
||||||
|
- deps: depd@2.0.0
|
||||||
|
- deps: statuses@2.0.1
|
||||||
|
* deps: on-finished@2.4.1
|
||||||
|
* deps: qs@6.10.3
|
||||||
|
* deps: raw-body@2.5.1
|
||||||
|
- deps: http-errors@2.0.0
|
||||||
|
|
||||||
|
1.19.2 / 2022-02-15
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: bytes@3.1.2
|
||||||
|
* deps: qs@6.9.7
|
||||||
|
* Fix handling of `__proto__` keys
|
||||||
|
* deps: raw-body@2.4.3
|
||||||
|
- deps: bytes@3.1.2
|
||||||
|
|
||||||
|
1.19.1 / 2021-12-10
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: bytes@3.1.1
|
||||||
|
* deps: http-errors@1.8.1
|
||||||
|
- deps: inherits@2.0.4
|
||||||
|
- deps: toidentifier@1.0.1
|
||||||
|
- deps: setprototypeof@1.2.0
|
||||||
|
* deps: qs@6.9.6
|
||||||
|
* deps: raw-body@2.4.2
|
||||||
|
- deps: bytes@3.1.1
|
||||||
|
- deps: http-errors@1.8.1
|
||||||
|
* deps: safe-buffer@5.2.1
|
||||||
|
* deps: type-is@~1.6.18
|
||||||
|
|
||||||
|
1.19.0 / 2019-04-25
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: bytes@3.1.0
|
||||||
|
- Add petabyte (`pb`) support
|
||||||
|
* deps: http-errors@1.7.2
|
||||||
|
- Set constructor name when possible
|
||||||
|
- deps: setprototypeof@1.1.1
|
||||||
|
- deps: statuses@'>= 1.5.0 < 2'
|
||||||
|
* deps: iconv-lite@0.4.24
|
||||||
|
- Added encoding MIK
|
||||||
|
* deps: qs@6.7.0
|
||||||
|
- Fix parsing array brackets after index
|
||||||
|
* deps: raw-body@2.4.0
|
||||||
|
- deps: bytes@3.1.0
|
||||||
|
- deps: http-errors@1.7.2
|
||||||
|
- deps: iconv-lite@0.4.24
|
||||||
|
* deps: type-is@~1.6.17
|
||||||
|
- deps: mime-types@~2.1.24
|
||||||
|
- perf: prevent internal `throw` on invalid type
|
||||||
|
|
||||||
|
1.18.3 / 2018-05-14
|
||||||
|
===================
|
||||||
|
|
||||||
|
* Fix stack trace for strict json parse error
|
||||||
|
* deps: depd@~1.1.2
|
||||||
|
- perf: remove argument reassignment
|
||||||
|
* deps: http-errors@~1.6.3
|
||||||
|
- deps: depd@~1.1.2
|
||||||
|
- deps: setprototypeof@1.1.0
|
||||||
|
- deps: statuses@'>= 1.3.1 < 2'
|
||||||
|
* deps: iconv-lite@0.4.23
|
||||||
|
- Fix loading encoding with year appended
|
||||||
|
- Fix deprecation warnings on Node.js 10+
|
||||||
|
* deps: qs@6.5.2
|
||||||
|
* deps: raw-body@2.3.3
|
||||||
|
- deps: http-errors@1.6.3
|
||||||
|
- deps: iconv-lite@0.4.23
|
||||||
|
* deps: type-is@~1.6.16
|
||||||
|
- deps: mime-types@~2.1.18
|
||||||
|
|
||||||
|
1.18.2 / 2017-09-22
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: debug@2.6.9
|
||||||
|
* perf: remove argument reassignment
|
||||||
|
|
||||||
|
1.18.1 / 2017-09-12
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: content-type@~1.0.4
|
||||||
|
- perf: remove argument reassignment
|
||||||
|
- perf: skip parameter parsing when no parameters
|
||||||
|
* deps: iconv-lite@0.4.19
|
||||||
|
- Fix ISO-8859-1 regression
|
||||||
|
- Update Windows-1255
|
||||||
|
* deps: qs@6.5.1
|
||||||
|
- Fix parsing & compacting very deep objects
|
||||||
|
* deps: raw-body@2.3.2
|
||||||
|
- deps: iconv-lite@0.4.19
|
||||||
|
|
||||||
|
1.18.0 / 2017-09-08
|
||||||
|
===================
|
||||||
|
|
||||||
|
* Fix JSON strict violation error to match native parse error
|
||||||
|
* Include the `body` property on verify errors
|
||||||
|
* Include the `type` property on all generated errors
|
||||||
|
* Use `http-errors` to set status code on errors
|
||||||
|
* deps: bytes@3.0.0
|
||||||
|
* deps: debug@2.6.8
|
||||||
|
* deps: depd@~1.1.1
|
||||||
|
- Remove unnecessary `Buffer` loading
|
||||||
|
* deps: http-errors@~1.6.2
|
||||||
|
- deps: depd@1.1.1
|
||||||
|
* deps: iconv-lite@0.4.18
|
||||||
|
- Add support for React Native
|
||||||
|
- Add a warning if not loaded as utf-8
|
||||||
|
- Fix CESU-8 decoding in Node.js 8
|
||||||
|
- Improve speed of ISO-8859-1 encoding
|
||||||
|
* deps: qs@6.5.0
|
||||||
|
* deps: raw-body@2.3.1
|
||||||
|
- Use `http-errors` for standard emitted errors
|
||||||
|
- deps: bytes@3.0.0
|
||||||
|
- deps: iconv-lite@0.4.18
|
||||||
|
- perf: skip buffer decoding on overage chunk
|
||||||
|
* perf: prevent internal `throw` when missing charset
|
||||||
|
|
||||||
|
1.17.2 / 2017-05-17
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: debug@2.6.7
|
||||||
|
- Fix `DEBUG_MAX_ARRAY_LENGTH`
|
||||||
|
- deps: ms@2.0.0
|
||||||
|
* deps: type-is@~1.6.15
|
||||||
|
- deps: mime-types@~2.1.15
|
||||||
|
|
||||||
|
1.17.1 / 2017-03-06
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: qs@6.4.0
|
||||||
|
- Fix regression parsing keys starting with `[`
|
||||||
|
|
||||||
|
1.17.0 / 2017-03-01
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: http-errors@~1.6.1
|
||||||
|
- Make `message` property enumerable for `HttpError`s
|
||||||
|
- deps: setprototypeof@1.0.3
|
||||||
|
* deps: qs@6.3.1
|
||||||
|
- Fix compacting nested arrays
|
||||||
|
|
||||||
|
1.16.1 / 2017-02-10
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: debug@2.6.1
|
||||||
|
- Fix deprecation messages in WebStorm and other editors
|
||||||
|
- Undeprecate `DEBUG_FD` set to `1` or `2`
|
||||||
|
|
||||||
|
1.16.0 / 2017-01-17
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: debug@2.6.0
|
||||||
|
- Allow colors in workers
|
||||||
|
- Deprecated `DEBUG_FD` environment variable
|
||||||
|
- Fix error when running under React Native
|
||||||
|
- Use same color for same namespace
|
||||||
|
- deps: ms@0.7.2
|
||||||
|
* deps: http-errors@~1.5.1
|
||||||
|
- deps: inherits@2.0.3
|
||||||
|
- deps: setprototypeof@1.0.2
|
||||||
|
- deps: statuses@'>= 1.3.1 < 2'
|
||||||
|
* deps: iconv-lite@0.4.15
|
||||||
|
- Added encoding MS-31J
|
||||||
|
- Added encoding MS-932
|
||||||
|
- Added encoding MS-936
|
||||||
|
- Added encoding MS-949
|
||||||
|
- Added encoding MS-950
|
||||||
|
- Fix GBK/GB18030 handling of Euro character
|
||||||
|
* deps: qs@6.2.1
|
||||||
|
- Fix array parsing from skipping empty values
|
||||||
|
* deps: raw-body@~2.2.0
|
||||||
|
- deps: iconv-lite@0.4.15
|
||||||
|
* deps: type-is@~1.6.14
|
||||||
|
- deps: mime-types@~2.1.13
|
||||||
|
|
||||||
|
1.15.2 / 2016-06-19
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: bytes@2.4.0
|
||||||
|
* deps: content-type@~1.0.2
|
||||||
|
- perf: enable strict mode
|
||||||
|
* deps: http-errors@~1.5.0
|
||||||
|
- Use `setprototypeof` module to replace `__proto__` setting
|
||||||
|
- deps: statuses@'>= 1.3.0 < 2'
|
||||||
|
- perf: enable strict mode
|
||||||
|
* deps: qs@6.2.0
|
||||||
|
* deps: raw-body@~2.1.7
|
||||||
|
- deps: bytes@2.4.0
|
||||||
|
- perf: remove double-cleanup on happy path
|
||||||
|
* deps: type-is@~1.6.13
|
||||||
|
- deps: mime-types@~2.1.11
|
||||||
|
|
||||||
|
1.15.1 / 2016-05-05
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: bytes@2.3.0
|
||||||
|
- Drop partial bytes on all parsed units
|
||||||
|
- Fix parsing byte string that looks like hex
|
||||||
|
* deps: raw-body@~2.1.6
|
||||||
|
- deps: bytes@2.3.0
|
||||||
|
* deps: type-is@~1.6.12
|
||||||
|
- deps: mime-types@~2.1.10
|
||||||
|
|
||||||
|
1.15.0 / 2016-02-10
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: http-errors@~1.4.0
|
||||||
|
- Add `HttpError` export, for `err instanceof createError.HttpError`
|
||||||
|
- deps: inherits@2.0.1
|
||||||
|
- deps: statuses@'>= 1.2.1 < 2'
|
||||||
|
* deps: qs@6.1.0
|
||||||
|
* deps: type-is@~1.6.11
|
||||||
|
- deps: mime-types@~2.1.9
|
||||||
|
|
||||||
|
1.14.2 / 2015-12-16
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: bytes@2.2.0
|
||||||
|
* deps: iconv-lite@0.4.13
|
||||||
|
* deps: qs@5.2.0
|
||||||
|
* deps: raw-body@~2.1.5
|
||||||
|
- deps: bytes@2.2.0
|
||||||
|
- deps: iconv-lite@0.4.13
|
||||||
|
* deps: type-is@~1.6.10
|
||||||
|
- deps: mime-types@~2.1.8
|
||||||
|
|
||||||
|
1.14.1 / 2015-09-27
|
||||||
|
===================
|
||||||
|
|
||||||
|
* Fix issue where invalid charset results in 400 when `verify` used
|
||||||
|
* deps: iconv-lite@0.4.12
|
||||||
|
- Fix CESU-8 decoding in Node.js 4.x
|
||||||
|
* deps: raw-body@~2.1.4
|
||||||
|
- Fix masking critical errors from `iconv-lite`
|
||||||
|
- deps: iconv-lite@0.4.12
|
||||||
|
* deps: type-is@~1.6.9
|
||||||
|
- deps: mime-types@~2.1.7
|
||||||
|
|
||||||
|
1.14.0 / 2015-09-16
|
||||||
|
===================
|
||||||
|
|
||||||
|
* Fix JSON strict parse error to match syntax errors
|
||||||
|
* Provide static `require` analysis in `urlencoded` parser
|
||||||
|
* deps: depd@~1.1.0
|
||||||
|
- Support web browser loading
|
||||||
|
* deps: qs@5.1.0
|
||||||
|
* deps: raw-body@~2.1.3
|
||||||
|
- Fix sync callback when attaching data listener causes sync read
|
||||||
|
* deps: type-is@~1.6.8
|
||||||
|
- Fix type error when given invalid type to match against
|
||||||
|
- deps: mime-types@~2.1.6
|
||||||
|
|
||||||
|
1.13.3 / 2015-07-31
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: type-is@~1.6.6
|
||||||
|
- deps: mime-types@~2.1.4
|
||||||
|
|
||||||
|
1.13.2 / 2015-07-05
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: iconv-lite@0.4.11
|
||||||
|
* deps: qs@4.0.0
|
||||||
|
- Fix dropping parameters like `hasOwnProperty`
|
||||||
|
- Fix user-visible incompatibilities from 3.1.0
|
||||||
|
- Fix various parsing edge cases
|
||||||
|
* deps: raw-body@~2.1.2
|
||||||
|
- Fix error stack traces to skip `makeError`
|
||||||
|
- deps: iconv-lite@0.4.11
|
||||||
|
* deps: type-is@~1.6.4
|
||||||
|
- deps: mime-types@~2.1.2
|
||||||
|
- perf: enable strict mode
|
||||||
|
- perf: remove argument reassignment
|
||||||
|
|
||||||
|
1.13.1 / 2015-06-16
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: qs@2.4.2
|
||||||
|
- Downgraded from 3.1.0 because of user-visible incompatibilities
|
||||||
|
|
||||||
|
1.13.0 / 2015-06-14
|
||||||
|
===================
|
||||||
|
|
||||||
|
* Add `statusCode` property on `Error`s, in addition to `status`
|
||||||
|
* Change `type` default to `application/json` for JSON parser
|
||||||
|
* Change `type` default to `application/x-www-form-urlencoded` for urlencoded parser
|
||||||
|
* Provide static `require` analysis
|
||||||
|
* Use the `http-errors` module to generate errors
|
||||||
|
* deps: bytes@2.1.0
|
||||||
|
- Slight optimizations
|
||||||
|
* deps: iconv-lite@0.4.10
|
||||||
|
- The encoding UTF-16 without BOM now defaults to UTF-16LE when detection fails
|
||||||
|
- Leading BOM is now removed when decoding
|
||||||
|
* deps: on-finished@~2.3.0
|
||||||
|
- Add defined behavior for HTTP `CONNECT` requests
|
||||||
|
- Add defined behavior for HTTP `Upgrade` requests
|
||||||
|
- deps: ee-first@1.1.1
|
||||||
|
* deps: qs@3.1.0
|
||||||
|
- Fix dropping parameters like `hasOwnProperty`
|
||||||
|
- Fix various parsing edge cases
|
||||||
|
- Parsed object now has `null` prototype
|
||||||
|
* deps: raw-body@~2.1.1
|
||||||
|
- Use `unpipe` module for unpiping requests
|
||||||
|
- deps: iconv-lite@0.4.10
|
||||||
|
* deps: type-is@~1.6.3
|
||||||
|
- deps: mime-types@~2.1.1
|
||||||
|
- perf: reduce try block size
|
||||||
|
- perf: remove bitwise operations
|
||||||
|
* perf: enable strict mode
|
||||||
|
* perf: remove argument reassignment
|
||||||
|
* perf: remove delete call
|
||||||
|
|
||||||
|
1.12.4 / 2015-05-10
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: debug@~2.2.0
|
||||||
|
* deps: qs@2.4.2
|
||||||
|
- Fix allowing parameters like `constructor`
|
||||||
|
* deps: on-finished@~2.2.1
|
||||||
|
* deps: raw-body@~2.0.1
|
||||||
|
- Fix a false-positive when unpiping in Node.js 0.8
|
||||||
|
- deps: bytes@2.0.1
|
||||||
|
* deps: type-is@~1.6.2
|
||||||
|
- deps: mime-types@~2.0.11
|
||||||
|
|
||||||
|
1.12.3 / 2015-04-15
|
||||||
|
===================
|
||||||
|
|
||||||
|
* Slight efficiency improvement when not debugging
|
||||||
|
* deps: depd@~1.0.1
|
||||||
|
* deps: iconv-lite@0.4.8
|
||||||
|
- Add encoding alias UNICODE-1-1-UTF-7
|
||||||
|
* deps: raw-body@1.3.4
|
||||||
|
- Fix hanging callback if request aborts during read
|
||||||
|
- deps: iconv-lite@0.4.8
|
||||||
|
|
||||||
|
1.12.2 / 2015-03-16
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: qs@2.4.1
|
||||||
|
- Fix error when parameter `hasOwnProperty` is present
|
||||||
|
|
||||||
|
1.12.1 / 2015-03-15
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: debug@~2.1.3
|
||||||
|
- Fix high intensity foreground color for bold
|
||||||
|
- deps: ms@0.7.0
|
||||||
|
* deps: type-is@~1.6.1
|
||||||
|
- deps: mime-types@~2.0.10
|
||||||
|
|
||||||
|
1.12.0 / 2015-02-13
|
||||||
|
===================
|
||||||
|
|
||||||
|
* add `debug` messages
|
||||||
|
* accept a function for the `type` option
|
||||||
|
* use `content-type` to parse `Content-Type` headers
|
||||||
|
* deps: iconv-lite@0.4.7
|
||||||
|
- Gracefully support enumerables on `Object.prototype`
|
||||||
|
* deps: raw-body@1.3.3
|
||||||
|
- deps: iconv-lite@0.4.7
|
||||||
|
* deps: type-is@~1.6.0
|
||||||
|
- fix argument reassignment
|
||||||
|
- fix false-positives in `hasBody` `Transfer-Encoding` check
|
||||||
|
- support wildcard for both type and subtype (`*/*`)
|
||||||
|
- deps: mime-types@~2.0.9
|
||||||
|
|
||||||
|
1.11.0 / 2015-01-30
|
||||||
|
===================
|
||||||
|
|
||||||
|
* make internal `extended: true` depth limit infinity
|
||||||
|
* deps: type-is@~1.5.6
|
||||||
|
- deps: mime-types@~2.0.8
|
||||||
|
|
||||||
|
1.10.2 / 2015-01-20
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: iconv-lite@0.4.6
|
||||||
|
- Fix rare aliases of single-byte encodings
|
||||||
|
* deps: raw-body@1.3.2
|
||||||
|
- deps: iconv-lite@0.4.6
|
||||||
|
|
||||||
|
1.10.1 / 2015-01-01
|
||||||
|
===================
|
||||||
|
|
||||||
|
* deps: on-finished@~2.2.0
|
||||||
|
* deps: type-is@~1.5.5
|
||||||
|
- deps: mime-types@~2.0.7
|
||||||
|
|
||||||
|
1.10.0 / 2014-12-02
|
||||||
|
===================
|
||||||
|
|
||||||
|
* make internal `extended: true` array limit dynamic
|
||||||
|
|
||||||
|
1.9.3 / 2014-11-21
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: iconv-lite@0.4.5
|
||||||
|
- Fix Windows-31J and X-SJIS encoding support
|
||||||
|
* deps: qs@2.3.3
|
||||||
|
- Fix `arrayLimit` behavior
|
||||||
|
* deps: raw-body@1.3.1
|
||||||
|
- deps: iconv-lite@0.4.5
|
||||||
|
* deps: type-is@~1.5.3
|
||||||
|
- deps: mime-types@~2.0.3
|
||||||
|
|
||||||
|
1.9.2 / 2014-10-27
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: qs@2.3.2
|
||||||
|
- Fix parsing of mixed objects and values
|
||||||
|
|
||||||
|
1.9.1 / 2014-10-22
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: on-finished@~2.1.1
|
||||||
|
- Fix handling of pipelined requests
|
||||||
|
* deps: qs@2.3.0
|
||||||
|
- Fix parsing of mixed implicit and explicit arrays
|
||||||
|
* deps: type-is@~1.5.2
|
||||||
|
- deps: mime-types@~2.0.2
|
||||||
|
|
||||||
|
1.9.0 / 2014-09-24
|
||||||
|
==================
|
||||||
|
|
||||||
|
* include the charset in "unsupported charset" error message
|
||||||
|
* include the encoding in "unsupported content encoding" error message
|
||||||
|
* deps: depd@~1.0.0
|
||||||
|
|
||||||
|
1.8.4 / 2014-09-23
|
||||||
|
==================
|
||||||
|
|
||||||
|
* fix content encoding to be case-insensitive
|
||||||
|
|
||||||
|
1.8.3 / 2014-09-19
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: qs@2.2.4
|
||||||
|
- Fix issue with object keys starting with numbers truncated
|
||||||
|
|
||||||
|
1.8.2 / 2014-09-15
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: depd@0.4.5
|
||||||
|
|
||||||
|
1.8.1 / 2014-09-07
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: media-typer@0.3.0
|
||||||
|
* deps: type-is@~1.5.1
|
||||||
|
|
||||||
|
1.8.0 / 2014-09-05
|
||||||
|
==================
|
||||||
|
|
||||||
|
* make empty-body-handling consistent between chunked requests
|
||||||
|
- empty `json` produces `{}`
|
||||||
|
- empty `raw` produces `new Buffer(0)`
|
||||||
|
- empty `text` produces `''`
|
||||||
|
- empty `urlencoded` produces `{}`
|
||||||
|
* deps: qs@2.2.3
|
||||||
|
- Fix issue where first empty value in array is discarded
|
||||||
|
* deps: type-is@~1.5.0
|
||||||
|
- fix `hasbody` to be true for `content-length: 0`
|
||||||
|
|
||||||
|
1.7.0 / 2014-09-01
|
||||||
|
==================
|
||||||
|
|
||||||
|
* add `parameterLimit` option to `urlencoded` parser
|
||||||
|
* change `urlencoded` extended array limit to 100
|
||||||
|
* respond with 413 when over `parameterLimit` in `urlencoded`
|
||||||
|
|
||||||
|
1.6.7 / 2014-08-29
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: qs@2.2.2
|
||||||
|
- Remove unnecessary cloning
|
||||||
|
|
||||||
|
1.6.6 / 2014-08-27
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: qs@2.2.0
|
||||||
|
- Array parsing fix
|
||||||
|
- Performance improvements
|
||||||
|
|
||||||
|
1.6.5 / 2014-08-16
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: on-finished@2.1.0
|
||||||
|
|
||||||
|
1.6.4 / 2014-08-14
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: qs@1.2.2
|
||||||
|
|
||||||
|
1.6.3 / 2014-08-10
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: qs@1.2.1
|
||||||
|
|
||||||
|
1.6.2 / 2014-08-07
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: qs@1.2.0
|
||||||
|
- Fix parsing array of objects
|
||||||
|
|
||||||
|
1.6.1 / 2014-08-06
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: qs@1.1.0
|
||||||
|
- Accept urlencoded square brackets
|
||||||
|
- Accept empty values in implicit array notation
|
||||||
|
|
||||||
|
1.6.0 / 2014-08-05
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: qs@1.0.2
|
||||||
|
- Complete rewrite
|
||||||
|
- Limits array length to 20
|
||||||
|
- Limits object depth to 5
|
||||||
|
- Limits parameters to 1,000
|
||||||
|
|
||||||
|
1.5.2 / 2014-07-27
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: depd@0.4.4
|
||||||
|
- Work-around v8 generating empty stack traces
|
||||||
|
|
||||||
|
1.5.1 / 2014-07-26
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: depd@0.4.3
|
||||||
|
- Fix exception when global `Error.stackTraceLimit` is too low
|
||||||
|
|
||||||
|
1.5.0 / 2014-07-20
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: depd@0.4.2
|
||||||
|
- Add `TRACE_DEPRECATION` environment variable
|
||||||
|
- Remove non-standard grey color from color output
|
||||||
|
- Support `--no-deprecation` argument
|
||||||
|
- Support `--trace-deprecation` argument
|
||||||
|
* deps: iconv-lite@0.4.4
|
||||||
|
- Added encoding UTF-7
|
||||||
|
* deps: raw-body@1.3.0
|
||||||
|
- deps: iconv-lite@0.4.4
|
||||||
|
- Added encoding UTF-7
|
||||||
|
- Fix `Cannot switch to old mode now` error on Node.js 0.10+
|
||||||
|
* deps: type-is@~1.3.2
|
||||||
|
|
||||||
|
1.4.3 / 2014-06-19
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: type-is@1.3.1
|
||||||
|
- fix global variable leak
|
||||||
|
|
||||||
|
1.4.2 / 2014-06-19
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: type-is@1.3.0
|
||||||
|
- improve type parsing
|
||||||
|
|
||||||
|
1.4.1 / 2014-06-19
|
||||||
|
==================
|
||||||
|
|
||||||
|
* fix urlencoded extended deprecation message
|
||||||
|
|
||||||
|
1.4.0 / 2014-06-19
|
||||||
|
==================
|
||||||
|
|
||||||
|
* add `text` parser
|
||||||
|
* add `raw` parser
|
||||||
|
* check accepted charset in content-type (accepts utf-8)
|
||||||
|
* check accepted encoding in content-encoding (accepts identity)
|
||||||
|
* deprecate `bodyParser()` middleware; use `.json()` and `.urlencoded()` as needed
|
||||||
|
* deprecate `urlencoded()` without provided `extended` option
|
||||||
|
* lazy-load urlencoded parsers
|
||||||
|
* parsers split into files for reduced mem usage
|
||||||
|
* support gzip and deflate bodies
|
||||||
|
- set `inflate: false` to turn off
|
||||||
|
* deps: raw-body@1.2.2
|
||||||
|
- Support all encodings from `iconv-lite`
|
||||||
|
|
||||||
|
1.3.1 / 2014-06-11
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: type-is@1.2.1
|
||||||
|
- Switch dependency from mime to mime-types@1.0.0
|
||||||
|
|
||||||
|
1.3.0 / 2014-05-31
|
||||||
|
==================
|
||||||
|
|
||||||
|
* add `extended` option to urlencoded parser
|
||||||
|
|
||||||
|
1.2.2 / 2014-05-27
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: raw-body@1.1.6
|
||||||
|
- assert stream encoding on node.js 0.8
|
||||||
|
- assert stream encoding on node.js < 0.10.6
|
||||||
|
- deps: bytes@1
|
||||||
|
|
||||||
|
1.2.1 / 2014-05-26
|
||||||
|
==================
|
||||||
|
|
||||||
|
* invoke `next(err)` after request fully read
|
||||||
|
- prevents hung responses and socket hang ups
|
||||||
|
|
||||||
|
1.2.0 / 2014-05-11
|
||||||
|
==================
|
||||||
|
|
||||||
|
* add `verify` option
|
||||||
|
* deps: type-is@1.2.0
|
||||||
|
- support suffix matching
|
||||||
|
|
||||||
|
1.1.2 / 2014-05-11
|
||||||
|
==================
|
||||||
|
|
||||||
|
* improve json parser speed
|
||||||
|
|
||||||
|
1.1.1 / 2014-05-11
|
||||||
|
==================
|
||||||
|
|
||||||
|
* fix repeated limit parsing with every request
|
||||||
|
|
||||||
|
1.1.0 / 2014-05-10
|
||||||
|
==================
|
||||||
|
|
||||||
|
* add `type` option
|
||||||
|
* deps: pin for safety and consistency
|
||||||
|
|
||||||
|
1.0.2 / 2014-04-14
|
||||||
|
==================
|
||||||
|
|
||||||
|
* use `type-is` module
|
||||||
|
|
||||||
|
1.0.1 / 2014-03-20
|
||||||
|
==================
|
||||||
|
|
||||||
|
* lower default limits to 100kb
|
||||||
+23
@@ -0,0 +1,23 @@
|
|||||||
|
(The MIT License)
|
||||||
|
|
||||||
|
Copyright (c) 2014 Jonathan Ong <me@jongleberry.com>
|
||||||
|
Copyright (c) 2014-2015 Douglas Christopher Wilson <doug@somethingdoug.com>
|
||||||
|
|
||||||
|
Permission is hereby granted, free of charge, to any person obtaining
|
||||||
|
a copy of this software and associated documentation files (the
|
||||||
|
'Software'), to deal in the Software without restriction, including
|
||||||
|
without limitation the rights to use, copy, modify, merge, publish,
|
||||||
|
distribute, sublicense, and/or sell copies of the Software, and to
|
||||||
|
permit persons to whom the Software is furnished to do so, subject to
|
||||||
|
the following conditions:
|
||||||
|
|
||||||
|
The above copyright notice and this permission notice shall be
|
||||||
|
included in all copies or substantial portions of the Software.
|
||||||
|
|
||||||
|
THE SOFTWARE IS PROVIDED 'AS IS', WITHOUT WARRANTY OF ANY KIND,
|
||||||
|
EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF
|
||||||
|
MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT.
|
||||||
|
IN NO EVENT SHALL THE AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY
|
||||||
|
CLAIM, DAMAGES OR OTHER LIABILITY, WHETHER IN AN ACTION OF CONTRACT,
|
||||||
|
TORT OR OTHERWISE, ARISING FROM, OUT OF OR IN CONNECTION WITH THE
|
||||||
|
SOFTWARE OR THE USE OR OTHER DEALINGS IN THE SOFTWARE.
|
||||||
+491
@@ -0,0 +1,491 @@
|
|||||||
|
# body-parser
|
||||||
|
|
||||||
|
[![NPM Version][npm-version-image]][npm-url]
|
||||||
|
[![NPM Downloads][npm-downloads-image]][npm-url]
|
||||||
|
[![Build Status][ci-image]][ci-url]
|
||||||
|
[![Test Coverage][coveralls-image]][coveralls-url]
|
||||||
|
[![OpenSSF Scorecard Badge][ossf-scorecard-badge]][ossf-scorecard-visualizer]
|
||||||
|
|
||||||
|
Node.js body parsing middleware.
|
||||||
|
|
||||||
|
Parse incoming request bodies in a middleware before your handlers, available
|
||||||
|
under the `req.body` property.
|
||||||
|
|
||||||
|
**Note** As `req.body`'s shape is based on user-controlled input, all
|
||||||
|
properties and values in this object are untrusted and should be validated
|
||||||
|
before trusting. For example, `req.body.foo.toString()` may fail in multiple
|
||||||
|
ways, for example the `foo` property may not be there or may not be a string,
|
||||||
|
and `toString` may not be a function and instead a string or other user input.
|
||||||
|
|
||||||
|
[Learn about the anatomy of an HTTP transaction in Node.js](https://nodejs.org/en/docs/guides/anatomy-of-an-http-transaction/).
|
||||||
|
|
||||||
|
_This does not handle multipart bodies_, due to their complex and typically
|
||||||
|
large nature. For multipart bodies, you may be interested in the following
|
||||||
|
modules:
|
||||||
|
|
||||||
|
* [busboy](https://www.npmjs.org/package/busboy#readme) and
|
||||||
|
[connect-busboy](https://www.npmjs.org/package/connect-busboy#readme)
|
||||||
|
* [multiparty](https://www.npmjs.org/package/multiparty#readme) and
|
||||||
|
[connect-multiparty](https://www.npmjs.org/package/connect-multiparty#readme)
|
||||||
|
* [formidable](https://www.npmjs.org/package/formidable#readme)
|
||||||
|
* [multer](https://www.npmjs.org/package/multer#readme)
|
||||||
|
|
||||||
|
This module provides the following parsers:
|
||||||
|
|
||||||
|
* [JSON body parser](#bodyparserjsonoptions)
|
||||||
|
* [Raw body parser](#bodyparserrawoptions)
|
||||||
|
* [Text body parser](#bodyparsertextoptions)
|
||||||
|
* [URL-encoded form body parser](#bodyparserurlencodedoptions)
|
||||||
|
|
||||||
|
Other body parsers you might be interested in:
|
||||||
|
|
||||||
|
- [body](https://www.npmjs.org/package/body#readme)
|
||||||
|
- [co-body](https://www.npmjs.org/package/co-body#readme)
|
||||||
|
|
||||||
|
## Installation
|
||||||
|
|
||||||
|
```sh
|
||||||
|
$ npm install body-parser
|
||||||
|
```
|
||||||
|
|
||||||
|
## API
|
||||||
|
|
||||||
|
```js
|
||||||
|
const bodyParser = require('body-parser')
|
||||||
|
```
|
||||||
|
|
||||||
|
The `bodyParser` object exposes various factories to create middlewares. All
|
||||||
|
middlewares will populate the `req.body` property with the parsed body when
|
||||||
|
the `Content-Type` request header matches the `type` option.
|
||||||
|
|
||||||
|
The various errors returned by this module are described in the
|
||||||
|
[errors section](#errors).
|
||||||
|
|
||||||
|
### bodyParser.json([options])
|
||||||
|
|
||||||
|
Returns middleware that only parses `json` and only looks at requests where
|
||||||
|
the `Content-Type` header matches the `type` option. This parser accepts any
|
||||||
|
Unicode encoding of the body and supports automatic inflation of `gzip`,
|
||||||
|
`br` (brotli) and `deflate` encodings.
|
||||||
|
|
||||||
|
A new `body` object containing the parsed data is populated on the `request`
|
||||||
|
object after the middleware (i.e. `req.body`).
|
||||||
|
|
||||||
|
#### Options
|
||||||
|
|
||||||
|
The `json` function takes an optional `options` object that may contain any of
|
||||||
|
the following keys:
|
||||||
|
|
||||||
|
##### inflate
|
||||||
|
|
||||||
|
When set to `true`, then deflated (compressed) bodies will be inflated; when
|
||||||
|
`false`, deflated bodies are rejected. Defaults to `true`.
|
||||||
|
|
||||||
|
##### limit
|
||||||
|
|
||||||
|
Controls the maximum request body size. If this is a number, then the value
|
||||||
|
specifies the number of bytes; if it is a string, the value is passed to the
|
||||||
|
[bytes](https://www.npmjs.com/package/bytes) library for parsing. Defaults
|
||||||
|
to `'100kb'`.
|
||||||
|
|
||||||
|
##### reviver
|
||||||
|
|
||||||
|
The `reviver` option is passed directly to `JSON.parse` as the second
|
||||||
|
argument. You can find more information on this argument
|
||||||
|
[in the MDN documentation about JSON.parse](https://developer.mozilla.org/en-US/docs/Web/JavaScript/Reference/Global_Objects/JSON/parse#Example.3A_Using_the_reviver_parameter).
|
||||||
|
|
||||||
|
##### strict
|
||||||
|
|
||||||
|
When set to `true`, will only accept arrays and objects; when `false` will
|
||||||
|
accept anything `JSON.parse` accepts. Defaults to `true`.
|
||||||
|
|
||||||
|
##### type
|
||||||
|
|
||||||
|
The `type` option is used to determine what media type the middleware will
|
||||||
|
parse. This option can be a string, array of strings, or a function. If not a
|
||||||
|
function, `type` option is passed directly to the
|
||||||
|
[type-is](https://www.npmjs.org/package/type-is#readme) library and this can
|
||||||
|
be an extension name (like `json`), a mime type (like `application/json`), or
|
||||||
|
a mime type with a wildcard (like `*/*` or `*/json`). If a function, the `type`
|
||||||
|
option is called as `fn(req)` and the request is parsed if it returns a truthy
|
||||||
|
value. Defaults to `application/json`.
|
||||||
|
|
||||||
|
##### verify
|
||||||
|
|
||||||
|
The `verify` option, if supplied, is called as `verify(req, res, buf, encoding)`,
|
||||||
|
where `buf` is a `Buffer` of the raw request body and `encoding` is the
|
||||||
|
encoding of the request. The parsing can be aborted by throwing an error.
|
||||||
|
|
||||||
|
### bodyParser.raw([options])
|
||||||
|
|
||||||
|
Returns middleware that parses all bodies as a `Buffer` and only looks at
|
||||||
|
requests where the `Content-Type` header matches the `type` option. This
|
||||||
|
parser supports automatic inflation of `gzip`, `br` (brotli) and `deflate`
|
||||||
|
encodings.
|
||||||
|
|
||||||
|
A new `body` object containing the parsed data is populated on the `request`
|
||||||
|
object after the middleware (i.e. `req.body`). This will be a `Buffer` object
|
||||||
|
of the body.
|
||||||
|
|
||||||
|
#### Options
|
||||||
|
|
||||||
|
The `raw` function takes an optional `options` object that may contain any of
|
||||||
|
the following keys:
|
||||||
|
|
||||||
|
##### inflate
|
||||||
|
|
||||||
|
When set to `true`, then deflated (compressed) bodies will be inflated; when
|
||||||
|
`false`, deflated bodies are rejected. Defaults to `true`.
|
||||||
|
|
||||||
|
##### limit
|
||||||
|
|
||||||
|
Controls the maximum request body size. If this is a number, then the value
|
||||||
|
specifies the number of bytes; if it is a string, the value is passed to the
|
||||||
|
[bytes](https://www.npmjs.com/package/bytes) library for parsing. Defaults
|
||||||
|
to `'100kb'`.
|
||||||
|
|
||||||
|
##### type
|
||||||
|
|
||||||
|
The `type` option is used to determine what media type the middleware will
|
||||||
|
parse. This option can be a string, array of strings, or a function.
|
||||||
|
If not a function, `type` option is passed directly to the
|
||||||
|
[type-is](https://www.npmjs.org/package/type-is#readme) library and this
|
||||||
|
can be an extension name (like `bin`), a mime type (like
|
||||||
|
`application/octet-stream`), or a mime type with a wildcard (like `*/*` or
|
||||||
|
`application/*`). If a function, the `type` option is called as `fn(req)`
|
||||||
|
and the request is parsed if it returns a truthy value. Defaults to
|
||||||
|
`application/octet-stream`.
|
||||||
|
|
||||||
|
##### verify
|
||||||
|
|
||||||
|
The `verify` option, if supplied, is called as `verify(req, res, buf, encoding)`,
|
||||||
|
where `buf` is a `Buffer` of the raw request body and `encoding` is the
|
||||||
|
encoding of the request. The parsing can be aborted by throwing an error.
|
||||||
|
|
||||||
|
### bodyParser.text([options])
|
||||||
|
|
||||||
|
Returns middleware that parses all bodies as a string and only looks at
|
||||||
|
requests where the `Content-Type` header matches the `type` option. This
|
||||||
|
parser supports automatic inflation of `gzip`, `br` (brotli) and `deflate`
|
||||||
|
encodings.
|
||||||
|
|
||||||
|
A new `body` string containing the parsed data is populated on the `request`
|
||||||
|
object after the middleware (i.e. `req.body`). This will be a string of the
|
||||||
|
body.
|
||||||
|
|
||||||
|
#### Options
|
||||||
|
|
||||||
|
The `text` function takes an optional `options` object that may contain any of
|
||||||
|
the following keys:
|
||||||
|
|
||||||
|
##### defaultCharset
|
||||||
|
|
||||||
|
Specify the default character set for the text content if the charset is not
|
||||||
|
specified in the `Content-Type` header of the request. Defaults to `utf-8`.
|
||||||
|
|
||||||
|
##### inflate
|
||||||
|
|
||||||
|
When set to `true`, then deflated (compressed) bodies will be inflated; when
|
||||||
|
`false`, deflated bodies are rejected. Defaults to `true`.
|
||||||
|
|
||||||
|
##### limit
|
||||||
|
|
||||||
|
Controls the maximum request body size. If this is a number, then the value
|
||||||
|
specifies the number of bytes; if it is a string, the value is passed to the
|
||||||
|
[bytes](https://www.npmjs.com/package/bytes) library for parsing. Defaults
|
||||||
|
to `'100kb'`.
|
||||||
|
|
||||||
|
##### type
|
||||||
|
|
||||||
|
The `type` option is used to determine what media type the middleware will
|
||||||
|
parse. This option can be a string, array of strings, or a function. If not
|
||||||
|
a function, `type` option is passed directly to the
|
||||||
|
[type-is](https://www.npmjs.org/package/type-is#readme) library and this can
|
||||||
|
be an extension name (like `txt`), a mime type (like `text/plain`), or a mime
|
||||||
|
type with a wildcard (like `*/*` or `text/*`). If a function, the `type`
|
||||||
|
option is called as `fn(req)` and the request is parsed if it returns a
|
||||||
|
truthy value. Defaults to `text/plain`.
|
||||||
|
|
||||||
|
##### verify
|
||||||
|
|
||||||
|
The `verify` option, if supplied, is called as `verify(req, res, buf, encoding)`,
|
||||||
|
where `buf` is a `Buffer` of the raw request body and `encoding` is the
|
||||||
|
encoding of the request. The parsing can be aborted by throwing an error.
|
||||||
|
|
||||||
|
### bodyParser.urlencoded([options])
|
||||||
|
|
||||||
|
Returns middleware that only parses `urlencoded` bodies and only looks at
|
||||||
|
requests where the `Content-Type` header matches the `type` option. This
|
||||||
|
parser accepts only UTF-8 encoding of the body and supports automatic
|
||||||
|
inflation of `gzip`, `br` (brotli) and `deflate` encodings.
|
||||||
|
|
||||||
|
A new `body` object containing the parsed data is populated on the `request`
|
||||||
|
object after the middleware (i.e. `req.body`). This object will contain
|
||||||
|
key-value pairs, where the value can be a string or array (when `extended` is
|
||||||
|
`false`), or any type (when `extended` is `true`).
|
||||||
|
|
||||||
|
#### Options
|
||||||
|
|
||||||
|
The `urlencoded` function takes an optional `options` object that may contain
|
||||||
|
any of the following keys:
|
||||||
|
|
||||||
|
##### extended
|
||||||
|
|
||||||
|
The "extended" syntax allows for rich objects and arrays to be encoded into the
|
||||||
|
URL-encoded format, allowing for a JSON-like experience with URL-encoded. For
|
||||||
|
more information, please [see the qs
|
||||||
|
library](https://www.npmjs.org/package/qs#readme).
|
||||||
|
|
||||||
|
Defaults to `false`.
|
||||||
|
|
||||||
|
##### inflate
|
||||||
|
|
||||||
|
When set to `true`, then deflated (compressed) bodies will be inflated; when
|
||||||
|
`false`, deflated bodies are rejected. Defaults to `true`.
|
||||||
|
|
||||||
|
##### limit
|
||||||
|
|
||||||
|
Controls the maximum request body size. If this is a number, then the value
|
||||||
|
specifies the number of bytes; if it is a string, the value is passed to the
|
||||||
|
[bytes](https://www.npmjs.com/package/bytes) library for parsing. Defaults
|
||||||
|
to `'100kb'`.
|
||||||
|
|
||||||
|
##### parameterLimit
|
||||||
|
|
||||||
|
The `parameterLimit` option controls the maximum number of parameters that
|
||||||
|
are allowed in the URL-encoded data. If a request contains more parameters
|
||||||
|
than this value, a 413 will be returned to the client. Defaults to `1000`.
|
||||||
|
|
||||||
|
##### type
|
||||||
|
|
||||||
|
The `type` option is used to determine what media type the middleware will
|
||||||
|
parse. This option can be a string, array of strings, or a function. If not
|
||||||
|
a function, `type` option is passed directly to the
|
||||||
|
[type-is](https://www.npmjs.org/package/type-is#readme) library and this can
|
||||||
|
be an extension name (like `urlencoded`), a mime type (like
|
||||||
|
`application/x-www-form-urlencoded`), or a mime type with a wildcard (like
|
||||||
|
`*/x-www-form-urlencoded`). If a function, the `type` option is called as
|
||||||
|
`fn(req)` and the request is parsed if it returns a truthy value. Defaults
|
||||||
|
to `application/x-www-form-urlencoded`.
|
||||||
|
|
||||||
|
##### verify
|
||||||
|
|
||||||
|
The `verify` option, if supplied, is called as `verify(req, res, buf, encoding)`,
|
||||||
|
where `buf` is a `Buffer` of the raw request body and `encoding` is the
|
||||||
|
encoding of the request. The parsing can be aborted by throwing an error.
|
||||||
|
|
||||||
|
##### defaultCharset
|
||||||
|
|
||||||
|
The default charset to parse as, if not specified in content-type. Must be
|
||||||
|
either `utf-8` or `iso-8859-1`. Defaults to `utf-8`.
|
||||||
|
|
||||||
|
##### charsetSentinel
|
||||||
|
|
||||||
|
Whether to let the value of the `utf8` parameter take precedence as the charset
|
||||||
|
selector. It requires the form to contain a parameter named `utf8` with a value
|
||||||
|
of `✓`. Defaults to `false`.
|
||||||
|
|
||||||
|
##### interpretNumericEntities
|
||||||
|
|
||||||
|
Whether to decode numeric entities such as `☺` when parsing an iso-8859-1
|
||||||
|
form. Defaults to `false`.
|
||||||
|
|
||||||
|
|
||||||
|
#### depth
|
||||||
|
|
||||||
|
The `depth` option is used to configure the maximum depth of the `qs` library when `extended` is `true`. This allows you to limit the amount of keys that are parsed and can be useful to prevent certain types of abuse. Defaults to `32`. It is recommended to keep this value as low as possible.
|
||||||
|
|
||||||
|
## Errors
|
||||||
|
|
||||||
|
The middlewares provided by this module create errors using the
|
||||||
|
[`http-errors` module](https://www.npmjs.com/package/http-errors). The errors
|
||||||
|
will typically have a `status`/`statusCode` property that contains the suggested
|
||||||
|
HTTP response code, an `expose` property to determine if the `message` property
|
||||||
|
should be displayed to the client, a `type` property to determine the type of
|
||||||
|
error without matching against the `message`, and a `body` property containing
|
||||||
|
the read body, if available.
|
||||||
|
|
||||||
|
The following are the common errors created, though any error can come through
|
||||||
|
for various reasons.
|
||||||
|
|
||||||
|
### content encoding unsupported
|
||||||
|
|
||||||
|
This error will occur when the request had a `Content-Encoding` header that
|
||||||
|
contained an encoding but the "inflation" option was set to `false`. The
|
||||||
|
`status` property is set to `415`, the `type` property is set to
|
||||||
|
`'encoding.unsupported'`, and the `charset` property will be set to the
|
||||||
|
encoding that is unsupported.
|
||||||
|
|
||||||
|
### entity parse failed
|
||||||
|
|
||||||
|
This error will occur when the request contained an entity that could not be
|
||||||
|
parsed by the middleware. The `status` property is set to `400`, the `type`
|
||||||
|
property is set to `'entity.parse.failed'`, and the `body` property is set to
|
||||||
|
the entity value that failed parsing.
|
||||||
|
|
||||||
|
### entity verify failed
|
||||||
|
|
||||||
|
This error will occur when the request contained an entity that could not be
|
||||||
|
failed verification by the defined `verify` option. The `status` property is
|
||||||
|
set to `403`, the `type` property is set to `'entity.verify.failed'`, and the
|
||||||
|
`body` property is set to the entity value that failed verification.
|
||||||
|
|
||||||
|
### request aborted
|
||||||
|
|
||||||
|
This error will occur when the request is aborted by the client before reading
|
||||||
|
the body has finished. The `received` property will be set to the number of
|
||||||
|
bytes received before the request was aborted and the `expected` property is
|
||||||
|
set to the number of expected bytes. The `status` property is set to `400`
|
||||||
|
and `type` property is set to `'request.aborted'`.
|
||||||
|
|
||||||
|
### request entity too large
|
||||||
|
|
||||||
|
This error will occur when the request body's size is larger than the "limit"
|
||||||
|
option. The `limit` property will be set to the byte limit and the `length`
|
||||||
|
property will be set to the request body's length. The `status` property is
|
||||||
|
set to `413` and the `type` property is set to `'entity.too.large'`.
|
||||||
|
|
||||||
|
### request size did not match content length
|
||||||
|
|
||||||
|
This error will occur when the request's length did not match the length from
|
||||||
|
the `Content-Length` header. This typically occurs when the request is malformed,
|
||||||
|
typically when the `Content-Length` header was calculated based on characters
|
||||||
|
instead of bytes. The `status` property is set to `400` and the `type` property
|
||||||
|
is set to `'request.size.invalid'`.
|
||||||
|
|
||||||
|
### stream encoding should not be set
|
||||||
|
|
||||||
|
This error will occur when something called the `req.setEncoding` method prior
|
||||||
|
to this middleware. This module operates directly on bytes only and you cannot
|
||||||
|
call `req.setEncoding` when using this module. The `status` property is set to
|
||||||
|
`500` and the `type` property is set to `'stream.encoding.set'`.
|
||||||
|
|
||||||
|
### stream is not readable
|
||||||
|
|
||||||
|
This error will occur when the request is no longer readable when this middleware
|
||||||
|
attempts to read it. This typically means something other than a middleware from
|
||||||
|
this module read the request body already and the middleware was also configured to
|
||||||
|
read the same request. The `status` property is set to `500` and the `type`
|
||||||
|
property is set to `'stream.not.readable'`.
|
||||||
|
|
||||||
|
### too many parameters
|
||||||
|
|
||||||
|
This error will occur when the content of the request exceeds the configured
|
||||||
|
`parameterLimit` for the `urlencoded` parser. The `status` property is set to
|
||||||
|
`413` and the `type` property is set to `'parameters.too.many'`.
|
||||||
|
|
||||||
|
### unsupported charset "BOGUS"
|
||||||
|
|
||||||
|
This error will occur when the request had a charset parameter in the
|
||||||
|
`Content-Type` header, but the `iconv-lite` module does not support it OR the
|
||||||
|
parser does not support it. The charset is contained in the message as well
|
||||||
|
as in the `charset` property. The `status` property is set to `415`, the
|
||||||
|
`type` property is set to `'charset.unsupported'`, and the `charset` property
|
||||||
|
is set to the charset that is unsupported.
|
||||||
|
|
||||||
|
### unsupported content encoding "bogus"
|
||||||
|
|
||||||
|
This error will occur when the request had a `Content-Encoding` header that
|
||||||
|
contained an unsupported encoding. The encoding is contained in the message
|
||||||
|
as well as in the `encoding` property. The `status` property is set to `415`,
|
||||||
|
the `type` property is set to `'encoding.unsupported'`, and the `encoding`
|
||||||
|
property is set to the encoding that is unsupported.
|
||||||
|
|
||||||
|
### The input exceeded the depth
|
||||||
|
|
||||||
|
This error occurs when using `bodyParser.urlencoded` with the `extended` property set to `true` and the input exceeds the configured `depth` option. The `status` property is set to `400`. It is recommended to review the `depth` option and evaluate if it requires a higher value. When the `depth` option is set to `32` (default value), the error will not be thrown.
|
||||||
|
|
||||||
|
## Examples
|
||||||
|
|
||||||
|
### Express/Connect top-level generic
|
||||||
|
|
||||||
|
This example demonstrates adding a generic JSON and URL-encoded parser as a
|
||||||
|
top-level middleware, which will parse the bodies of all incoming requests.
|
||||||
|
This is the simplest setup.
|
||||||
|
|
||||||
|
```js
|
||||||
|
const express = require('express')
|
||||||
|
const bodyParser = require('body-parser')
|
||||||
|
|
||||||
|
const app = express()
|
||||||
|
|
||||||
|
// parse application/x-www-form-urlencoded
|
||||||
|
app.use(bodyParser.urlencoded())
|
||||||
|
|
||||||
|
// parse application/json
|
||||||
|
app.use(bodyParser.json())
|
||||||
|
|
||||||
|
app.use(function (req, res) {
|
||||||
|
res.setHeader('Content-Type', 'text/plain')
|
||||||
|
res.write('you posted:\n')
|
||||||
|
res.end(String(JSON.stringify(req.body, null, 2)))
|
||||||
|
})
|
||||||
|
```
|
||||||
|
|
||||||
|
### Express route-specific
|
||||||
|
|
||||||
|
This example demonstrates adding body parsers specifically to the routes that
|
||||||
|
need them. In general, this is the most recommended way to use body-parser with
|
||||||
|
Express.
|
||||||
|
|
||||||
|
```js
|
||||||
|
const express = require('express')
|
||||||
|
const bodyParser = require('body-parser')
|
||||||
|
|
||||||
|
const app = express()
|
||||||
|
|
||||||
|
// create application/json parser
|
||||||
|
const jsonParser = bodyParser.json()
|
||||||
|
|
||||||
|
// create application/x-www-form-urlencoded parser
|
||||||
|
const urlencodedParser = bodyParser.urlencoded()
|
||||||
|
|
||||||
|
// POST /login gets urlencoded bodies
|
||||||
|
app.post('/login', urlencodedParser, function (req, res) {
|
||||||
|
if (!req.body || !req.body.username) res.sendStatus(400)
|
||||||
|
res.send('welcome, ' + req.body.username)
|
||||||
|
})
|
||||||
|
|
||||||
|
// POST /api/users gets JSON bodies
|
||||||
|
app.post('/api/users', jsonParser, function (req, res) {
|
||||||
|
if (!req.body) res.sendStatus(400)
|
||||||
|
// create user in req.body
|
||||||
|
})
|
||||||
|
```
|
||||||
|
|
||||||
|
### Change accepted type for parsers
|
||||||
|
|
||||||
|
All the parsers accept a `type` option which allows you to change the
|
||||||
|
`Content-Type` that the middleware will parse.
|
||||||
|
|
||||||
|
```js
|
||||||
|
const express = require('express')
|
||||||
|
const bodyParser = require('body-parser')
|
||||||
|
|
||||||
|
const app = express()
|
||||||
|
|
||||||
|
// parse various different custom JSON types as JSON
|
||||||
|
app.use(bodyParser.json({ type: 'application/*+json' }))
|
||||||
|
|
||||||
|
// parse some custom thing into a Buffer
|
||||||
|
app.use(bodyParser.raw({ type: 'application/vnd.custom-type' }))
|
||||||
|
|
||||||
|
// parse an HTML body into a string
|
||||||
|
app.use(bodyParser.text({ type: 'text/html' }))
|
||||||
|
```
|
||||||
|
|
||||||
|
## License
|
||||||
|
|
||||||
|
[MIT](LICENSE)
|
||||||
|
|
||||||
|
[ci-image]: https://badgen.net/github/checks/expressjs/body-parser/master?label=ci
|
||||||
|
[ci-url]: https://github.com/expressjs/body-parser/actions/workflows/ci.yml
|
||||||
|
[coveralls-image]: https://badgen.net/coveralls/c/github/expressjs/body-parser/master
|
||||||
|
[coveralls-url]: https://coveralls.io/r/expressjs/body-parser?branch=master
|
||||||
|
[node-version-image]: https://badgen.net/npm/node/body-parser
|
||||||
|
[node-version-url]: https://nodejs.org/en/download
|
||||||
|
[npm-downloads-image]: https://badgen.net/npm/dm/body-parser
|
||||||
|
[npm-url]: https://npmjs.org/package/body-parser
|
||||||
|
[npm-version-image]: https://badgen.net/npm/v/body-parser
|
||||||
|
[ossf-scorecard-badge]: https://api.scorecard.dev/projects/github.com/expressjs/body-parser/badge
|
||||||
|
[ossf-scorecard-visualizer]: https://ossf.github.io/scorecard-visualizer/#/projects/github.com/expressjs/body-parser
|
||||||
+80
@@ -0,0 +1,80 @@
|
|||||||
|
/*!
|
||||||
|
* body-parser
|
||||||
|
* Copyright(c) 2014-2015 Douglas Christopher Wilson
|
||||||
|
* MIT Licensed
|
||||||
|
*/
|
||||||
|
|
||||||
|
'use strict'
|
||||||
|
|
||||||
|
/**
|
||||||
|
* @typedef Parsers
|
||||||
|
* @type {function}
|
||||||
|
* @property {function} json
|
||||||
|
* @property {function} raw
|
||||||
|
* @property {function} text
|
||||||
|
* @property {function} urlencoded
|
||||||
|
*/
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module exports.
|
||||||
|
* @type {Parsers}
|
||||||
|
*/
|
||||||
|
|
||||||
|
exports = module.exports = bodyParser
|
||||||
|
|
||||||
|
/**
|
||||||
|
* JSON parser.
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
Object.defineProperty(exports, 'json', {
|
||||||
|
configurable: true,
|
||||||
|
enumerable: true,
|
||||||
|
get: () => require('./lib/types/json')
|
||||||
|
})
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Raw parser.
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
Object.defineProperty(exports, 'raw', {
|
||||||
|
configurable: true,
|
||||||
|
enumerable: true,
|
||||||
|
get: () => require('./lib/types/raw')
|
||||||
|
})
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Text parser.
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
Object.defineProperty(exports, 'text', {
|
||||||
|
configurable: true,
|
||||||
|
enumerable: true,
|
||||||
|
get: () => require('./lib/types/text')
|
||||||
|
})
|
||||||
|
|
||||||
|
/**
|
||||||
|
* URL-encoded parser.
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
Object.defineProperty(exports, 'urlencoded', {
|
||||||
|
configurable: true,
|
||||||
|
enumerable: true,
|
||||||
|
get: () => require('./lib/types/urlencoded')
|
||||||
|
})
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Create a middleware to parse json and urlencoded bodies.
|
||||||
|
*
|
||||||
|
* @param {object} [options]
|
||||||
|
* @return {function}
|
||||||
|
* @deprecated
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
function bodyParser () {
|
||||||
|
throw new Error('The bodyParser() generic has been split into individual middleware to use instead.')
|
||||||
|
}
|
||||||
+210
@@ -0,0 +1,210 @@
|
|||||||
|
/*!
|
||||||
|
* body-parser
|
||||||
|
* Copyright(c) 2014-2015 Douglas Christopher Wilson
|
||||||
|
* MIT Licensed
|
||||||
|
*/
|
||||||
|
|
||||||
|
'use strict'
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module dependencies.
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
var createError = require('http-errors')
|
||||||
|
var getBody = require('raw-body')
|
||||||
|
var iconv = require('iconv-lite')
|
||||||
|
var onFinished = require('on-finished')
|
||||||
|
var zlib = require('node:zlib')
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module exports.
|
||||||
|
*/
|
||||||
|
|
||||||
|
module.exports = read
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Read a request into a buffer and parse.
|
||||||
|
*
|
||||||
|
* @param {object} req
|
||||||
|
* @param {object} res
|
||||||
|
* @param {function} next
|
||||||
|
* @param {function} parse
|
||||||
|
* @param {function} debug
|
||||||
|
* @param {object} options
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
function read (req, res, next, parse, debug, options) {
|
||||||
|
var length
|
||||||
|
var opts = options
|
||||||
|
var stream
|
||||||
|
|
||||||
|
// read options
|
||||||
|
var encoding = opts.encoding !== null
|
||||||
|
? opts.encoding
|
||||||
|
: null
|
||||||
|
var verify = opts.verify
|
||||||
|
|
||||||
|
try {
|
||||||
|
// get the content stream
|
||||||
|
stream = contentstream(req, debug, opts.inflate)
|
||||||
|
length = stream.length
|
||||||
|
stream.length = undefined
|
||||||
|
} catch (err) {
|
||||||
|
return next(err)
|
||||||
|
}
|
||||||
|
|
||||||
|
// set raw-body options
|
||||||
|
opts.length = length
|
||||||
|
opts.encoding = verify
|
||||||
|
? null
|
||||||
|
: encoding
|
||||||
|
|
||||||
|
// assert charset is supported
|
||||||
|
if (opts.encoding === null && encoding !== null && !iconv.encodingExists(encoding)) {
|
||||||
|
return next(createError(415, 'unsupported charset "' + encoding.toUpperCase() + '"', {
|
||||||
|
charset: encoding.toLowerCase(),
|
||||||
|
type: 'charset.unsupported'
|
||||||
|
}))
|
||||||
|
}
|
||||||
|
|
||||||
|
// read body
|
||||||
|
debug('read body')
|
||||||
|
getBody(stream, opts, function (error, body) {
|
||||||
|
if (error) {
|
||||||
|
var _error
|
||||||
|
|
||||||
|
if (error.type === 'encoding.unsupported') {
|
||||||
|
// echo back charset
|
||||||
|
_error = createError(415, 'unsupported charset "' + encoding.toUpperCase() + '"', {
|
||||||
|
charset: encoding.toLowerCase(),
|
||||||
|
type: 'charset.unsupported'
|
||||||
|
})
|
||||||
|
} else {
|
||||||
|
// set status code on error
|
||||||
|
_error = createError(400, error)
|
||||||
|
}
|
||||||
|
|
||||||
|
// unpipe from stream and destroy
|
||||||
|
if (stream !== req) {
|
||||||
|
req.unpipe()
|
||||||
|
stream.destroy()
|
||||||
|
}
|
||||||
|
|
||||||
|
// read off entire request
|
||||||
|
dump(req, function onfinished () {
|
||||||
|
next(createError(400, _error))
|
||||||
|
})
|
||||||
|
return
|
||||||
|
}
|
||||||
|
|
||||||
|
// verify
|
||||||
|
if (verify) {
|
||||||
|
try {
|
||||||
|
debug('verify body')
|
||||||
|
verify(req, res, body, encoding)
|
||||||
|
} catch (err) {
|
||||||
|
next(createError(403, err, {
|
||||||
|
body: body,
|
||||||
|
type: err.type || 'entity.verify.failed'
|
||||||
|
}))
|
||||||
|
return
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// parse
|
||||||
|
var str = body
|
||||||
|
try {
|
||||||
|
debug('parse body')
|
||||||
|
str = typeof body !== 'string' && encoding !== null
|
||||||
|
? iconv.decode(body, encoding)
|
||||||
|
: body
|
||||||
|
req.body = parse(str, encoding)
|
||||||
|
} catch (err) {
|
||||||
|
next(createError(400, err, {
|
||||||
|
body: str,
|
||||||
|
type: err.type || 'entity.parse.failed'
|
||||||
|
}))
|
||||||
|
return
|
||||||
|
}
|
||||||
|
|
||||||
|
next()
|
||||||
|
})
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Get the content stream of the request.
|
||||||
|
*
|
||||||
|
* @param {object} req
|
||||||
|
* @param {function} debug
|
||||||
|
* @param {boolean} [inflate=true]
|
||||||
|
* @return {object}
|
||||||
|
* @api private
|
||||||
|
*/
|
||||||
|
|
||||||
|
function contentstream (req, debug, inflate) {
|
||||||
|
var encoding = (req.headers['content-encoding'] || 'identity').toLowerCase()
|
||||||
|
var length = req.headers['content-length']
|
||||||
|
|
||||||
|
debug('content-encoding "%s"', encoding)
|
||||||
|
|
||||||
|
if (inflate === false && encoding !== 'identity') {
|
||||||
|
throw createError(415, 'content encoding unsupported', {
|
||||||
|
encoding: encoding,
|
||||||
|
type: 'encoding.unsupported'
|
||||||
|
})
|
||||||
|
}
|
||||||
|
|
||||||
|
if (encoding === 'identity') {
|
||||||
|
req.length = length
|
||||||
|
return req
|
||||||
|
}
|
||||||
|
|
||||||
|
var stream = createDecompressionStream(encoding, debug)
|
||||||
|
req.pipe(stream)
|
||||||
|
return stream
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Create a decompression stream for the given encoding.
|
||||||
|
* @param {string} encoding
|
||||||
|
* @param {function} debug
|
||||||
|
* @return {object}
|
||||||
|
* @api private
|
||||||
|
*/
|
||||||
|
function createDecompressionStream (encoding, debug) {
|
||||||
|
switch (encoding) {
|
||||||
|
case 'deflate':
|
||||||
|
debug('inflate body')
|
||||||
|
return zlib.createInflate()
|
||||||
|
case 'gzip':
|
||||||
|
debug('gunzip body')
|
||||||
|
return zlib.createGunzip()
|
||||||
|
case 'br':
|
||||||
|
debug('brotli decompress body')
|
||||||
|
return zlib.createBrotliDecompress()
|
||||||
|
default:
|
||||||
|
throw createError(415, 'unsupported content encoding "' + encoding + '"', {
|
||||||
|
encoding: encoding,
|
||||||
|
type: 'encoding.unsupported'
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Dump the contents of a request.
|
||||||
|
*
|
||||||
|
* @param {object} req
|
||||||
|
* @param {function} callback
|
||||||
|
* @api private
|
||||||
|
*/
|
||||||
|
|
||||||
|
function dump (req, callback) {
|
||||||
|
if (onFinished.isFinished(req)) {
|
||||||
|
callback(null)
|
||||||
|
} else {
|
||||||
|
onFinished(req, callback)
|
||||||
|
req.resume()
|
||||||
|
}
|
||||||
|
}
|
||||||
+206
@@ -0,0 +1,206 @@
|
|||||||
|
/*!
|
||||||
|
* body-parser
|
||||||
|
* Copyright(c) 2014 Jonathan Ong
|
||||||
|
* Copyright(c) 2014-2015 Douglas Christopher Wilson
|
||||||
|
* MIT Licensed
|
||||||
|
*/
|
||||||
|
|
||||||
|
'use strict'
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module dependencies.
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
var createError = require('http-errors')
|
||||||
|
var debug = require('debug')('body-parser:json')
|
||||||
|
var isFinished = require('on-finished').isFinished
|
||||||
|
var read = require('../read')
|
||||||
|
var typeis = require('type-is')
|
||||||
|
var { getCharset, normalizeOptions } = require('../utils')
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module exports.
|
||||||
|
*/
|
||||||
|
|
||||||
|
module.exports = json
|
||||||
|
|
||||||
|
/**
|
||||||
|
* RegExp to match the first non-space in a string.
|
||||||
|
*
|
||||||
|
* Allowed whitespace is defined in RFC 7159:
|
||||||
|
*
|
||||||
|
* ws = *(
|
||||||
|
* %x20 / ; Space
|
||||||
|
* %x09 / ; Horizontal tab
|
||||||
|
* %x0A / ; Line feed or New line
|
||||||
|
* %x0D ) ; Carriage return
|
||||||
|
*/
|
||||||
|
|
||||||
|
var FIRST_CHAR_REGEXP = /^[\x20\x09\x0a\x0d]*([^\x20\x09\x0a\x0d])/ // eslint-disable-line no-control-regex
|
||||||
|
|
||||||
|
var JSON_SYNTAX_CHAR = '#'
|
||||||
|
var JSON_SYNTAX_REGEXP = /#+/g
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Create a middleware to parse JSON bodies.
|
||||||
|
*
|
||||||
|
* @param {object} [options]
|
||||||
|
* @return {function}
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
function json (options) {
|
||||||
|
var { inflate, limit, verify, shouldParse } = normalizeOptions(options, 'application/json')
|
||||||
|
|
||||||
|
var reviver = options?.reviver
|
||||||
|
var strict = options?.strict !== false
|
||||||
|
|
||||||
|
function parse (body) {
|
||||||
|
if (body.length === 0) {
|
||||||
|
// special-case empty json body, as it's a common client-side mistake
|
||||||
|
// TODO: maybe make this configurable or part of "strict" option
|
||||||
|
return {}
|
||||||
|
}
|
||||||
|
|
||||||
|
if (strict) {
|
||||||
|
var first = firstchar(body)
|
||||||
|
|
||||||
|
if (first !== '{' && first !== '[') {
|
||||||
|
debug('strict violation')
|
||||||
|
throw createStrictSyntaxError(body, first)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
try {
|
||||||
|
debug('parse json')
|
||||||
|
return JSON.parse(body, reviver)
|
||||||
|
} catch (e) {
|
||||||
|
throw normalizeJsonSyntaxError(e, {
|
||||||
|
message: e.message,
|
||||||
|
stack: e.stack
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
return function jsonParser (req, res, next) {
|
||||||
|
if (isFinished(req)) {
|
||||||
|
debug('body already parsed')
|
||||||
|
next()
|
||||||
|
return
|
||||||
|
}
|
||||||
|
|
||||||
|
if (!('body' in req)) {
|
||||||
|
req.body = undefined
|
||||||
|
}
|
||||||
|
|
||||||
|
// skip requests without bodies
|
||||||
|
if (!typeis.hasBody(req)) {
|
||||||
|
debug('skip empty body')
|
||||||
|
next()
|
||||||
|
return
|
||||||
|
}
|
||||||
|
|
||||||
|
debug('content-type %j', req.headers['content-type'])
|
||||||
|
|
||||||
|
// determine if request should be parsed
|
||||||
|
if (!shouldParse(req)) {
|
||||||
|
debug('skip parsing')
|
||||||
|
next()
|
||||||
|
return
|
||||||
|
}
|
||||||
|
|
||||||
|
// assert charset per RFC 7159 sec 8.1
|
||||||
|
var charset = getCharset(req) || 'utf-8'
|
||||||
|
if (charset.slice(0, 4) !== 'utf-') {
|
||||||
|
debug('invalid charset')
|
||||||
|
next(createError(415, 'unsupported charset "' + charset.toUpperCase() + '"', {
|
||||||
|
charset: charset,
|
||||||
|
type: 'charset.unsupported'
|
||||||
|
}))
|
||||||
|
return
|
||||||
|
}
|
||||||
|
|
||||||
|
// read
|
||||||
|
read(req, res, next, parse, debug, {
|
||||||
|
encoding: charset,
|
||||||
|
inflate,
|
||||||
|
limit,
|
||||||
|
verify
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Create strict violation syntax error matching native error.
|
||||||
|
*
|
||||||
|
* @param {string} str
|
||||||
|
* @param {string} char
|
||||||
|
* @return {Error}
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
function createStrictSyntaxError (str, char) {
|
||||||
|
var index = str.indexOf(char)
|
||||||
|
var partial = ''
|
||||||
|
|
||||||
|
if (index !== -1) {
|
||||||
|
partial = str.substring(0, index) + JSON_SYNTAX_CHAR
|
||||||
|
|
||||||
|
for (var i = index + 1; i < str.length; i++) {
|
||||||
|
partial += JSON_SYNTAX_CHAR
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
try {
|
||||||
|
JSON.parse(partial); /* istanbul ignore next */ throw new SyntaxError('strict violation')
|
||||||
|
} catch (e) {
|
||||||
|
return normalizeJsonSyntaxError(e, {
|
||||||
|
message: e.message.replace(JSON_SYNTAX_REGEXP, function (placeholder) {
|
||||||
|
return str.substring(index, index + placeholder.length)
|
||||||
|
}),
|
||||||
|
stack: e.stack
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Get the first non-whitespace character in a string.
|
||||||
|
*
|
||||||
|
* @param {string} str
|
||||||
|
* @return {function}
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
function firstchar (str) {
|
||||||
|
var match = FIRST_CHAR_REGEXP.exec(str)
|
||||||
|
|
||||||
|
return match
|
||||||
|
? match[1]
|
||||||
|
: undefined
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Normalize a SyntaxError for JSON.parse.
|
||||||
|
*
|
||||||
|
* @param {SyntaxError} error
|
||||||
|
* @param {object} obj
|
||||||
|
* @return {SyntaxError}
|
||||||
|
*/
|
||||||
|
|
||||||
|
function normalizeJsonSyntaxError (error, obj) {
|
||||||
|
var keys = Object.getOwnPropertyNames(error)
|
||||||
|
|
||||||
|
for (var i = 0; i < keys.length; i++) {
|
||||||
|
var key = keys[i]
|
||||||
|
if (key !== 'stack' && key !== 'message') {
|
||||||
|
delete error[key]
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// replace stack before message for Node.js 0.10 and below
|
||||||
|
error.stack = obj.stack.replace(error.message, obj.message)
|
||||||
|
error.message = obj.message
|
||||||
|
|
||||||
|
return error
|
||||||
|
}
|
||||||
+75
@@ -0,0 +1,75 @@
|
|||||||
|
/*!
|
||||||
|
* body-parser
|
||||||
|
* Copyright(c) 2014-2015 Douglas Christopher Wilson
|
||||||
|
* MIT Licensed
|
||||||
|
*/
|
||||||
|
|
||||||
|
'use strict'
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module dependencies.
|
||||||
|
*/
|
||||||
|
|
||||||
|
var debug = require('debug')('body-parser:raw')
|
||||||
|
var isFinished = require('on-finished').isFinished
|
||||||
|
var read = require('../read')
|
||||||
|
var typeis = require('type-is')
|
||||||
|
var { normalizeOptions } = require('../utils')
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module exports.
|
||||||
|
*/
|
||||||
|
|
||||||
|
module.exports = raw
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Create a middleware to parse raw bodies.
|
||||||
|
*
|
||||||
|
* @param {object} [options]
|
||||||
|
* @return {function}
|
||||||
|
* @api public
|
||||||
|
*/
|
||||||
|
|
||||||
|
function raw (options) {
|
||||||
|
var { inflate, limit, verify, shouldParse } = normalizeOptions(options, 'application/octet-stream')
|
||||||
|
|
||||||
|
function parse (buf) {
|
||||||
|
return buf
|
||||||
|
}
|
||||||
|
|
||||||
|
return function rawParser (req, res, next) {
|
||||||
|
if (isFinished(req)) {
|
||||||
|
debug('body already parsed')
|
||||||
|
next()
|
||||||
|
return
|
||||||
|
}
|
||||||
|
|
||||||
|
if (!('body' in req)) {
|
||||||
|
req.body = undefined
|
||||||
|
}
|
||||||
|
|
||||||
|
// skip requests without bodies
|
||||||
|
if (!typeis.hasBody(req)) {
|
||||||
|
debug('skip empty body')
|
||||||
|
next()
|
||||||
|
return
|
||||||
|
}
|
||||||
|
|
||||||
|
debug('content-type %j', req.headers['content-type'])
|
||||||
|
|
||||||
|
// determine if request should be parsed
|
||||||
|
if (!shouldParse(req)) {
|
||||||
|
debug('skip parsing')
|
||||||
|
next()
|
||||||
|
return
|
||||||
|
}
|
||||||
|
|
||||||
|
// read
|
||||||
|
read(req, res, next, parse, debug, {
|
||||||
|
encoding: null,
|
||||||
|
inflate,
|
||||||
|
limit,
|
||||||
|
verify
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
+80
@@ -0,0 +1,80 @@
|
|||||||
|
/*!
|
||||||
|
* body-parser
|
||||||
|
* Copyright(c) 2014-2015 Douglas Christopher Wilson
|
||||||
|
* MIT Licensed
|
||||||
|
*/
|
||||||
|
|
||||||
|
'use strict'
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module dependencies.
|
||||||
|
*/
|
||||||
|
|
||||||
|
var debug = require('debug')('body-parser:text')
|
||||||
|
var isFinished = require('on-finished').isFinished
|
||||||
|
var read = require('../read')
|
||||||
|
var typeis = require('type-is')
|
||||||
|
var { getCharset, normalizeOptions } = require('../utils')
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module exports.
|
||||||
|
*/
|
||||||
|
|
||||||
|
module.exports = text
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Create a middleware to parse text bodies.
|
||||||
|
*
|
||||||
|
* @param {object} [options]
|
||||||
|
* @return {function}
|
||||||
|
* @api public
|
||||||
|
*/
|
||||||
|
|
||||||
|
function text (options) {
|
||||||
|
var { inflate, limit, verify, shouldParse } = normalizeOptions(options, 'text/plain')
|
||||||
|
|
||||||
|
var defaultCharset = options?.defaultCharset || 'utf-8'
|
||||||
|
|
||||||
|
function parse (buf) {
|
||||||
|
return buf
|
||||||
|
}
|
||||||
|
|
||||||
|
return function textParser (req, res, next) {
|
||||||
|
if (isFinished(req)) {
|
||||||
|
debug('body already parsed')
|
||||||
|
next()
|
||||||
|
return
|
||||||
|
}
|
||||||
|
|
||||||
|
if (!('body' in req)) {
|
||||||
|
req.body = undefined
|
||||||
|
}
|
||||||
|
|
||||||
|
// skip requests without bodies
|
||||||
|
if (!typeis.hasBody(req)) {
|
||||||
|
debug('skip empty body')
|
||||||
|
next()
|
||||||
|
return
|
||||||
|
}
|
||||||
|
|
||||||
|
debug('content-type %j', req.headers['content-type'])
|
||||||
|
|
||||||
|
// determine if request should be parsed
|
||||||
|
if (!shouldParse(req)) {
|
||||||
|
debug('skip parsing')
|
||||||
|
next()
|
||||||
|
return
|
||||||
|
}
|
||||||
|
|
||||||
|
// get charset
|
||||||
|
var charset = getCharset(req) || defaultCharset
|
||||||
|
|
||||||
|
// read
|
||||||
|
read(req, res, next, parse, debug, {
|
||||||
|
encoding: charset,
|
||||||
|
inflate,
|
||||||
|
limit,
|
||||||
|
verify
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
+177
@@ -0,0 +1,177 @@
|
|||||||
|
/*!
|
||||||
|
* body-parser
|
||||||
|
* Copyright(c) 2014 Jonathan Ong
|
||||||
|
* Copyright(c) 2014-2015 Douglas Christopher Wilson
|
||||||
|
* MIT Licensed
|
||||||
|
*/
|
||||||
|
|
||||||
|
'use strict'
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module dependencies.
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
var createError = require('http-errors')
|
||||||
|
var debug = require('debug')('body-parser:urlencoded')
|
||||||
|
var isFinished = require('on-finished').isFinished
|
||||||
|
var read = require('../read')
|
||||||
|
var typeis = require('type-is')
|
||||||
|
var qs = require('qs')
|
||||||
|
var { getCharset, normalizeOptions } = require('../utils')
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module exports.
|
||||||
|
*/
|
||||||
|
|
||||||
|
module.exports = urlencoded
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Create a middleware to parse urlencoded bodies.
|
||||||
|
*
|
||||||
|
* @param {object} [options]
|
||||||
|
* @return {function}
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
function urlencoded (options) {
|
||||||
|
var { inflate, limit, verify, shouldParse } = normalizeOptions(options, 'application/x-www-form-urlencoded')
|
||||||
|
|
||||||
|
var defaultCharset = options?.defaultCharset || 'utf-8'
|
||||||
|
if (defaultCharset !== 'utf-8' && defaultCharset !== 'iso-8859-1') {
|
||||||
|
throw new TypeError('option defaultCharset must be either utf-8 or iso-8859-1')
|
||||||
|
}
|
||||||
|
|
||||||
|
// create the appropriate query parser
|
||||||
|
var queryparse = createQueryParser(options)
|
||||||
|
|
||||||
|
function parse (body, encoding) {
|
||||||
|
return body.length
|
||||||
|
? queryparse(body, encoding)
|
||||||
|
: {}
|
||||||
|
}
|
||||||
|
|
||||||
|
return function urlencodedParser (req, res, next) {
|
||||||
|
if (isFinished(req)) {
|
||||||
|
debug('body already parsed')
|
||||||
|
next()
|
||||||
|
return
|
||||||
|
}
|
||||||
|
|
||||||
|
if (!('body' in req)) {
|
||||||
|
req.body = undefined
|
||||||
|
}
|
||||||
|
|
||||||
|
// skip requests without bodies
|
||||||
|
if (!typeis.hasBody(req)) {
|
||||||
|
debug('skip empty body')
|
||||||
|
next()
|
||||||
|
return
|
||||||
|
}
|
||||||
|
|
||||||
|
debug('content-type %j', req.headers['content-type'])
|
||||||
|
|
||||||
|
// determine if request should be parsed
|
||||||
|
if (!shouldParse(req)) {
|
||||||
|
debug('skip parsing')
|
||||||
|
next()
|
||||||
|
return
|
||||||
|
}
|
||||||
|
|
||||||
|
// assert charset
|
||||||
|
var charset = getCharset(req) || defaultCharset
|
||||||
|
if (charset !== 'utf-8' && charset !== 'iso-8859-1') {
|
||||||
|
debug('invalid charset')
|
||||||
|
next(createError(415, 'unsupported charset "' + charset.toUpperCase() + '"', {
|
||||||
|
charset: charset,
|
||||||
|
type: 'charset.unsupported'
|
||||||
|
}))
|
||||||
|
return
|
||||||
|
}
|
||||||
|
|
||||||
|
// read
|
||||||
|
read(req, res, next, parse, debug, {
|
||||||
|
encoding: charset,
|
||||||
|
inflate,
|
||||||
|
limit,
|
||||||
|
verify
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Get the extended query parser.
|
||||||
|
*
|
||||||
|
* @param {object} options
|
||||||
|
*/
|
||||||
|
|
||||||
|
function createQueryParser (options) {
|
||||||
|
var extended = Boolean(options?.extended)
|
||||||
|
var parameterLimit = options?.parameterLimit !== undefined
|
||||||
|
? options?.parameterLimit
|
||||||
|
: 1000
|
||||||
|
var charsetSentinel = options?.charsetSentinel
|
||||||
|
var interpretNumericEntities = options?.interpretNumericEntities
|
||||||
|
var depth = extended ? (options?.depth !== undefined ? options?.depth : 32) : 0
|
||||||
|
|
||||||
|
if (isNaN(parameterLimit) || parameterLimit < 1) {
|
||||||
|
throw new TypeError('option parameterLimit must be a positive number')
|
||||||
|
}
|
||||||
|
|
||||||
|
if (isNaN(depth) || depth < 0) {
|
||||||
|
throw new TypeError('option depth must be a zero or a positive number')
|
||||||
|
}
|
||||||
|
|
||||||
|
if (isFinite(parameterLimit)) {
|
||||||
|
parameterLimit = parameterLimit | 0
|
||||||
|
}
|
||||||
|
|
||||||
|
return function queryparse (body, encoding) {
|
||||||
|
var paramCount = parameterCount(body, parameterLimit)
|
||||||
|
|
||||||
|
if (paramCount === undefined) {
|
||||||
|
debug('too many parameters')
|
||||||
|
throw createError(413, 'too many parameters', {
|
||||||
|
type: 'parameters.too.many'
|
||||||
|
})
|
||||||
|
}
|
||||||
|
|
||||||
|
var arrayLimit = extended ? Math.max(100, paramCount) : 0
|
||||||
|
|
||||||
|
debug('parse ' + (extended ? 'extended ' : '') + 'urlencoding')
|
||||||
|
try {
|
||||||
|
return qs.parse(body, {
|
||||||
|
allowPrototypes: true,
|
||||||
|
arrayLimit: arrayLimit,
|
||||||
|
depth: depth,
|
||||||
|
charsetSentinel: charsetSentinel,
|
||||||
|
interpretNumericEntities: interpretNumericEntities,
|
||||||
|
charset: encoding,
|
||||||
|
parameterLimit: parameterLimit,
|
||||||
|
strictDepth: true
|
||||||
|
})
|
||||||
|
} catch (err) {
|
||||||
|
if (err instanceof RangeError) {
|
||||||
|
throw createError(400, 'The input exceeded the depth', {
|
||||||
|
type: 'querystring.parse.rangeError'
|
||||||
|
})
|
||||||
|
} else {
|
||||||
|
throw err
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Count the number of parameters, stopping once limit reached
|
||||||
|
*
|
||||||
|
* @param {string} body
|
||||||
|
* @param {number} limit
|
||||||
|
* @api private
|
||||||
|
*/
|
||||||
|
|
||||||
|
function parameterCount (body, limit) {
|
||||||
|
var len = body.split('&').length
|
||||||
|
|
||||||
|
return len > limit ? undefined : len - 1
|
||||||
|
}
|
||||||
+83
@@ -0,0 +1,83 @@
|
|||||||
|
'use strict'
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module dependencies.
|
||||||
|
*/
|
||||||
|
|
||||||
|
var bytes = require('bytes')
|
||||||
|
var contentType = require('content-type')
|
||||||
|
var typeis = require('type-is')
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module exports.
|
||||||
|
*/
|
||||||
|
|
||||||
|
module.exports = {
|
||||||
|
getCharset,
|
||||||
|
normalizeOptions
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Get the charset of a request.
|
||||||
|
*
|
||||||
|
* @param {object} req
|
||||||
|
* @api private
|
||||||
|
*/
|
||||||
|
|
||||||
|
function getCharset (req) {
|
||||||
|
try {
|
||||||
|
return (contentType.parse(req).parameters.charset || '').toLowerCase()
|
||||||
|
} catch {
|
||||||
|
return undefined
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Get the simple type checker.
|
||||||
|
*
|
||||||
|
* @param {string | string[]} type
|
||||||
|
* @return {function}
|
||||||
|
*/
|
||||||
|
|
||||||
|
function typeChecker (type) {
|
||||||
|
return function checkType (req) {
|
||||||
|
return Boolean(typeis(req, type))
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Normalizes the common options for all parsers.
|
||||||
|
*
|
||||||
|
* @param {object} options options to normalize
|
||||||
|
* @param {string | string[] | function} defaultType default content type(s) or a function to determine it
|
||||||
|
* @returns {object}
|
||||||
|
*/
|
||||||
|
function normalizeOptions (options, defaultType) {
|
||||||
|
if (!defaultType) {
|
||||||
|
// Parsers must define a default content type
|
||||||
|
throw new TypeError('defaultType must be provided')
|
||||||
|
}
|
||||||
|
|
||||||
|
var inflate = options?.inflate !== false
|
||||||
|
var limit = typeof options?.limit !== 'number'
|
||||||
|
? bytes.parse(options?.limit || '100kb')
|
||||||
|
: options?.limit
|
||||||
|
var type = options?.type || defaultType
|
||||||
|
var verify = options?.verify || false
|
||||||
|
|
||||||
|
if (verify !== false && typeof verify !== 'function') {
|
||||||
|
throw new TypeError('option verify must be function')
|
||||||
|
}
|
||||||
|
|
||||||
|
// create the appropriate type checking function
|
||||||
|
var shouldParse = typeof type !== 'function'
|
||||||
|
? typeChecker(type)
|
||||||
|
: type
|
||||||
|
|
||||||
|
return {
|
||||||
|
inflate,
|
||||||
|
limit,
|
||||||
|
verify,
|
||||||
|
shouldParse
|
||||||
|
}
|
||||||
|
}
|
||||||
+49
@@ -0,0 +1,49 @@
|
|||||||
|
{
|
||||||
|
"name": "body-parser",
|
||||||
|
"description": "Node.js body parsing middleware",
|
||||||
|
"version": "2.2.0",
|
||||||
|
"contributors": [
|
||||||
|
"Douglas Christopher Wilson <doug@somethingdoug.com>",
|
||||||
|
"Jonathan Ong <me@jongleberry.com> (http://jongleberry.com)"
|
||||||
|
],
|
||||||
|
"license": "MIT",
|
||||||
|
"repository": "expressjs/body-parser",
|
||||||
|
"dependencies": {
|
||||||
|
"bytes": "^3.1.2",
|
||||||
|
"content-type": "^1.0.5",
|
||||||
|
"debug": "^4.4.0",
|
||||||
|
"http-errors": "^2.0.0",
|
||||||
|
"iconv-lite": "^0.6.3",
|
||||||
|
"on-finished": "^2.4.1",
|
||||||
|
"qs": "^6.14.0",
|
||||||
|
"raw-body": "^3.0.0",
|
||||||
|
"type-is": "^2.0.0"
|
||||||
|
},
|
||||||
|
"devDependencies": {
|
||||||
|
"eslint": "8.34.0",
|
||||||
|
"eslint-config-standard": "14.1.1",
|
||||||
|
"eslint-plugin-import": "2.27.5",
|
||||||
|
"eslint-plugin-markdown": "3.0.0",
|
||||||
|
"eslint-plugin-node": "11.1.0",
|
||||||
|
"eslint-plugin-promise": "6.1.1",
|
||||||
|
"eslint-plugin-standard": "4.1.0",
|
||||||
|
"mocha": "^11.1.0",
|
||||||
|
"nyc": "^17.1.0",
|
||||||
|
"supertest": "^7.0.0"
|
||||||
|
},
|
||||||
|
"files": [
|
||||||
|
"lib/",
|
||||||
|
"LICENSE",
|
||||||
|
"HISTORY.md",
|
||||||
|
"index.js"
|
||||||
|
],
|
||||||
|
"engines": {
|
||||||
|
"node": ">=18"
|
||||||
|
},
|
||||||
|
"scripts": {
|
||||||
|
"lint": "eslint .",
|
||||||
|
"test": "mocha --reporter spec --check-leaks test/",
|
||||||
|
"test-ci": "nyc --reporter=lcovonly --reporter=text npm test",
|
||||||
|
"test-cov": "nyc --reporter=html --reporter=text npm test"
|
||||||
|
}
|
||||||
|
}
|
||||||
+97
@@ -0,0 +1,97 @@
|
|||||||
|
3.1.2 / 2022-01-27
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Fix return value for un-parsable strings
|
||||||
|
|
||||||
|
3.1.1 / 2021-11-15
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Fix "thousandsSeparator" incorrecting formatting fractional part
|
||||||
|
|
||||||
|
3.1.0 / 2019-01-22
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Add petabyte (`pb`) support
|
||||||
|
|
||||||
|
3.0.0 / 2017-08-31
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Change "kB" to "KB" in format output
|
||||||
|
* Remove support for Node.js 0.6
|
||||||
|
* Remove support for ComponentJS
|
||||||
|
|
||||||
|
2.5.0 / 2017-03-24
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Add option "unit"
|
||||||
|
|
||||||
|
2.4.0 / 2016-06-01
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Add option "unitSeparator"
|
||||||
|
|
||||||
|
2.3.0 / 2016-02-15
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Drop partial bytes on all parsed units
|
||||||
|
* Fix non-finite numbers to `.format` to return `null`
|
||||||
|
* Fix parsing byte string that looks like hex
|
||||||
|
* perf: hoist regular expressions
|
||||||
|
|
||||||
|
2.2.0 / 2015-11-13
|
||||||
|
==================
|
||||||
|
|
||||||
|
* add option "decimalPlaces"
|
||||||
|
* add option "fixedDecimals"
|
||||||
|
|
||||||
|
2.1.0 / 2015-05-21
|
||||||
|
==================
|
||||||
|
|
||||||
|
* add `.format` export
|
||||||
|
* add `.parse` export
|
||||||
|
|
||||||
|
2.0.2 / 2015-05-20
|
||||||
|
==================
|
||||||
|
|
||||||
|
* remove map recreation
|
||||||
|
* remove unnecessary object construction
|
||||||
|
|
||||||
|
2.0.1 / 2015-05-07
|
||||||
|
==================
|
||||||
|
|
||||||
|
* fix browserify require
|
||||||
|
* remove node.extend dependency
|
||||||
|
|
||||||
|
2.0.0 / 2015-04-12
|
||||||
|
==================
|
||||||
|
|
||||||
|
* add option "case"
|
||||||
|
* add option "thousandsSeparator"
|
||||||
|
* return "null" on invalid parse input
|
||||||
|
* support proper round-trip: bytes(bytes(num)) === num
|
||||||
|
* units no longer case sensitive when parsing
|
||||||
|
|
||||||
|
1.0.0 / 2014-05-05
|
||||||
|
==================
|
||||||
|
|
||||||
|
* add negative support. fixes #6
|
||||||
|
|
||||||
|
0.3.0 / 2014-03-19
|
||||||
|
==================
|
||||||
|
|
||||||
|
* added terabyte support
|
||||||
|
|
||||||
|
0.2.1 / 2013-04-01
|
||||||
|
==================
|
||||||
|
|
||||||
|
* add .component
|
||||||
|
|
||||||
|
0.2.0 / 2012-10-28
|
||||||
|
==================
|
||||||
|
|
||||||
|
* bytes(200).should.eql('200b')
|
||||||
|
|
||||||
|
0.1.0 / 2012-07-04
|
||||||
|
==================
|
||||||
|
|
||||||
|
* add bytes to string conversion [yields]
|
||||||
+23
@@ -0,0 +1,23 @@
|
|||||||
|
(The MIT License)
|
||||||
|
|
||||||
|
Copyright (c) 2012-2014 TJ Holowaychuk <tj@vision-media.ca>
|
||||||
|
Copyright (c) 2015 Jed Watson <jed.watson@me.com>
|
||||||
|
|
||||||
|
Permission is hereby granted, free of charge, to any person obtaining
|
||||||
|
a copy of this software and associated documentation files (the
|
||||||
|
'Software'), to deal in the Software without restriction, including
|
||||||
|
without limitation the rights to use, copy, modify, merge, publish,
|
||||||
|
distribute, sublicense, and/or sell copies of the Software, and to
|
||||||
|
permit persons to whom the Software is furnished to do so, subject to
|
||||||
|
the following conditions:
|
||||||
|
|
||||||
|
The above copyright notice and this permission notice shall be
|
||||||
|
included in all copies or substantial portions of the Software.
|
||||||
|
|
||||||
|
THE SOFTWARE IS PROVIDED 'AS IS', WITHOUT WARRANTY OF ANY KIND,
|
||||||
|
EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF
|
||||||
|
MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT.
|
||||||
|
IN NO EVENT SHALL THE AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY
|
||||||
|
CLAIM, DAMAGES OR OTHER LIABILITY, WHETHER IN AN ACTION OF CONTRACT,
|
||||||
|
TORT OR OTHERWISE, ARISING FROM, OUT OF OR IN CONNECTION WITH THE
|
||||||
|
SOFTWARE OR THE USE OR OTHER DEALINGS IN THE SOFTWARE.
|
||||||
+152
@@ -0,0 +1,152 @@
|
|||||||
|
# Bytes utility
|
||||||
|
|
||||||
|
[![NPM Version][npm-image]][npm-url]
|
||||||
|
[![NPM Downloads][downloads-image]][downloads-url]
|
||||||
|
[![Build Status][ci-image]][ci-url]
|
||||||
|
[![Test Coverage][coveralls-image]][coveralls-url]
|
||||||
|
|
||||||
|
Utility to parse a string bytes (ex: `1TB`) to bytes (`1099511627776`) and vice-versa.
|
||||||
|
|
||||||
|
## Installation
|
||||||
|
|
||||||
|
This is a [Node.js](https://nodejs.org/en/) module available through the
|
||||||
|
[npm registry](https://www.npmjs.com/). Installation is done using the
|
||||||
|
[`npm install` command](https://docs.npmjs.com/getting-started/installing-npm-packages-locally):
|
||||||
|
|
||||||
|
```bash
|
||||||
|
$ npm install bytes
|
||||||
|
```
|
||||||
|
|
||||||
|
## Usage
|
||||||
|
|
||||||
|
```js
|
||||||
|
var bytes = require('bytes');
|
||||||
|
```
|
||||||
|
|
||||||
|
#### bytes(number|string value, [options]): number|string|null
|
||||||
|
|
||||||
|
Default export function. Delegates to either `bytes.format` or `bytes.parse` based on the type of `value`.
|
||||||
|
|
||||||
|
**Arguments**
|
||||||
|
|
||||||
|
| Name | Type | Description |
|
||||||
|
|---------|----------|--------------------|
|
||||||
|
| value | `number`|`string` | Number value to format or string value to parse |
|
||||||
|
| options | `Object` | Conversion options for `format` |
|
||||||
|
|
||||||
|
**Returns**
|
||||||
|
|
||||||
|
| Name | Type | Description |
|
||||||
|
|---------|------------------|-------------------------------------------------|
|
||||||
|
| results | `string`|`number`|`null` | Return null upon error. Numeric value in bytes, or string value otherwise. |
|
||||||
|
|
||||||
|
**Example**
|
||||||
|
|
||||||
|
```js
|
||||||
|
bytes(1024);
|
||||||
|
// output: '1KB'
|
||||||
|
|
||||||
|
bytes('1KB');
|
||||||
|
// output: 1024
|
||||||
|
```
|
||||||
|
|
||||||
|
#### bytes.format(number value, [options]): string|null
|
||||||
|
|
||||||
|
Format the given value in bytes into a string. If the value is negative, it is kept as such. If it is a float, it is
|
||||||
|
rounded.
|
||||||
|
|
||||||
|
**Arguments**
|
||||||
|
|
||||||
|
| Name | Type | Description |
|
||||||
|
|---------|----------|--------------------|
|
||||||
|
| value | `number` | Value in bytes |
|
||||||
|
| options | `Object` | Conversion options |
|
||||||
|
|
||||||
|
**Options**
|
||||||
|
|
||||||
|
| Property | Type | Description |
|
||||||
|
|-------------------|--------|-----------------------------------------------------------------------------------------|
|
||||||
|
| decimalPlaces | `number`|`null` | Maximum number of decimal places to include in output. Default value to `2`. |
|
||||||
|
| fixedDecimals | `boolean`|`null` | Whether to always display the maximum number of decimal places. Default value to `false` |
|
||||||
|
| thousandsSeparator | `string`|`null` | Example of values: `' '`, `','` and `'.'`... Default value to `''`. |
|
||||||
|
| unit | `string`|`null` | The unit in which the result will be returned (B/KB/MB/GB/TB). Default value to `''` (which means auto detect). |
|
||||||
|
| unitSeparator | `string`|`null` | Separator to use between number and unit. Default value to `''`. |
|
||||||
|
|
||||||
|
**Returns**
|
||||||
|
|
||||||
|
| Name | Type | Description |
|
||||||
|
|---------|------------------|-------------------------------------------------|
|
||||||
|
| results | `string`|`null` | Return null upon error. String value otherwise. |
|
||||||
|
|
||||||
|
**Example**
|
||||||
|
|
||||||
|
```js
|
||||||
|
bytes.format(1024);
|
||||||
|
// output: '1KB'
|
||||||
|
|
||||||
|
bytes.format(1000);
|
||||||
|
// output: '1000B'
|
||||||
|
|
||||||
|
bytes.format(1000, {thousandsSeparator: ' '});
|
||||||
|
// output: '1 000B'
|
||||||
|
|
||||||
|
bytes.format(1024 * 1.7, {decimalPlaces: 0});
|
||||||
|
// output: '2KB'
|
||||||
|
|
||||||
|
bytes.format(1024, {unitSeparator: ' '});
|
||||||
|
// output: '1 KB'
|
||||||
|
```
|
||||||
|
|
||||||
|
#### bytes.parse(string|number value): number|null
|
||||||
|
|
||||||
|
Parse the string value into an integer in bytes. If no unit is given, or `value`
|
||||||
|
is a number, it is assumed the value is in bytes.
|
||||||
|
|
||||||
|
Supported units and abbreviations are as follows and are case-insensitive:
|
||||||
|
|
||||||
|
* `b` for bytes
|
||||||
|
* `kb` for kilobytes
|
||||||
|
* `mb` for megabytes
|
||||||
|
* `gb` for gigabytes
|
||||||
|
* `tb` for terabytes
|
||||||
|
* `pb` for petabytes
|
||||||
|
|
||||||
|
The units are in powers of two, not ten. This means 1kb = 1024b according to this parser.
|
||||||
|
|
||||||
|
**Arguments**
|
||||||
|
|
||||||
|
| Name | Type | Description |
|
||||||
|
|---------------|--------|--------------------|
|
||||||
|
| value | `string`|`number` | String to parse, or number in bytes. |
|
||||||
|
|
||||||
|
**Returns**
|
||||||
|
|
||||||
|
| Name | Type | Description |
|
||||||
|
|---------|-------------|-------------------------|
|
||||||
|
| results | `number`|`null` | Return null upon error. Value in bytes otherwise. |
|
||||||
|
|
||||||
|
**Example**
|
||||||
|
|
||||||
|
```js
|
||||||
|
bytes.parse('1KB');
|
||||||
|
// output: 1024
|
||||||
|
|
||||||
|
bytes.parse('1024');
|
||||||
|
// output: 1024
|
||||||
|
|
||||||
|
bytes.parse(1024);
|
||||||
|
// output: 1024
|
||||||
|
```
|
||||||
|
|
||||||
|
## License
|
||||||
|
|
||||||
|
[MIT](LICENSE)
|
||||||
|
|
||||||
|
[ci-image]: https://badgen.net/github/checks/visionmedia/bytes.js/master?label=ci
|
||||||
|
[ci-url]: https://github.com/visionmedia/bytes.js/actions?query=workflow%3Aci
|
||||||
|
[coveralls-image]: https://badgen.net/coveralls/c/github/visionmedia/bytes.js/master
|
||||||
|
[coveralls-url]: https://coveralls.io/r/visionmedia/bytes.js?branch=master
|
||||||
|
[downloads-image]: https://badgen.net/npm/dm/bytes
|
||||||
|
[downloads-url]: https://npmjs.org/package/bytes
|
||||||
|
[npm-image]: https://badgen.net/npm/v/bytes
|
||||||
|
[npm-url]: https://npmjs.org/package/bytes
|
||||||
+170
@@ -0,0 +1,170 @@
|
|||||||
|
/*!
|
||||||
|
* bytes
|
||||||
|
* Copyright(c) 2012-2014 TJ Holowaychuk
|
||||||
|
* Copyright(c) 2015 Jed Watson
|
||||||
|
* MIT Licensed
|
||||||
|
*/
|
||||||
|
|
||||||
|
'use strict';
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module exports.
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
module.exports = bytes;
|
||||||
|
module.exports.format = format;
|
||||||
|
module.exports.parse = parse;
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module variables.
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
var formatThousandsRegExp = /\B(?=(\d{3})+(?!\d))/g;
|
||||||
|
|
||||||
|
var formatDecimalsRegExp = /(?:\.0*|(\.[^0]+)0+)$/;
|
||||||
|
|
||||||
|
var map = {
|
||||||
|
b: 1,
|
||||||
|
kb: 1 << 10,
|
||||||
|
mb: 1 << 20,
|
||||||
|
gb: 1 << 30,
|
||||||
|
tb: Math.pow(1024, 4),
|
||||||
|
pb: Math.pow(1024, 5),
|
||||||
|
};
|
||||||
|
|
||||||
|
var parseRegExp = /^((-|\+)?(\d+(?:\.\d+)?)) *(kb|mb|gb|tb|pb)$/i;
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Convert the given value in bytes into a string or parse to string to an integer in bytes.
|
||||||
|
*
|
||||||
|
* @param {string|number} value
|
||||||
|
* @param {{
|
||||||
|
* case: [string],
|
||||||
|
* decimalPlaces: [number]
|
||||||
|
* fixedDecimals: [boolean]
|
||||||
|
* thousandsSeparator: [string]
|
||||||
|
* unitSeparator: [string]
|
||||||
|
* }} [options] bytes options.
|
||||||
|
*
|
||||||
|
* @returns {string|number|null}
|
||||||
|
*/
|
||||||
|
|
||||||
|
function bytes(value, options) {
|
||||||
|
if (typeof value === 'string') {
|
||||||
|
return parse(value);
|
||||||
|
}
|
||||||
|
|
||||||
|
if (typeof value === 'number') {
|
||||||
|
return format(value, options);
|
||||||
|
}
|
||||||
|
|
||||||
|
return null;
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Format the given value in bytes into a string.
|
||||||
|
*
|
||||||
|
* If the value is negative, it is kept as such. If it is a float,
|
||||||
|
* it is rounded.
|
||||||
|
*
|
||||||
|
* @param {number} value
|
||||||
|
* @param {object} [options]
|
||||||
|
* @param {number} [options.decimalPlaces=2]
|
||||||
|
* @param {number} [options.fixedDecimals=false]
|
||||||
|
* @param {string} [options.thousandsSeparator=]
|
||||||
|
* @param {string} [options.unit=]
|
||||||
|
* @param {string} [options.unitSeparator=]
|
||||||
|
*
|
||||||
|
* @returns {string|null}
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
function format(value, options) {
|
||||||
|
if (!Number.isFinite(value)) {
|
||||||
|
return null;
|
||||||
|
}
|
||||||
|
|
||||||
|
var mag = Math.abs(value);
|
||||||
|
var thousandsSeparator = (options && options.thousandsSeparator) || '';
|
||||||
|
var unitSeparator = (options && options.unitSeparator) || '';
|
||||||
|
var decimalPlaces = (options && options.decimalPlaces !== undefined) ? options.decimalPlaces : 2;
|
||||||
|
var fixedDecimals = Boolean(options && options.fixedDecimals);
|
||||||
|
var unit = (options && options.unit) || '';
|
||||||
|
|
||||||
|
if (!unit || !map[unit.toLowerCase()]) {
|
||||||
|
if (mag >= map.pb) {
|
||||||
|
unit = 'PB';
|
||||||
|
} else if (mag >= map.tb) {
|
||||||
|
unit = 'TB';
|
||||||
|
} else if (mag >= map.gb) {
|
||||||
|
unit = 'GB';
|
||||||
|
} else if (mag >= map.mb) {
|
||||||
|
unit = 'MB';
|
||||||
|
} else if (mag >= map.kb) {
|
||||||
|
unit = 'KB';
|
||||||
|
} else {
|
||||||
|
unit = 'B';
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
var val = value / map[unit.toLowerCase()];
|
||||||
|
var str = val.toFixed(decimalPlaces);
|
||||||
|
|
||||||
|
if (!fixedDecimals) {
|
||||||
|
str = str.replace(formatDecimalsRegExp, '$1');
|
||||||
|
}
|
||||||
|
|
||||||
|
if (thousandsSeparator) {
|
||||||
|
str = str.split('.').map(function (s, i) {
|
||||||
|
return i === 0
|
||||||
|
? s.replace(formatThousandsRegExp, thousandsSeparator)
|
||||||
|
: s
|
||||||
|
}).join('.');
|
||||||
|
}
|
||||||
|
|
||||||
|
return str + unitSeparator + unit;
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Parse the string value into an integer in bytes.
|
||||||
|
*
|
||||||
|
* If no unit is given, it is assumed the value is in bytes.
|
||||||
|
*
|
||||||
|
* @param {number|string} val
|
||||||
|
*
|
||||||
|
* @returns {number|null}
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
function parse(val) {
|
||||||
|
if (typeof val === 'number' && !isNaN(val)) {
|
||||||
|
return val;
|
||||||
|
}
|
||||||
|
|
||||||
|
if (typeof val !== 'string') {
|
||||||
|
return null;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Test if the string passed is valid
|
||||||
|
var results = parseRegExp.exec(val);
|
||||||
|
var floatValue;
|
||||||
|
var unit = 'b';
|
||||||
|
|
||||||
|
if (!results) {
|
||||||
|
// Nothing could be extracted from the given string
|
||||||
|
floatValue = parseInt(val, 10);
|
||||||
|
unit = 'b'
|
||||||
|
} else {
|
||||||
|
// Retrieve the value and the unit
|
||||||
|
floatValue = parseFloat(results[1]);
|
||||||
|
unit = results[4].toLowerCase();
|
||||||
|
}
|
||||||
|
|
||||||
|
if (isNaN(floatValue)) {
|
||||||
|
return null;
|
||||||
|
}
|
||||||
|
|
||||||
|
return Math.floor(map[unit] * floatValue);
|
||||||
|
}
|
||||||
+42
@@ -0,0 +1,42 @@
|
|||||||
|
{
|
||||||
|
"name": "bytes",
|
||||||
|
"description": "Utility to parse a string bytes to bytes and vice-versa",
|
||||||
|
"version": "3.1.2",
|
||||||
|
"author": "TJ Holowaychuk <tj@vision-media.ca> (http://tjholowaychuk.com)",
|
||||||
|
"contributors": [
|
||||||
|
"Jed Watson <jed.watson@me.com>",
|
||||||
|
"Théo FIDRY <theo.fidry@gmail.com>"
|
||||||
|
],
|
||||||
|
"license": "MIT",
|
||||||
|
"keywords": [
|
||||||
|
"byte",
|
||||||
|
"bytes",
|
||||||
|
"utility",
|
||||||
|
"parse",
|
||||||
|
"parser",
|
||||||
|
"convert",
|
||||||
|
"converter"
|
||||||
|
],
|
||||||
|
"repository": "visionmedia/bytes.js",
|
||||||
|
"devDependencies": {
|
||||||
|
"eslint": "7.32.0",
|
||||||
|
"eslint-plugin-markdown": "2.2.1",
|
||||||
|
"mocha": "9.2.0",
|
||||||
|
"nyc": "15.1.0"
|
||||||
|
},
|
||||||
|
"files": [
|
||||||
|
"History.md",
|
||||||
|
"LICENSE",
|
||||||
|
"Readme.md",
|
||||||
|
"index.js"
|
||||||
|
],
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.8"
|
||||||
|
},
|
||||||
|
"scripts": {
|
||||||
|
"lint": "eslint .",
|
||||||
|
"test": "mocha --check-leaks --reporter spec",
|
||||||
|
"test-ci": "nyc --reporter=lcov --reporter=text npm test",
|
||||||
|
"test-cov": "nyc --reporter=html --reporter=text npm test"
|
||||||
|
}
|
||||||
|
}
|
||||||
+17
@@ -0,0 +1,17 @@
|
|||||||
|
{
|
||||||
|
"root": true,
|
||||||
|
|
||||||
|
"extends": "@ljharb",
|
||||||
|
|
||||||
|
"rules": {
|
||||||
|
"func-name-matching": 0,
|
||||||
|
"id-length": 0,
|
||||||
|
"new-cap": [2, {
|
||||||
|
"capIsNewExceptions": [
|
||||||
|
"GetIntrinsic",
|
||||||
|
],
|
||||||
|
}],
|
||||||
|
"no-extra-parens": 0,
|
||||||
|
"no-magic-numbers": 0,
|
||||||
|
},
|
||||||
|
}
|
||||||
+12
@@ -0,0 +1,12 @@
|
|||||||
|
# These are supported funding model platforms
|
||||||
|
|
||||||
|
github: [ljharb]
|
||||||
|
patreon: # Replace with a single Patreon username
|
||||||
|
open_collective: # Replace with a single Open Collective username
|
||||||
|
ko_fi: # Replace with a single Ko-fi username
|
||||||
|
tidelift: npm/call-bind-apply-helpers
|
||||||
|
community_bridge: # Replace with a single Community Bridge project-name e.g., cloud-foundry
|
||||||
|
liberapay: # Replace with a single Liberapay username
|
||||||
|
issuehunt: # Replace with a single IssueHunt username
|
||||||
|
otechie: # Replace with a single Otechie username
|
||||||
|
custom: # Replace with up to 4 custom sponsorship URLs e.g., ['link1', 'link2']
|
||||||
+9
@@ -0,0 +1,9 @@
|
|||||||
|
{
|
||||||
|
"all": true,
|
||||||
|
"check-coverage": false,
|
||||||
|
"reporter": ["text-summary", "text", "html", "json"],
|
||||||
|
"exclude": [
|
||||||
|
"coverage",
|
||||||
|
"test"
|
||||||
|
]
|
||||||
|
}
|
||||||
+30
@@ -0,0 +1,30 @@
|
|||||||
|
# Changelog
|
||||||
|
|
||||||
|
All notable changes to this project will be documented in this file.
|
||||||
|
|
||||||
|
The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/)
|
||||||
|
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).
|
||||||
|
|
||||||
|
## [v1.0.2](https://github.com/ljharb/call-bind-apply-helpers/compare/v1.0.1...v1.0.2) - 2025-02-12
|
||||||
|
|
||||||
|
### Commits
|
||||||
|
|
||||||
|
- [types] improve inferred types [`e6f9586`](https://github.com/ljharb/call-bind-apply-helpers/commit/e6f95860a3c72879cb861a858cdfb8138fbedec1)
|
||||||
|
- [Dev Deps] update `@arethetypeswrong/cli`, `@ljharb/tsconfig`, `@types/tape`, `es-value-fixtures`, `for-each`, `has-strict-mode`, `object-inspect` [`e43d540`](https://github.com/ljharb/call-bind-apply-helpers/commit/e43d5409f97543bfbb11f345d47d8ce4e066d8c1)
|
||||||
|
|
||||||
|
## [v1.0.1](https://github.com/ljharb/call-bind-apply-helpers/compare/v1.0.0...v1.0.1) - 2024-12-08
|
||||||
|
|
||||||
|
### Commits
|
||||||
|
|
||||||
|
- [types] `reflectApply`: fix types [`4efc396`](https://github.com/ljharb/call-bind-apply-helpers/commit/4efc3965351a4f02cc55e836fa391d3d11ef2ef8)
|
||||||
|
- [Fix] `reflectApply`: oops, Reflect is not a function [`83cc739`](https://github.com/ljharb/call-bind-apply-helpers/commit/83cc7395de6b79b7730bdf092f1436f0b1263c75)
|
||||||
|
- [Dev Deps] update `@arethetypeswrong/cli` [`80bd5d3`](https://github.com/ljharb/call-bind-apply-helpers/commit/80bd5d3ae58b4f6b6995ce439dd5a1bcb178a940)
|
||||||
|
|
||||||
|
## v1.0.0 - 2024-12-05
|
||||||
|
|
||||||
|
### Commits
|
||||||
|
|
||||||
|
- Initial implementation, tests, readme [`7879629`](https://github.com/ljharb/call-bind-apply-helpers/commit/78796290f9b7430c9934d6f33d94ae9bc89fce04)
|
||||||
|
- Initial commit [`3f1dc16`](https://github.com/ljharb/call-bind-apply-helpers/commit/3f1dc164afc43285631b114a5f9dd9137b2b952f)
|
||||||
|
- npm init [`081df04`](https://github.com/ljharb/call-bind-apply-helpers/commit/081df048c312fcee400922026f6e97281200a603)
|
||||||
|
- Only apps should have lockfiles [`5b9ca0f`](https://github.com/ljharb/call-bind-apply-helpers/commit/5b9ca0fe8101ebfaf309c549caac4e0a017ed930)
|
||||||
+21
@@ -0,0 +1,21 @@
|
|||||||
|
MIT License
|
||||||
|
|
||||||
|
Copyright (c) 2024 Jordan Harband
|
||||||
|
|
||||||
|
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||||
|
of this software and associated documentation files (the "Software"), to deal
|
||||||
|
in the Software without restriction, including without limitation the rights
|
||||||
|
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||||
|
copies of the Software, and to permit persons to whom the Software is
|
||||||
|
furnished to do so, subject to the following conditions:
|
||||||
|
|
||||||
|
The above copyright notice and this permission notice shall be included in all
|
||||||
|
copies or substantial portions of the Software.
|
||||||
|
|
||||||
|
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||||
|
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||||
|
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||||
|
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||||
|
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||||
|
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||||
|
SOFTWARE.
|
||||||
+62
@@ -0,0 +1,62 @@
|
|||||||
|
# call-bind-apply-helpers <sup>[![Version Badge][npm-version-svg]][package-url]</sup>
|
||||||
|
|
||||||
|
[![github actions][actions-image]][actions-url]
|
||||||
|
[![coverage][codecov-image]][codecov-url]
|
||||||
|
[![dependency status][deps-svg]][deps-url]
|
||||||
|
[![dev dependency status][dev-deps-svg]][dev-deps-url]
|
||||||
|
[![License][license-image]][license-url]
|
||||||
|
[![Downloads][downloads-image]][downloads-url]
|
||||||
|
|
||||||
|
[![npm badge][npm-badge-png]][package-url]
|
||||||
|
|
||||||
|
Helper functions around Function call/apply/bind, for use in `call-bind`.
|
||||||
|
|
||||||
|
The only packages that should likely ever use this package directly are `call-bind` and `get-intrinsic`.
|
||||||
|
Please use `call-bind` unless you have a very good reason not to.
|
||||||
|
|
||||||
|
## Getting started
|
||||||
|
|
||||||
|
```sh
|
||||||
|
npm install --save call-bind-apply-helpers
|
||||||
|
```
|
||||||
|
|
||||||
|
## Usage/Examples
|
||||||
|
|
||||||
|
```js
|
||||||
|
const assert = require('assert');
|
||||||
|
const callBindBasic = require('call-bind-apply-helpers');
|
||||||
|
|
||||||
|
function f(a, b) {
|
||||||
|
assert.equal(this, 1);
|
||||||
|
assert.equal(a, 2);
|
||||||
|
assert.equal(b, 3);
|
||||||
|
assert.equal(arguments.length, 2);
|
||||||
|
}
|
||||||
|
|
||||||
|
const fBound = callBindBasic([f, 1]);
|
||||||
|
|
||||||
|
delete Function.prototype.call;
|
||||||
|
delete Function.prototype.bind;
|
||||||
|
|
||||||
|
fBound(2, 3);
|
||||||
|
```
|
||||||
|
|
||||||
|
## Tests
|
||||||
|
|
||||||
|
Clone the repo, `npm install`, and run `npm test`
|
||||||
|
|
||||||
|
[package-url]: https://npmjs.org/package/call-bind-apply-helpers
|
||||||
|
[npm-version-svg]: https://versionbadg.es/ljharb/call-bind-apply-helpers.svg
|
||||||
|
[deps-svg]: https://david-dm.org/ljharb/call-bind-apply-helpers.svg
|
||||||
|
[deps-url]: https://david-dm.org/ljharb/call-bind-apply-helpers
|
||||||
|
[dev-deps-svg]: https://david-dm.org/ljharb/call-bind-apply-helpers/dev-status.svg
|
||||||
|
[dev-deps-url]: https://david-dm.org/ljharb/call-bind-apply-helpers#info=devDependencies
|
||||||
|
[npm-badge-png]: https://nodei.co/npm/call-bind-apply-helpers.png?downloads=true&stars=true
|
||||||
|
[license-image]: https://img.shields.io/npm/l/call-bind-apply-helpers.svg
|
||||||
|
[license-url]: LICENSE
|
||||||
|
[downloads-image]: https://img.shields.io/npm/dm/call-bind-apply-helpers.svg
|
||||||
|
[downloads-url]: https://npm-stat.com/charts.html?package=call-bind-apply-helpers
|
||||||
|
[codecov-image]: https://codecov.io/gh/ljharb/call-bind-apply-helpers/branch/main/graphs/badge.svg
|
||||||
|
[codecov-url]: https://app.codecov.io/gh/ljharb/call-bind-apply-helpers/
|
||||||
|
[actions-image]: https://img.shields.io/endpoint?url=https://github-actions-badge-u3jn4tfpocch.runkit.sh/ljharb/call-bind-apply-helpers
|
||||||
|
[actions-url]: https://github.com/ljharb/call-bind-apply-helpers/actions
|
||||||
+1
@@ -0,0 +1 @@
|
|||||||
|
export = Reflect.apply;
|
||||||
+10
@@ -0,0 +1,10 @@
|
|||||||
|
'use strict';
|
||||||
|
|
||||||
|
var bind = require('function-bind');
|
||||||
|
|
||||||
|
var $apply = require('./functionApply');
|
||||||
|
var $call = require('./functionCall');
|
||||||
|
var $reflectApply = require('./reflectApply');
|
||||||
|
|
||||||
|
/** @type {import('./actualApply')} */
|
||||||
|
module.exports = $reflectApply || bind.call($call, $apply);
|
||||||
+19
@@ -0,0 +1,19 @@
|
|||||||
|
import actualApply from './actualApply';
|
||||||
|
|
||||||
|
type TupleSplitHead<T extends any[], N extends number> = T['length'] extends N
|
||||||
|
? T
|
||||||
|
: T extends [...infer R, any]
|
||||||
|
? TupleSplitHead<R, N>
|
||||||
|
: never
|
||||||
|
|
||||||
|
type TupleSplitTail<T, N extends number, O extends any[] = []> = O['length'] extends N
|
||||||
|
? T
|
||||||
|
: T extends [infer F, ...infer R]
|
||||||
|
? TupleSplitTail<[...R], N, [...O, F]>
|
||||||
|
: never
|
||||||
|
|
||||||
|
type TupleSplit<T extends any[], N extends number> = [TupleSplitHead<T, N>, TupleSplitTail<T, N>]
|
||||||
|
|
||||||
|
declare function applyBind(...args: TupleSplit<Parameters<typeof actualApply>, 2>[1]): ReturnType<typeof actualApply>;
|
||||||
|
|
||||||
|
export = applyBind;
|
||||||
+10
@@ -0,0 +1,10 @@
|
|||||||
|
'use strict';
|
||||||
|
|
||||||
|
var bind = require('function-bind');
|
||||||
|
var $apply = require('./functionApply');
|
||||||
|
var actualApply = require('./actualApply');
|
||||||
|
|
||||||
|
/** @type {import('./applyBind')} */
|
||||||
|
module.exports = function applyBind() {
|
||||||
|
return actualApply(bind, $apply, arguments);
|
||||||
|
};
|
||||||
+1
@@ -0,0 +1 @@
|
|||||||
|
export = Function.prototype.apply;
|
||||||
+4
@@ -0,0 +1,4 @@
|
|||||||
|
'use strict';
|
||||||
|
|
||||||
|
/** @type {import('./functionApply')} */
|
||||||
|
module.exports = Function.prototype.apply;
|
||||||
+1
@@ -0,0 +1 @@
|
|||||||
|
export = Function.prototype.call;
|
||||||
+4
@@ -0,0 +1,4 @@
|
|||||||
|
'use strict';
|
||||||
|
|
||||||
|
/** @type {import('./functionCall')} */
|
||||||
|
module.exports = Function.prototype.call;
|
||||||
+64
@@ -0,0 +1,64 @@
|
|||||||
|
type RemoveFromTuple<
|
||||||
|
Tuple extends readonly unknown[],
|
||||||
|
RemoveCount extends number,
|
||||||
|
Index extends 1[] = []
|
||||||
|
> = Index["length"] extends RemoveCount
|
||||||
|
? Tuple
|
||||||
|
: Tuple extends [infer First, ...infer Rest]
|
||||||
|
? RemoveFromTuple<Rest, RemoveCount, [...Index, 1]>
|
||||||
|
: Tuple;
|
||||||
|
|
||||||
|
type ConcatTuples<
|
||||||
|
Prefix extends readonly unknown[],
|
||||||
|
Suffix extends readonly unknown[]
|
||||||
|
> = [...Prefix, ...Suffix];
|
||||||
|
|
||||||
|
type ExtractFunctionParams<T> = T extends (this: infer TThis, ...args: infer P extends readonly unknown[]) => infer R
|
||||||
|
? { thisArg: TThis; params: P; returnType: R }
|
||||||
|
: never;
|
||||||
|
|
||||||
|
type BindFunction<
|
||||||
|
T extends (this: any, ...args: any[]) => any,
|
||||||
|
TThis,
|
||||||
|
TBoundArgs extends readonly unknown[],
|
||||||
|
ReceiverBound extends boolean
|
||||||
|
> = ExtractFunctionParams<T> extends {
|
||||||
|
thisArg: infer OrigThis;
|
||||||
|
params: infer P extends readonly unknown[];
|
||||||
|
returnType: infer R;
|
||||||
|
}
|
||||||
|
? ReceiverBound extends true
|
||||||
|
? (...args: RemoveFromTuple<P, Extract<TBoundArgs["length"], number>>) => R extends [OrigThis, ...infer Rest]
|
||||||
|
? [TThis, ...Rest] // Replace `this` with `thisArg`
|
||||||
|
: R
|
||||||
|
: <U, RemainingArgs extends RemoveFromTuple<P, Extract<TBoundArgs["length"], number>>>(
|
||||||
|
thisArg: U,
|
||||||
|
...args: RemainingArgs
|
||||||
|
) => R extends [OrigThis, ...infer Rest]
|
||||||
|
? [U, ...ConcatTuples<TBoundArgs, Rest>] // Preserve bound args in return type
|
||||||
|
: R
|
||||||
|
: never;
|
||||||
|
|
||||||
|
declare function callBind<
|
||||||
|
const T extends (this: any, ...args: any[]) => any,
|
||||||
|
Extracted extends ExtractFunctionParams<T>,
|
||||||
|
const TBoundArgs extends Partial<Extracted["params"]> & readonly unknown[],
|
||||||
|
const TThis extends Extracted["thisArg"]
|
||||||
|
>(
|
||||||
|
args: [fn: T, thisArg: TThis, ...boundArgs: TBoundArgs]
|
||||||
|
): BindFunction<T, TThis, TBoundArgs, true>;
|
||||||
|
|
||||||
|
declare function callBind<
|
||||||
|
const T extends (this: any, ...args: any[]) => any,
|
||||||
|
Extracted extends ExtractFunctionParams<T>,
|
||||||
|
const TBoundArgs extends Partial<Extracted["params"]> & readonly unknown[]
|
||||||
|
>(
|
||||||
|
args: [fn: T, ...boundArgs: TBoundArgs]
|
||||||
|
): BindFunction<T, Extracted["thisArg"], TBoundArgs, false>;
|
||||||
|
|
||||||
|
declare function callBind<const TArgs extends readonly unknown[]>(
|
||||||
|
args: [fn: Exclude<TArgs[0], Function>, ...rest: TArgs]
|
||||||
|
): never;
|
||||||
|
|
||||||
|
// export as namespace callBind;
|
||||||
|
export = callBind;
|
||||||
+15
@@ -0,0 +1,15 @@
|
|||||||
|
'use strict';
|
||||||
|
|
||||||
|
var bind = require('function-bind');
|
||||||
|
var $TypeError = require('es-errors/type');
|
||||||
|
|
||||||
|
var $call = require('./functionCall');
|
||||||
|
var $actualApply = require('./actualApply');
|
||||||
|
|
||||||
|
/** @type {(args: [Function, thisArg?: unknown, ...args: unknown[]]) => Function} TODO FIXME, find a way to use import('.') */
|
||||||
|
module.exports = function callBindBasic(args) {
|
||||||
|
if (args.length < 1 || typeof args[0] !== 'function') {
|
||||||
|
throw new $TypeError('a function is required');
|
||||||
|
}
|
||||||
|
return $actualApply(bind, $call, args);
|
||||||
|
};
|
||||||
+85
@@ -0,0 +1,85 @@
|
|||||||
|
{
|
||||||
|
"name": "call-bind-apply-helpers",
|
||||||
|
"version": "1.0.2",
|
||||||
|
"description": "Helper functions around Function call/apply/bind, for use in `call-bind`",
|
||||||
|
"main": "index.js",
|
||||||
|
"exports": {
|
||||||
|
".": "./index.js",
|
||||||
|
"./actualApply": "./actualApply.js",
|
||||||
|
"./applyBind": "./applyBind.js",
|
||||||
|
"./functionApply": "./functionApply.js",
|
||||||
|
"./functionCall": "./functionCall.js",
|
||||||
|
"./reflectApply": "./reflectApply.js",
|
||||||
|
"./package.json": "./package.json"
|
||||||
|
},
|
||||||
|
"scripts": {
|
||||||
|
"prepack": "npmignore --auto --commentLines=auto",
|
||||||
|
"prepublish": "not-in-publish || npm run prepublishOnly",
|
||||||
|
"prepublishOnly": "safe-publish-latest",
|
||||||
|
"prelint": "evalmd README.md",
|
||||||
|
"lint": "eslint --ext=.js,.mjs .",
|
||||||
|
"postlint": "tsc -p . && attw -P",
|
||||||
|
"pretest": "npm run lint",
|
||||||
|
"tests-only": "nyc tape 'test/**/*.js'",
|
||||||
|
"test": "npm run tests-only",
|
||||||
|
"posttest": "npx npm@'>=10.2' audit --production",
|
||||||
|
"version": "auto-changelog && git add CHANGELOG.md",
|
||||||
|
"postversion": "auto-changelog && git add CHANGELOG.md && git commit --no-edit --amend && git tag -f \"v$(node -e \"console.log(require('./package.json').version)\")\""
|
||||||
|
},
|
||||||
|
"repository": {
|
||||||
|
"type": "git",
|
||||||
|
"url": "git+https://github.com/ljharb/call-bind-apply-helpers.git"
|
||||||
|
},
|
||||||
|
"author": "Jordan Harband <ljharb@gmail.com>",
|
||||||
|
"license": "MIT",
|
||||||
|
"bugs": {
|
||||||
|
"url": "https://github.com/ljharb/call-bind-apply-helpers/issues"
|
||||||
|
},
|
||||||
|
"homepage": "https://github.com/ljharb/call-bind-apply-helpers#readme",
|
||||||
|
"dependencies": {
|
||||||
|
"es-errors": "^1.3.0",
|
||||||
|
"function-bind": "^1.1.2"
|
||||||
|
},
|
||||||
|
"devDependencies": {
|
||||||
|
"@arethetypeswrong/cli": "^0.17.3",
|
||||||
|
"@ljharb/eslint-config": "^21.1.1",
|
||||||
|
"@ljharb/tsconfig": "^0.2.3",
|
||||||
|
"@types/for-each": "^0.3.3",
|
||||||
|
"@types/function-bind": "^1.1.10",
|
||||||
|
"@types/object-inspect": "^1.13.0",
|
||||||
|
"@types/tape": "^5.8.1",
|
||||||
|
"auto-changelog": "^2.5.0",
|
||||||
|
"encoding": "^0.1.13",
|
||||||
|
"es-value-fixtures": "^1.7.1",
|
||||||
|
"eslint": "=8.8.0",
|
||||||
|
"evalmd": "^0.0.19",
|
||||||
|
"for-each": "^0.3.5",
|
||||||
|
"has-strict-mode": "^1.1.0",
|
||||||
|
"in-publish": "^2.0.1",
|
||||||
|
"npmignore": "^0.3.1",
|
||||||
|
"nyc": "^10.3.2",
|
||||||
|
"object-inspect": "^1.13.4",
|
||||||
|
"safe-publish-latest": "^2.0.0",
|
||||||
|
"tape": "^5.9.0",
|
||||||
|
"typescript": "next"
|
||||||
|
},
|
||||||
|
"testling": {
|
||||||
|
"files": "test/index.js"
|
||||||
|
},
|
||||||
|
"auto-changelog": {
|
||||||
|
"output": "CHANGELOG.md",
|
||||||
|
"template": "keepachangelog",
|
||||||
|
"unreleased": false,
|
||||||
|
"commitLimit": false,
|
||||||
|
"backfillLimit": false,
|
||||||
|
"hideCredit": true
|
||||||
|
},
|
||||||
|
"publishConfig": {
|
||||||
|
"ignore": [
|
||||||
|
".github/workflows"
|
||||||
|
]
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
}
|
||||||
|
}
|
||||||
+3
@@ -0,0 +1,3 @@
|
|||||||
|
declare const reflectApply: false | typeof Reflect.apply;
|
||||||
|
|
||||||
|
export = reflectApply;
|
||||||
+4
@@ -0,0 +1,4 @@
|
|||||||
|
'use strict';
|
||||||
|
|
||||||
|
/** @type {import('./reflectApply')} */
|
||||||
|
module.exports = typeof Reflect !== 'undefined' && Reflect && Reflect.apply;
|
||||||
+63
@@ -0,0 +1,63 @@
|
|||||||
|
'use strict';
|
||||||
|
|
||||||
|
var callBind = require('../');
|
||||||
|
var hasStrictMode = require('has-strict-mode')();
|
||||||
|
var forEach = require('for-each');
|
||||||
|
var inspect = require('object-inspect');
|
||||||
|
var v = require('es-value-fixtures');
|
||||||
|
|
||||||
|
var test = require('tape');
|
||||||
|
|
||||||
|
test('callBindBasic', function (t) {
|
||||||
|
forEach(v.nonFunctions, function (nonFunction) {
|
||||||
|
t['throws'](
|
||||||
|
// @ts-expect-error
|
||||||
|
function () { callBind([nonFunction]); },
|
||||||
|
TypeError,
|
||||||
|
inspect(nonFunction) + ' is not a function'
|
||||||
|
);
|
||||||
|
});
|
||||||
|
|
||||||
|
var sentinel = { sentinel: true };
|
||||||
|
/** @type {<T, A extends number, B extends number>(this: T, a: A, b: B) => [T | undefined, A, B]} */
|
||||||
|
var func = function (a, b) {
|
||||||
|
// eslint-disable-next-line no-invalid-this
|
||||||
|
return [!hasStrictMode && this === global ? undefined : this, a, b];
|
||||||
|
};
|
||||||
|
t.equal(func.length, 2, 'original function length is 2');
|
||||||
|
|
||||||
|
/** type {(thisArg: unknown, a: number, b: number) => [unknown, number, number]} */
|
||||||
|
var bound = callBind([func]);
|
||||||
|
/** type {((a: number, b: number) => [typeof sentinel, typeof a, typeof b])} */
|
||||||
|
var boundR = callBind([func, sentinel]);
|
||||||
|
/** type {((b: number) => [typeof sentinel, number, typeof b])} */
|
||||||
|
var boundArg = callBind([func, sentinel, /** @type {const} */ (1)]);
|
||||||
|
|
||||||
|
// @ts-expect-error
|
||||||
|
t.deepEqual(bound(), [undefined, undefined, undefined], 'bound func with no args');
|
||||||
|
|
||||||
|
// @ts-expect-error
|
||||||
|
t.deepEqual(func(), [undefined, undefined, undefined], 'unbound func with too few args');
|
||||||
|
// @ts-expect-error
|
||||||
|
t.deepEqual(bound(1, 2), [hasStrictMode ? 1 : Object(1), 2, undefined], 'bound func too few args');
|
||||||
|
// @ts-expect-error
|
||||||
|
t.deepEqual(boundR(), [sentinel, undefined, undefined], 'bound func with receiver, with too few args');
|
||||||
|
// @ts-expect-error
|
||||||
|
t.deepEqual(boundArg(), [sentinel, 1, undefined], 'bound func with receiver and arg, with too few args');
|
||||||
|
|
||||||
|
t.deepEqual(func(1, 2), [undefined, 1, 2], 'unbound func with right args');
|
||||||
|
t.deepEqual(bound(1, 2, 3), [hasStrictMode ? 1 : Object(1), 2, 3], 'bound func with right args');
|
||||||
|
t.deepEqual(boundR(1, 2), [sentinel, 1, 2], 'bound func with receiver, with right args');
|
||||||
|
t.deepEqual(boundArg(2), [sentinel, 1, 2], 'bound func with receiver and arg, with right arg');
|
||||||
|
|
||||||
|
// @ts-expect-error
|
||||||
|
t.deepEqual(func(1, 2, 3), [undefined, 1, 2], 'unbound func with too many args');
|
||||||
|
// @ts-expect-error
|
||||||
|
t.deepEqual(bound(1, 2, 3, 4), [hasStrictMode ? 1 : Object(1), 2, 3], 'bound func with too many args');
|
||||||
|
// @ts-expect-error
|
||||||
|
t.deepEqual(boundR(1, 2, 3), [sentinel, 1, 2], 'bound func with receiver, with too many args');
|
||||||
|
// @ts-expect-error
|
||||||
|
t.deepEqual(boundArg(2, 3), [sentinel, 1, 2], 'bound func with receiver and arg, with too many args');
|
||||||
|
|
||||||
|
t.end();
|
||||||
|
});
|
||||||
+9
@@ -0,0 +1,9 @@
|
|||||||
|
{
|
||||||
|
"extends": "@ljharb/tsconfig",
|
||||||
|
"compilerOptions": {
|
||||||
|
"target": "es2021",
|
||||||
|
},
|
||||||
|
"exclude": [
|
||||||
|
"coverage",
|
||||||
|
],
|
||||||
|
}
|
||||||
+13
@@ -0,0 +1,13 @@
|
|||||||
|
{
|
||||||
|
"root": true,
|
||||||
|
|
||||||
|
"extends": "@ljharb",
|
||||||
|
|
||||||
|
"rules": {
|
||||||
|
"new-cap": [2, {
|
||||||
|
"capIsNewExceptions": [
|
||||||
|
"GetIntrinsic",
|
||||||
|
],
|
||||||
|
}],
|
||||||
|
},
|
||||||
|
}
|
||||||
+12
@@ -0,0 +1,12 @@
|
|||||||
|
# These are supported funding model platforms
|
||||||
|
|
||||||
|
github: [ljharb]
|
||||||
|
patreon: # Replace with a single Patreon username
|
||||||
|
open_collective: # Replace with a single Open Collective username
|
||||||
|
ko_fi: # Replace with a single Ko-fi username
|
||||||
|
tidelift: npm/call-bound
|
||||||
|
community_bridge: # Replace with a single Community Bridge project-name e.g., cloud-foundry
|
||||||
|
liberapay: # Replace with a single Liberapay username
|
||||||
|
issuehunt: # Replace with a single IssueHunt username
|
||||||
|
otechie: # Replace with a single Otechie username
|
||||||
|
custom: # Replace with up to 4 custom sponsorship URLs e.g., ['link1', 'link2']
|
||||||
+9
@@ -0,0 +1,9 @@
|
|||||||
|
{
|
||||||
|
"all": true,
|
||||||
|
"check-coverage": false,
|
||||||
|
"reporter": ["text-summary", "text", "html", "json"],
|
||||||
|
"exclude": [
|
||||||
|
"coverage",
|
||||||
|
"test"
|
||||||
|
]
|
||||||
|
}
|
||||||
+42
@@ -0,0 +1,42 @@
|
|||||||
|
# Changelog
|
||||||
|
|
||||||
|
All notable changes to this project will be documented in this file.
|
||||||
|
|
||||||
|
The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/)
|
||||||
|
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).
|
||||||
|
|
||||||
|
## [v1.0.4](https://github.com/ljharb/call-bound/compare/v1.0.3...v1.0.4) - 2025-03-03
|
||||||
|
|
||||||
|
### Commits
|
||||||
|
|
||||||
|
- [types] improve types [`e648922`](https://github.com/ljharb/call-bound/commit/e6489222a9e54f350fbf952ceabe51fd8b6027ff)
|
||||||
|
- [Dev Deps] update `@arethetypeswrong/cli`, `@ljharb/tsconfig`, `@types/tape`, `es-value-fixtures`, `for-each`, `has-strict-mode`, `object-inspect` [`a42a5eb`](https://github.com/ljharb/call-bound/commit/a42a5ebe6c1b54fcdc7997c7dc64fdca9e936719)
|
||||||
|
- [Deps] update `call-bind-apply-helpers`, `get-intrinsic` [`f529eac`](https://github.com/ljharb/call-bound/commit/f529eac132404c17156bbc23ab2297a25d0f20b8)
|
||||||
|
|
||||||
|
## [v1.0.3](https://github.com/ljharb/call-bound/compare/v1.0.2...v1.0.3) - 2024-12-15
|
||||||
|
|
||||||
|
### Commits
|
||||||
|
|
||||||
|
- [Refactor] use `call-bind-apply-helpers` instead of `call-bind` [`5e0b134`](https://github.com/ljharb/call-bound/commit/5e0b13496df14fb7d05dae9412f088da8d3f75be)
|
||||||
|
- [Deps] update `get-intrinsic` [`41fc967`](https://github.com/ljharb/call-bound/commit/41fc96732a22c7b7e8f381f93ccc54bb6293be2e)
|
||||||
|
- [readme] fix example [`79a0137`](https://github.com/ljharb/call-bound/commit/79a0137723f7c6d09c9c05452bbf8d5efb5d6e49)
|
||||||
|
- [meta] add `sideEffects` flag [`08b07be`](https://github.com/ljharb/call-bound/commit/08b07be7f1c03f67dc6f3cdaf0906259771859f7)
|
||||||
|
|
||||||
|
## [v1.0.2](https://github.com/ljharb/call-bound/compare/v1.0.1...v1.0.2) - 2024-12-10
|
||||||
|
|
||||||
|
### Commits
|
||||||
|
|
||||||
|
- [Dev Deps] update `@arethetypeswrong/cli`, `@ljharb/tsconfig`, `gopd` [`e6a5ffe`](https://github.com/ljharb/call-bound/commit/e6a5ffe849368fe4f74dfd6cdeca1b9baa39e8d5)
|
||||||
|
- [Deps] update `call-bind`, `get-intrinsic` [`2aeb5b5`](https://github.com/ljharb/call-bound/commit/2aeb5b521dc2b2683d1345c753ea1161de2d1c14)
|
||||||
|
- [types] improve return type [`1a0c9fe`](https://github.com/ljharb/call-bound/commit/1a0c9fe3114471e7ca1f57d104e2efe713bb4871)
|
||||||
|
|
||||||
|
## v1.0.1 - 2024-12-05
|
||||||
|
|
||||||
|
### Commits
|
||||||
|
|
||||||
|
- Initial implementation, tests, readme, types [`6d94121`](https://github.com/ljharb/call-bound/commit/6d94121a9243602e506334069f7a03189fe3363d)
|
||||||
|
- Initial commit [`0eae867`](https://github.com/ljharb/call-bound/commit/0eae867334ea025c33e6e91cdecfc9df96680cf9)
|
||||||
|
- npm init [`71b2479`](https://github.com/ljharb/call-bound/commit/71b2479c6723e0b7d91a6b663613067e98b7b275)
|
||||||
|
- Only apps should have lockfiles [`c3754a9`](https://github.com/ljharb/call-bound/commit/c3754a949b7f9132b47e2d18c1729889736741eb)
|
||||||
|
- [actions] skip `npm ls` in node < 10 [`74275a5`](https://github.com/ljharb/call-bound/commit/74275a5186b8caf6309b6b97472bdcb0df4683a8)
|
||||||
|
- [Dev Deps] add missing peer dep [`1354de8`](https://github.com/ljharb/call-bound/commit/1354de8679413e4ae9c523d85f76fa7a5e032d97)
|
||||||
+21
@@ -0,0 +1,21 @@
|
|||||||
|
MIT License
|
||||||
|
|
||||||
|
Copyright (c) 2024 Jordan Harband
|
||||||
|
|
||||||
|
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||||
|
of this software and associated documentation files (the "Software"), to deal
|
||||||
|
in the Software without restriction, including without limitation the rights
|
||||||
|
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||||
|
copies of the Software, and to permit persons to whom the Software is
|
||||||
|
furnished to do so, subject to the following conditions:
|
||||||
|
|
||||||
|
The above copyright notice and this permission notice shall be included in all
|
||||||
|
copies or substantial portions of the Software.
|
||||||
|
|
||||||
|
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||||
|
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||||
|
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||||
|
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||||
|
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||||
|
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||||
|
SOFTWARE.
|
||||||
+53
@@ -0,0 +1,53 @@
|
|||||||
|
# call-bound <sup>[![Version Badge][npm-version-svg]][package-url]</sup>
|
||||||
|
|
||||||
|
[![github actions][actions-image]][actions-url]
|
||||||
|
[![coverage][codecov-image]][codecov-url]
|
||||||
|
[![dependency status][deps-svg]][deps-url]
|
||||||
|
[![dev dependency status][dev-deps-svg]][dev-deps-url]
|
||||||
|
[![License][license-image]][license-url]
|
||||||
|
[![Downloads][downloads-image]][downloads-url]
|
||||||
|
|
||||||
|
[![npm badge][npm-badge-png]][package-url]
|
||||||
|
|
||||||
|
Robust call-bound JavaScript intrinsics, using `call-bind` and `get-intrinsic`.
|
||||||
|
|
||||||
|
## Getting started
|
||||||
|
|
||||||
|
```sh
|
||||||
|
npm install --save call-bound
|
||||||
|
```
|
||||||
|
|
||||||
|
## Usage/Examples
|
||||||
|
|
||||||
|
```js
|
||||||
|
const assert = require('assert');
|
||||||
|
const callBound = require('call-bound');
|
||||||
|
|
||||||
|
const slice = callBound('Array.prototype.slice');
|
||||||
|
|
||||||
|
delete Function.prototype.call;
|
||||||
|
delete Function.prototype.bind;
|
||||||
|
delete Array.prototype.slice;
|
||||||
|
|
||||||
|
assert.deepEqual(slice([1, 2, 3, 4], 1, -1), [2, 3]);
|
||||||
|
```
|
||||||
|
|
||||||
|
## Tests
|
||||||
|
|
||||||
|
Clone the repo, `npm install`, and run `npm test`
|
||||||
|
|
||||||
|
[package-url]: https://npmjs.org/package/call-bound
|
||||||
|
[npm-version-svg]: https://versionbadg.es/ljharb/call-bound.svg
|
||||||
|
[deps-svg]: https://david-dm.org/ljharb/call-bound.svg
|
||||||
|
[deps-url]: https://david-dm.org/ljharb/call-bound
|
||||||
|
[dev-deps-svg]: https://david-dm.org/ljharb/call-bound/dev-status.svg
|
||||||
|
[dev-deps-url]: https://david-dm.org/ljharb/call-bound#info=devDependencies
|
||||||
|
[npm-badge-png]: https://nodei.co/npm/call-bound.png?downloads=true&stars=true
|
||||||
|
[license-image]: https://img.shields.io/npm/l/call-bound.svg
|
||||||
|
[license-url]: LICENSE
|
||||||
|
[downloads-image]: https://img.shields.io/npm/dm/call-bound.svg
|
||||||
|
[downloads-url]: https://npm-stat.com/charts.html?package=call-bound
|
||||||
|
[codecov-image]: https://codecov.io/gh/ljharb/call-bound/branch/main/graphs/badge.svg
|
||||||
|
[codecov-url]: https://app.codecov.io/gh/ljharb/call-bound/
|
||||||
|
[actions-image]: https://img.shields.io/endpoint?url=https://github-actions-badge-u3jn4tfpocch.runkit.sh/ljharb/call-bound
|
||||||
|
[actions-url]: https://github.com/ljharb/call-bound/actions
|
||||||
+94
@@ -0,0 +1,94 @@
|
|||||||
|
type Intrinsic = typeof globalThis;
|
||||||
|
|
||||||
|
type IntrinsicName = keyof Intrinsic | `%${keyof Intrinsic}%`;
|
||||||
|
|
||||||
|
type IntrinsicPath = IntrinsicName | `${StripPercents<IntrinsicName>}.${string}` | `%${StripPercents<IntrinsicName>}.${string}%`;
|
||||||
|
|
||||||
|
type AllowMissing = boolean;
|
||||||
|
|
||||||
|
type StripPercents<T extends string> = T extends `%${infer U}%` ? U : T;
|
||||||
|
|
||||||
|
type BindMethodPrecise<F> =
|
||||||
|
F extends (this: infer This, ...args: infer Args) => infer R
|
||||||
|
? (obj: This, ...args: Args) => R
|
||||||
|
: F extends {
|
||||||
|
(this: infer This1, ...args: infer Args1): infer R1;
|
||||||
|
(this: infer This2, ...args: infer Args2): infer R2
|
||||||
|
}
|
||||||
|
? {
|
||||||
|
(obj: This1, ...args: Args1): R1;
|
||||||
|
(obj: This2, ...args: Args2): R2
|
||||||
|
}
|
||||||
|
: never
|
||||||
|
|
||||||
|
// Extract method type from a prototype
|
||||||
|
type GetPrototypeMethod<T extends keyof typeof globalThis, M extends string> =
|
||||||
|
(typeof globalThis)[T] extends { prototype: any }
|
||||||
|
? M extends keyof (typeof globalThis)[T]['prototype']
|
||||||
|
? (typeof globalThis)[T]['prototype'][M]
|
||||||
|
: never
|
||||||
|
: never
|
||||||
|
|
||||||
|
// Get static property/method
|
||||||
|
type GetStaticMember<T extends keyof typeof globalThis, P extends string> =
|
||||||
|
P extends keyof (typeof globalThis)[T] ? (typeof globalThis)[T][P] : never
|
||||||
|
|
||||||
|
// Type that maps string path to actual bound function or value with better precision
|
||||||
|
type BoundIntrinsic<S extends string> =
|
||||||
|
S extends `${infer Obj}.prototype.${infer Method}`
|
||||||
|
? Obj extends keyof typeof globalThis
|
||||||
|
? BindMethodPrecise<GetPrototypeMethod<Obj, Method & string>>
|
||||||
|
: unknown
|
||||||
|
: S extends `${infer Obj}.${infer Prop}`
|
||||||
|
? Obj extends keyof typeof globalThis
|
||||||
|
? GetStaticMember<Obj, Prop & string>
|
||||||
|
: unknown
|
||||||
|
: unknown
|
||||||
|
|
||||||
|
declare function arraySlice<T>(array: readonly T[], start?: number, end?: number): T[];
|
||||||
|
declare function arraySlice<T>(array: ArrayLike<T>, start?: number, end?: number): T[];
|
||||||
|
declare function arraySlice<T>(array: IArguments, start?: number, end?: number): T[];
|
||||||
|
|
||||||
|
// Special cases for methods that need explicit typing
|
||||||
|
interface SpecialCases {
|
||||||
|
'%Object.prototype.isPrototypeOf%': (thisArg: {}, obj: unknown) => boolean;
|
||||||
|
'%String.prototype.replace%': {
|
||||||
|
(str: string, searchValue: string | RegExp, replaceValue: string): string;
|
||||||
|
(str: string, searchValue: string | RegExp, replacer: (substring: string, ...args: any[]) => string): string
|
||||||
|
};
|
||||||
|
'%Object.prototype.toString%': (obj: {}) => string;
|
||||||
|
'%Object.prototype.hasOwnProperty%': (obj: {}, v: PropertyKey) => boolean;
|
||||||
|
'%Array.prototype.slice%': typeof arraySlice;
|
||||||
|
'%Array.prototype.map%': <T, U>(array: readonly T[], callbackfn: (value: T, index: number, array: readonly T[]) => U, thisArg?: any) => U[];
|
||||||
|
'%Array.prototype.filter%': <T>(array: readonly T[], predicate: (value: T, index: number, array: readonly T[]) => unknown, thisArg?: any) => T[];
|
||||||
|
'%Array.prototype.indexOf%': <T>(array: readonly T[], searchElement: T, fromIndex?: number) => number;
|
||||||
|
'%Function.prototype.apply%': <T, A extends any[], R>(fn: (...args: A) => R, thisArg: any, args: A) => R;
|
||||||
|
'%Function.prototype.call%': <T, A extends any[], R>(fn: (...args: A) => R, thisArg: any, ...args: A) => R;
|
||||||
|
'%Function.prototype.bind%': <T, A extends any[], R>(fn: (...args: A) => R, thisArg: any, ...args: A) => (...remainingArgs: A) => R;
|
||||||
|
'%Promise.prototype.then%': {
|
||||||
|
<T, R>(promise: Promise<T>, onfulfilled: (value: T) => R | PromiseLike<R>): Promise<R>;
|
||||||
|
<T, R>(promise: Promise<T>, onfulfilled: ((value: T) => R | PromiseLike<R>) | undefined | null, onrejected: (reason: any) => R | PromiseLike<R>): Promise<R>;
|
||||||
|
};
|
||||||
|
'%RegExp.prototype.test%': (regexp: RegExp, str: string) => boolean;
|
||||||
|
'%RegExp.prototype.exec%': (regexp: RegExp, str: string) => RegExpExecArray | null;
|
||||||
|
'%Error.prototype.toString%': (error: Error) => string;
|
||||||
|
'%TypeError.prototype.toString%': (error: TypeError) => string;
|
||||||
|
'%String.prototype.split%': (
|
||||||
|
obj: unknown,
|
||||||
|
splitter: string | RegExp | {
|
||||||
|
[Symbol.split](string: string, limit?: number): string[];
|
||||||
|
},
|
||||||
|
limit?: number | undefined
|
||||||
|
) => string[];
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Returns a bound function for a prototype method, or a value for a static property.
|
||||||
|
*
|
||||||
|
* @param name - The name of the intrinsic (e.g. 'Array.prototype.slice')
|
||||||
|
* @param {AllowMissing} [allowMissing] - Whether to allow missing intrinsics (default: false)
|
||||||
|
*/
|
||||||
|
declare function callBound<K extends keyof SpecialCases | StripPercents<keyof SpecialCases>, S extends IntrinsicPath>(name: K, allowMissing?: AllowMissing): SpecialCases[`%${StripPercents<K>}%`];
|
||||||
|
declare function callBound<K extends keyof SpecialCases | StripPercents<keyof SpecialCases>, S extends IntrinsicPath>(name: S, allowMissing?: AllowMissing): BoundIntrinsic<S>;
|
||||||
|
|
||||||
|
export = callBound;
|
||||||
+19
@@ -0,0 +1,19 @@
|
|||||||
|
'use strict';
|
||||||
|
|
||||||
|
var GetIntrinsic = require('get-intrinsic');
|
||||||
|
|
||||||
|
var callBindBasic = require('call-bind-apply-helpers');
|
||||||
|
|
||||||
|
/** @type {(thisArg: string, searchString: string, position?: number) => number} */
|
||||||
|
var $indexOf = callBindBasic([GetIntrinsic('%String.prototype.indexOf%')]);
|
||||||
|
|
||||||
|
/** @type {import('.')} */
|
||||||
|
module.exports = function callBoundIntrinsic(name, allowMissing) {
|
||||||
|
/* eslint no-extra-parens: 0 */
|
||||||
|
|
||||||
|
var intrinsic = /** @type {(this: unknown, ...args: unknown[]) => unknown} */ (GetIntrinsic(name, !!allowMissing));
|
||||||
|
if (typeof intrinsic === 'function' && $indexOf(name, '.prototype.') > -1) {
|
||||||
|
return callBindBasic(/** @type {const} */ ([intrinsic]));
|
||||||
|
}
|
||||||
|
return intrinsic;
|
||||||
|
};
|
||||||
+99
@@ -0,0 +1,99 @@
|
|||||||
|
{
|
||||||
|
"name": "call-bound",
|
||||||
|
"version": "1.0.4",
|
||||||
|
"description": "Robust call-bound JavaScript intrinsics, using `call-bind` and `get-intrinsic`.",
|
||||||
|
"main": "index.js",
|
||||||
|
"exports": {
|
||||||
|
".": "./index.js",
|
||||||
|
"./package.json": "./package.json"
|
||||||
|
},
|
||||||
|
"sideEffects": false,
|
||||||
|
"scripts": {
|
||||||
|
"prepack": "npmignore --auto --commentLines=auto",
|
||||||
|
"prepublish": "not-in-publish || npm run prepublishOnly",
|
||||||
|
"prepublishOnly": "safe-publish-latest",
|
||||||
|
"prelint": "evalmd README.md",
|
||||||
|
"lint": "eslint --ext=.js,.mjs .",
|
||||||
|
"postlint": "tsc -p . && attw -P",
|
||||||
|
"pretest": "npm run lint",
|
||||||
|
"tests-only": "nyc tape 'test/**/*.js'",
|
||||||
|
"test": "npm run tests-only",
|
||||||
|
"posttest": "npx npm@'>=10.2' audit --production",
|
||||||
|
"version": "auto-changelog && git add CHANGELOG.md",
|
||||||
|
"postversion": "auto-changelog && git add CHANGELOG.md && git commit --no-edit --amend && git tag -f \"v$(node -e \"console.log(require('./package.json').version)\")\""
|
||||||
|
},
|
||||||
|
"repository": {
|
||||||
|
"type": "git",
|
||||||
|
"url": "git+https://github.com/ljharb/call-bound.git"
|
||||||
|
},
|
||||||
|
"keywords": [
|
||||||
|
"javascript",
|
||||||
|
"ecmascript",
|
||||||
|
"es",
|
||||||
|
"js",
|
||||||
|
"callbind",
|
||||||
|
"callbound",
|
||||||
|
"call",
|
||||||
|
"bind",
|
||||||
|
"bound",
|
||||||
|
"call-bind",
|
||||||
|
"call-bound",
|
||||||
|
"function",
|
||||||
|
"es-abstract"
|
||||||
|
],
|
||||||
|
"author": "Jordan Harband <ljharb@gmail.com>",
|
||||||
|
"funding": {
|
||||||
|
"url": "https://github.com/sponsors/ljharb"
|
||||||
|
},
|
||||||
|
"license": "MIT",
|
||||||
|
"bugs": {
|
||||||
|
"url": "https://github.com/ljharb/call-bound/issues"
|
||||||
|
},
|
||||||
|
"homepage": "https://github.com/ljharb/call-bound#readme",
|
||||||
|
"dependencies": {
|
||||||
|
"call-bind-apply-helpers": "^1.0.2",
|
||||||
|
"get-intrinsic": "^1.3.0"
|
||||||
|
},
|
||||||
|
"devDependencies": {
|
||||||
|
"@arethetypeswrong/cli": "^0.17.4",
|
||||||
|
"@ljharb/eslint-config": "^21.1.1",
|
||||||
|
"@ljharb/tsconfig": "^0.3.0",
|
||||||
|
"@types/call-bind": "^1.0.5",
|
||||||
|
"@types/get-intrinsic": "^1.2.3",
|
||||||
|
"@types/tape": "^5.8.1",
|
||||||
|
"auto-changelog": "^2.5.0",
|
||||||
|
"encoding": "^0.1.13",
|
||||||
|
"es-value-fixtures": "^1.7.1",
|
||||||
|
"eslint": "=8.8.0",
|
||||||
|
"evalmd": "^0.0.19",
|
||||||
|
"for-each": "^0.3.5",
|
||||||
|
"gopd": "^1.2.0",
|
||||||
|
"has-strict-mode": "^1.1.0",
|
||||||
|
"in-publish": "^2.0.1",
|
||||||
|
"npmignore": "^0.3.1",
|
||||||
|
"nyc": "^10.3.2",
|
||||||
|
"object-inspect": "^1.13.4",
|
||||||
|
"safe-publish-latest": "^2.0.0",
|
||||||
|
"tape": "^5.9.0",
|
||||||
|
"typescript": "next"
|
||||||
|
},
|
||||||
|
"testling": {
|
||||||
|
"files": "test/index.js"
|
||||||
|
},
|
||||||
|
"auto-changelog": {
|
||||||
|
"output": "CHANGELOG.md",
|
||||||
|
"template": "keepachangelog",
|
||||||
|
"unreleased": false,
|
||||||
|
"commitLimit": false,
|
||||||
|
"backfillLimit": false,
|
||||||
|
"hideCredit": true
|
||||||
|
},
|
||||||
|
"publishConfig": {
|
||||||
|
"ignore": [
|
||||||
|
".github/workflows"
|
||||||
|
]
|
||||||
|
},
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.4"
|
||||||
|
}
|
||||||
|
}
|
||||||
+61
@@ -0,0 +1,61 @@
|
|||||||
|
'use strict';
|
||||||
|
|
||||||
|
var test = require('tape');
|
||||||
|
|
||||||
|
var callBound = require('../');
|
||||||
|
|
||||||
|
/** @template {true} T @template U @typedef {T extends U ? T : never} AssertType */
|
||||||
|
|
||||||
|
test('callBound', function (t) {
|
||||||
|
// static primitive
|
||||||
|
t.equal(callBound('Array.length'), Array.length, 'Array.length yields itself');
|
||||||
|
t.equal(callBound('%Array.length%'), Array.length, '%Array.length% yields itself');
|
||||||
|
|
||||||
|
// static non-function object
|
||||||
|
t.equal(callBound('Array.prototype'), Array.prototype, 'Array.prototype yields itself');
|
||||||
|
t.equal(callBound('%Array.prototype%'), Array.prototype, '%Array.prototype% yields itself');
|
||||||
|
t.equal(callBound('Array.constructor'), Array.constructor, 'Array.constructor yields itself');
|
||||||
|
t.equal(callBound('%Array.constructor%'), Array.constructor, '%Array.constructor% yields itself');
|
||||||
|
|
||||||
|
// static function
|
||||||
|
t.equal(callBound('Date.parse'), Date.parse, 'Date.parse yields itself');
|
||||||
|
t.equal(callBound('%Date.parse%'), Date.parse, '%Date.parse% yields itself');
|
||||||
|
|
||||||
|
// prototype primitive
|
||||||
|
t.equal(callBound('Error.prototype.message'), Error.prototype.message, 'Error.prototype.message yields itself');
|
||||||
|
t.equal(callBound('%Error.prototype.message%'), Error.prototype.message, '%Error.prototype.message% yields itself');
|
||||||
|
|
||||||
|
var x = callBound('Object.prototype.toString');
|
||||||
|
var y = callBound('%Object.prototype.toString%');
|
||||||
|
|
||||||
|
// prototype function
|
||||||
|
t.notEqual(x, Object.prototype.toString, 'Object.prototype.toString does not yield itself');
|
||||||
|
t.notEqual(y, Object.prototype.toString, '%Object.prototype.toString% does not yield itself');
|
||||||
|
t.equal(x(true), Object.prototype.toString.call(true), 'call-bound Object.prototype.toString calls into the original');
|
||||||
|
t.equal(y(true), Object.prototype.toString.call(true), 'call-bound %Object.prototype.toString% calls into the original');
|
||||||
|
|
||||||
|
t['throws'](
|
||||||
|
// @ts-expect-error
|
||||||
|
function () { callBound('does not exist'); },
|
||||||
|
SyntaxError,
|
||||||
|
'nonexistent intrinsic throws'
|
||||||
|
);
|
||||||
|
t['throws'](
|
||||||
|
// @ts-expect-error
|
||||||
|
function () { callBound('does not exist', true); },
|
||||||
|
SyntaxError,
|
||||||
|
'allowMissing arg still throws for unknown intrinsic'
|
||||||
|
);
|
||||||
|
|
||||||
|
t.test('real but absent intrinsic', { skip: typeof WeakRef !== 'undefined' }, function (st) {
|
||||||
|
st['throws'](
|
||||||
|
function () { callBound('WeakRef'); },
|
||||||
|
TypeError,
|
||||||
|
'real but absent intrinsic throws'
|
||||||
|
);
|
||||||
|
st.equal(callBound('WeakRef', true), undefined, 'allowMissing arg avoids exception');
|
||||||
|
st.end();
|
||||||
|
});
|
||||||
|
|
||||||
|
t.end();
|
||||||
|
});
|
||||||
+10
@@ -0,0 +1,10 @@
|
|||||||
|
{
|
||||||
|
"extends": "@ljharb/tsconfig",
|
||||||
|
"compilerOptions": {
|
||||||
|
"target": "ESNext",
|
||||||
|
"lib": ["es2024"],
|
||||||
|
},
|
||||||
|
"exclude": [
|
||||||
|
"coverage",
|
||||||
|
],
|
||||||
|
}
|
||||||
+66
@@ -0,0 +1,66 @@
|
|||||||
|
1.0.0 / 2024-08-31
|
||||||
|
==================
|
||||||
|
|
||||||
|
* drop node <18
|
||||||
|
* allow utf8 as alias for utf-8
|
||||||
|
|
||||||
|
0.5.4 / 2021-12-10
|
||||||
|
==================
|
||||||
|
|
||||||
|
* deps: safe-buffer@5.2.1
|
||||||
|
|
||||||
|
0.5.3 / 2018-12-17
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Use `safe-buffer` for improved Buffer API
|
||||||
|
|
||||||
|
0.5.2 / 2016-12-08
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Fix `parse` to accept any linear whitespace character
|
||||||
|
|
||||||
|
0.5.1 / 2016-01-17
|
||||||
|
==================
|
||||||
|
|
||||||
|
* perf: enable strict mode
|
||||||
|
|
||||||
|
0.5.0 / 2014-10-11
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Add `parse` function
|
||||||
|
|
||||||
|
0.4.0 / 2014-09-21
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Expand non-Unicode `filename` to the full ISO-8859-1 charset
|
||||||
|
|
||||||
|
0.3.0 / 2014-09-20
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Add `fallback` option
|
||||||
|
* Add `type` option
|
||||||
|
|
||||||
|
0.2.0 / 2014-09-19
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Reduce ambiguity of file names with hex escape in buggy browsers
|
||||||
|
|
||||||
|
0.1.2 / 2014-09-19
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Fix periodic invalid Unicode filename header
|
||||||
|
|
||||||
|
0.1.1 / 2014-09-19
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Fix invalid characters appearing in `filename*` parameter
|
||||||
|
|
||||||
|
0.1.0 / 2014-09-18
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Make the `filename` argument optional
|
||||||
|
|
||||||
|
0.0.0 / 2014-09-18
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Initial release
|
||||||
+22
@@ -0,0 +1,22 @@
|
|||||||
|
(The MIT License)
|
||||||
|
|
||||||
|
Copyright (c) 2014-2017 Douglas Christopher Wilson
|
||||||
|
|
||||||
|
Permission is hereby granted, free of charge, to any person obtaining
|
||||||
|
a copy of this software and associated documentation files (the
|
||||||
|
'Software'), to deal in the Software without restriction, including
|
||||||
|
without limitation the rights to use, copy, modify, merge, publish,
|
||||||
|
distribute, sublicense, and/or sell copies of the Software, and to
|
||||||
|
permit persons to whom the Software is furnished to do so, subject to
|
||||||
|
the following conditions:
|
||||||
|
|
||||||
|
The above copyright notice and this permission notice shall be
|
||||||
|
included in all copies or substantial portions of the Software.
|
||||||
|
|
||||||
|
THE SOFTWARE IS PROVIDED 'AS IS', WITHOUT WARRANTY OF ANY KIND,
|
||||||
|
EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF
|
||||||
|
MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT.
|
||||||
|
IN NO EVENT SHALL THE AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY
|
||||||
|
CLAIM, DAMAGES OR OTHER LIABILITY, WHETHER IN AN ACTION OF CONTRACT,
|
||||||
|
TORT OR OTHERWISE, ARISING FROM, OUT OF OR IN CONNECTION WITH THE
|
||||||
|
SOFTWARE OR THE USE OR OTHER DEALINGS IN THE SOFTWARE.
|
||||||
+142
@@ -0,0 +1,142 @@
|
|||||||
|
# content-disposition
|
||||||
|
|
||||||
|
[![NPM Version][npm-image]][npm-url]
|
||||||
|
[![NPM Downloads][downloads-image]][downloads-url]
|
||||||
|
[![Node.js Version][node-version-image]][node-version-url]
|
||||||
|
[![Build Status][github-actions-ci-image]][github-actions-ci-url]
|
||||||
|
[![Test Coverage][coveralls-image]][coveralls-url]
|
||||||
|
|
||||||
|
Create and parse HTTP `Content-Disposition` header
|
||||||
|
|
||||||
|
## Installation
|
||||||
|
|
||||||
|
```sh
|
||||||
|
$ npm install content-disposition
|
||||||
|
```
|
||||||
|
|
||||||
|
## API
|
||||||
|
|
||||||
|
```js
|
||||||
|
var contentDisposition = require('content-disposition')
|
||||||
|
```
|
||||||
|
|
||||||
|
### contentDisposition(filename, options)
|
||||||
|
|
||||||
|
Create an attachment `Content-Disposition` header value using the given file name,
|
||||||
|
if supplied. The `filename` is optional and if no file name is desired, but you
|
||||||
|
want to specify `options`, set `filename` to `undefined`.
|
||||||
|
|
||||||
|
```js
|
||||||
|
res.setHeader('Content-Disposition', contentDisposition('∫ maths.pdf'))
|
||||||
|
```
|
||||||
|
|
||||||
|
**note** HTTP headers are of the ISO-8859-1 character set. If you are writing this
|
||||||
|
header through a means different from `setHeader` in Node.js, you'll want to specify
|
||||||
|
the `'binary'` encoding in Node.js.
|
||||||
|
|
||||||
|
#### Options
|
||||||
|
|
||||||
|
`contentDisposition` accepts these properties in the options object.
|
||||||
|
|
||||||
|
##### fallback
|
||||||
|
|
||||||
|
If the `filename` option is outside ISO-8859-1, then the file name is actually
|
||||||
|
stored in a supplemental field for clients that support Unicode file names and
|
||||||
|
a ISO-8859-1 version of the file name is automatically generated.
|
||||||
|
|
||||||
|
This specifies the ISO-8859-1 file name to override the automatic generation or
|
||||||
|
disables the generation all together, defaults to `true`.
|
||||||
|
|
||||||
|
- A string will specify the ISO-8859-1 file name to use in place of automatic
|
||||||
|
generation.
|
||||||
|
- `false` will disable including a ISO-8859-1 file name and only include the
|
||||||
|
Unicode version (unless the file name is already ISO-8859-1).
|
||||||
|
- `true` will enable automatic generation if the file name is outside ISO-8859-1.
|
||||||
|
|
||||||
|
If the `filename` option is ISO-8859-1 and this option is specified and has a
|
||||||
|
different value, then the `filename` option is encoded in the extended field
|
||||||
|
and this set as the fallback field, even though they are both ISO-8859-1.
|
||||||
|
|
||||||
|
##### type
|
||||||
|
|
||||||
|
Specifies the disposition type, defaults to `"attachment"`. This can also be
|
||||||
|
`"inline"`, or any other value (all values except inline are treated like
|
||||||
|
`attachment`, but can convey additional information if both parties agree to
|
||||||
|
it). The type is normalized to lower-case.
|
||||||
|
|
||||||
|
### contentDisposition.parse(string)
|
||||||
|
|
||||||
|
```js
|
||||||
|
var disposition = contentDisposition.parse('attachment; filename="EURO rates.txt"; filename*=UTF-8\'\'%e2%82%ac%20rates.txt')
|
||||||
|
```
|
||||||
|
|
||||||
|
Parse a `Content-Disposition` header string. This automatically handles extended
|
||||||
|
("Unicode") parameters by decoding them and providing them under the standard
|
||||||
|
parameter name. This will return an object with the following properties (examples
|
||||||
|
are shown for the string `'attachment; filename="EURO rates.txt"; filename*=UTF-8\'\'%e2%82%ac%20rates.txt'`):
|
||||||
|
|
||||||
|
- `type`: The disposition type (always lower case). Example: `'attachment'`
|
||||||
|
|
||||||
|
- `parameters`: An object of the parameters in the disposition (name of parameter
|
||||||
|
always lower case and extended versions replace non-extended versions). Example:
|
||||||
|
`{filename: "€ rates.txt"}`
|
||||||
|
|
||||||
|
## Examples
|
||||||
|
|
||||||
|
### Send a file for download
|
||||||
|
|
||||||
|
```js
|
||||||
|
var contentDisposition = require('content-disposition')
|
||||||
|
var destroy = require('destroy')
|
||||||
|
var fs = require('fs')
|
||||||
|
var http = require('http')
|
||||||
|
var onFinished = require('on-finished')
|
||||||
|
|
||||||
|
var filePath = '/path/to/public/plans.pdf'
|
||||||
|
|
||||||
|
http.createServer(function onRequest (req, res) {
|
||||||
|
// set headers
|
||||||
|
res.setHeader('Content-Type', 'application/pdf')
|
||||||
|
res.setHeader('Content-Disposition', contentDisposition(filePath))
|
||||||
|
|
||||||
|
// send file
|
||||||
|
var stream = fs.createReadStream(filePath)
|
||||||
|
stream.pipe(res)
|
||||||
|
onFinished(res, function () {
|
||||||
|
destroy(stream)
|
||||||
|
})
|
||||||
|
})
|
||||||
|
```
|
||||||
|
|
||||||
|
## Testing
|
||||||
|
|
||||||
|
```sh
|
||||||
|
$ npm test
|
||||||
|
```
|
||||||
|
|
||||||
|
## References
|
||||||
|
|
||||||
|
- [RFC 2616: Hypertext Transfer Protocol -- HTTP/1.1][rfc-2616]
|
||||||
|
- [RFC 5987: Character Set and Language Encoding for Hypertext Transfer Protocol (HTTP) Header Field Parameters][rfc-5987]
|
||||||
|
- [RFC 6266: Use of the Content-Disposition Header Field in the Hypertext Transfer Protocol (HTTP)][rfc-6266]
|
||||||
|
- [Test Cases for HTTP Content-Disposition header field (RFC 6266) and the Encodings defined in RFCs 2047, 2231 and 5987][tc-2231]
|
||||||
|
|
||||||
|
[rfc-2616]: https://tools.ietf.org/html/rfc2616
|
||||||
|
[rfc-5987]: https://tools.ietf.org/html/rfc5987
|
||||||
|
[rfc-6266]: https://tools.ietf.org/html/rfc6266
|
||||||
|
[tc-2231]: http://greenbytes.de/tech/tc2231/
|
||||||
|
|
||||||
|
## License
|
||||||
|
|
||||||
|
[MIT](LICENSE)
|
||||||
|
|
||||||
|
[npm-image]: https://img.shields.io/npm/v/content-disposition.svg
|
||||||
|
[npm-url]: https://npmjs.org/package/content-disposition
|
||||||
|
[node-version-image]: https://img.shields.io/node/v/content-disposition.svg
|
||||||
|
[node-version-url]: https://nodejs.org/en/download
|
||||||
|
[coveralls-image]: https://img.shields.io/coveralls/jshttp/content-disposition.svg
|
||||||
|
[coveralls-url]: https://coveralls.io/r/jshttp/content-disposition?branch=master
|
||||||
|
[downloads-image]: https://img.shields.io/npm/dm/content-disposition.svg
|
||||||
|
[downloads-url]: https://npmjs.org/package/content-disposition
|
||||||
|
[github-actions-ci-image]: https://img.shields.io/github/workflow/status/jshttp/content-disposition/ci/master?label=ci
|
||||||
|
[github-actions-ci-url]: https://github.com/jshttp/content-disposition?query=workflow%3Aci
|
||||||
+459
@@ -0,0 +1,459 @@
|
|||||||
|
/*!
|
||||||
|
* content-disposition
|
||||||
|
* Copyright(c) 2014-2017 Douglas Christopher Wilson
|
||||||
|
* MIT Licensed
|
||||||
|
*/
|
||||||
|
|
||||||
|
'use strict'
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module exports.
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
module.exports = contentDisposition
|
||||||
|
module.exports.parse = parse
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Module dependencies.
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
var basename = require('path').basename
|
||||||
|
var Buffer = require('safe-buffer').Buffer
|
||||||
|
|
||||||
|
/**
|
||||||
|
* RegExp to match non attr-char, *after* encodeURIComponent (i.e. not including "%")
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
var ENCODE_URL_ATTR_CHAR_REGEXP = /[\x00-\x20"'()*,/:;<=>?@[\\\]{}\x7f]/g // eslint-disable-line no-control-regex
|
||||||
|
|
||||||
|
/**
|
||||||
|
* RegExp to match percent encoding escape.
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
var HEX_ESCAPE_REGEXP = /%[0-9A-Fa-f]{2}/
|
||||||
|
var HEX_ESCAPE_REPLACE_REGEXP = /%([0-9A-Fa-f]{2})/g
|
||||||
|
|
||||||
|
/**
|
||||||
|
* RegExp to match non-latin1 characters.
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
var NON_LATIN1_REGEXP = /[^\x20-\x7e\xa0-\xff]/g
|
||||||
|
|
||||||
|
/**
|
||||||
|
* RegExp to match quoted-pair in RFC 2616
|
||||||
|
*
|
||||||
|
* quoted-pair = "\" CHAR
|
||||||
|
* CHAR = <any US-ASCII character (octets 0 - 127)>
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
var QESC_REGEXP = /\\([\u0000-\u007f])/g // eslint-disable-line no-control-regex
|
||||||
|
|
||||||
|
/**
|
||||||
|
* RegExp to match chars that must be quoted-pair in RFC 2616
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
var QUOTE_REGEXP = /([\\"])/g
|
||||||
|
|
||||||
|
/**
|
||||||
|
* RegExp for various RFC 2616 grammar
|
||||||
|
*
|
||||||
|
* parameter = token "=" ( token | quoted-string )
|
||||||
|
* token = 1*<any CHAR except CTLs or separators>
|
||||||
|
* separators = "(" | ")" | "<" | ">" | "@"
|
||||||
|
* | "," | ";" | ":" | "\" | <">
|
||||||
|
* | "/" | "[" | "]" | "?" | "="
|
||||||
|
* | "{" | "}" | SP | HT
|
||||||
|
* quoted-string = ( <"> *(qdtext | quoted-pair ) <"> )
|
||||||
|
* qdtext = <any TEXT except <">>
|
||||||
|
* quoted-pair = "\" CHAR
|
||||||
|
* CHAR = <any US-ASCII character (octets 0 - 127)>
|
||||||
|
* TEXT = <any OCTET except CTLs, but including LWS>
|
||||||
|
* LWS = [CRLF] 1*( SP | HT )
|
||||||
|
* CRLF = CR LF
|
||||||
|
* CR = <US-ASCII CR, carriage return (13)>
|
||||||
|
* LF = <US-ASCII LF, linefeed (10)>
|
||||||
|
* SP = <US-ASCII SP, space (32)>
|
||||||
|
* HT = <US-ASCII HT, horizontal-tab (9)>
|
||||||
|
* CTL = <any US-ASCII control character (octets 0 - 31) and DEL (127)>
|
||||||
|
* OCTET = <any 8-bit sequence of data>
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
var PARAM_REGEXP = /;[\x09\x20]*([!#$%&'*+.0-9A-Z^_`a-z|~-]+)[\x09\x20]*=[\x09\x20]*("(?:[\x20!\x23-\x5b\x5d-\x7e\x80-\xff]|\\[\x20-\x7e])*"|[!#$%&'*+.0-9A-Z^_`a-z|~-]+)[\x09\x20]*/g // eslint-disable-line no-control-regex
|
||||||
|
var TEXT_REGEXP = /^[\x20-\x7e\x80-\xff]+$/
|
||||||
|
var TOKEN_REGEXP = /^[!#$%&'*+.0-9A-Z^_`a-z|~-]+$/
|
||||||
|
|
||||||
|
/**
|
||||||
|
* RegExp for various RFC 5987 grammar
|
||||||
|
*
|
||||||
|
* ext-value = charset "'" [ language ] "'" value-chars
|
||||||
|
* charset = "UTF-8" / "ISO-8859-1" / mime-charset
|
||||||
|
* mime-charset = 1*mime-charsetc
|
||||||
|
* mime-charsetc = ALPHA / DIGIT
|
||||||
|
* / "!" / "#" / "$" / "%" / "&"
|
||||||
|
* / "+" / "-" / "^" / "_" / "`"
|
||||||
|
* / "{" / "}" / "~"
|
||||||
|
* language = ( 2*3ALPHA [ extlang ] )
|
||||||
|
* / 4ALPHA
|
||||||
|
* / 5*8ALPHA
|
||||||
|
* extlang = *3( "-" 3ALPHA )
|
||||||
|
* value-chars = *( pct-encoded / attr-char )
|
||||||
|
* pct-encoded = "%" HEXDIG HEXDIG
|
||||||
|
* attr-char = ALPHA / DIGIT
|
||||||
|
* / "!" / "#" / "$" / "&" / "+" / "-" / "."
|
||||||
|
* / "^" / "_" / "`" / "|" / "~"
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
var EXT_VALUE_REGEXP = /^([A-Za-z0-9!#$%&+\-^_`{}~]+)'(?:[A-Za-z]{2,3}(?:-[A-Za-z]{3}){0,3}|[A-Za-z]{4,8}|)'((?:%[0-9A-Fa-f]{2}|[A-Za-z0-9!#$&+.^_`|~-])+)$/
|
||||||
|
|
||||||
|
/**
|
||||||
|
* RegExp for various RFC 6266 grammar
|
||||||
|
*
|
||||||
|
* disposition-type = "inline" | "attachment" | disp-ext-type
|
||||||
|
* disp-ext-type = token
|
||||||
|
* disposition-parm = filename-parm | disp-ext-parm
|
||||||
|
* filename-parm = "filename" "=" value
|
||||||
|
* | "filename*" "=" ext-value
|
||||||
|
* disp-ext-parm = token "=" value
|
||||||
|
* | ext-token "=" ext-value
|
||||||
|
* ext-token = <the characters in token, followed by "*">
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
var DISPOSITION_TYPE_REGEXP = /^([!#$%&'*+.0-9A-Z^_`a-z|~-]+)[\x09\x20]*(?:$|;)/ // eslint-disable-line no-control-regex
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Create an attachment Content-Disposition header.
|
||||||
|
*
|
||||||
|
* @param {string} [filename]
|
||||||
|
* @param {object} [options]
|
||||||
|
* @param {string} [options.type=attachment]
|
||||||
|
* @param {string|boolean} [options.fallback=true]
|
||||||
|
* @return {string}
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
function contentDisposition (filename, options) {
|
||||||
|
var opts = options || {}
|
||||||
|
|
||||||
|
// get type
|
||||||
|
var type = opts.type || 'attachment'
|
||||||
|
|
||||||
|
// get parameters
|
||||||
|
var params = createparams(filename, opts.fallback)
|
||||||
|
|
||||||
|
// format into string
|
||||||
|
return format(new ContentDisposition(type, params))
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Create parameters object from filename and fallback.
|
||||||
|
*
|
||||||
|
* @param {string} [filename]
|
||||||
|
* @param {string|boolean} [fallback=true]
|
||||||
|
* @return {object}
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
function createparams (filename, fallback) {
|
||||||
|
if (filename === undefined) {
|
||||||
|
return
|
||||||
|
}
|
||||||
|
|
||||||
|
var params = {}
|
||||||
|
|
||||||
|
if (typeof filename !== 'string') {
|
||||||
|
throw new TypeError('filename must be a string')
|
||||||
|
}
|
||||||
|
|
||||||
|
// fallback defaults to true
|
||||||
|
if (fallback === undefined) {
|
||||||
|
fallback = true
|
||||||
|
}
|
||||||
|
|
||||||
|
if (typeof fallback !== 'string' && typeof fallback !== 'boolean') {
|
||||||
|
throw new TypeError('fallback must be a string or boolean')
|
||||||
|
}
|
||||||
|
|
||||||
|
if (typeof fallback === 'string' && NON_LATIN1_REGEXP.test(fallback)) {
|
||||||
|
throw new TypeError('fallback must be ISO-8859-1 string')
|
||||||
|
}
|
||||||
|
|
||||||
|
// restrict to file base name
|
||||||
|
var name = basename(filename)
|
||||||
|
|
||||||
|
// determine if name is suitable for quoted string
|
||||||
|
var isQuotedString = TEXT_REGEXP.test(name)
|
||||||
|
|
||||||
|
// generate fallback name
|
||||||
|
var fallbackName = typeof fallback !== 'string'
|
||||||
|
? fallback && getlatin1(name)
|
||||||
|
: basename(fallback)
|
||||||
|
var hasFallback = typeof fallbackName === 'string' && fallbackName !== name
|
||||||
|
|
||||||
|
// set extended filename parameter
|
||||||
|
if (hasFallback || !isQuotedString || HEX_ESCAPE_REGEXP.test(name)) {
|
||||||
|
params['filename*'] = name
|
||||||
|
}
|
||||||
|
|
||||||
|
// set filename parameter
|
||||||
|
if (isQuotedString || hasFallback) {
|
||||||
|
params.filename = hasFallback
|
||||||
|
? fallbackName
|
||||||
|
: name
|
||||||
|
}
|
||||||
|
|
||||||
|
return params
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Format object to Content-Disposition header.
|
||||||
|
*
|
||||||
|
* @param {object} obj
|
||||||
|
* @param {string} obj.type
|
||||||
|
* @param {object} [obj.parameters]
|
||||||
|
* @return {string}
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
function format (obj) {
|
||||||
|
var parameters = obj.parameters
|
||||||
|
var type = obj.type
|
||||||
|
|
||||||
|
if (!type || typeof type !== 'string' || !TOKEN_REGEXP.test(type)) {
|
||||||
|
throw new TypeError('invalid type')
|
||||||
|
}
|
||||||
|
|
||||||
|
// start with normalized type
|
||||||
|
var string = String(type).toLowerCase()
|
||||||
|
|
||||||
|
// append parameters
|
||||||
|
if (parameters && typeof parameters === 'object') {
|
||||||
|
var param
|
||||||
|
var params = Object.keys(parameters).sort()
|
||||||
|
|
||||||
|
for (var i = 0; i < params.length; i++) {
|
||||||
|
param = params[i]
|
||||||
|
|
||||||
|
var val = param.slice(-1) === '*'
|
||||||
|
? ustring(parameters[param])
|
||||||
|
: qstring(parameters[param])
|
||||||
|
|
||||||
|
string += '; ' + param + '=' + val
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
return string
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Decode a RFC 5987 field value (gracefully).
|
||||||
|
*
|
||||||
|
* @param {string} str
|
||||||
|
* @return {string}
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
function decodefield (str) {
|
||||||
|
var match = EXT_VALUE_REGEXP.exec(str)
|
||||||
|
|
||||||
|
if (!match) {
|
||||||
|
throw new TypeError('invalid extended field value')
|
||||||
|
}
|
||||||
|
|
||||||
|
var charset = match[1].toLowerCase()
|
||||||
|
var encoded = match[2]
|
||||||
|
var value
|
||||||
|
|
||||||
|
// to binary string
|
||||||
|
var binary = encoded.replace(HEX_ESCAPE_REPLACE_REGEXP, pdecode)
|
||||||
|
|
||||||
|
switch (charset) {
|
||||||
|
case 'iso-8859-1':
|
||||||
|
value = getlatin1(binary)
|
||||||
|
break
|
||||||
|
case 'utf-8':
|
||||||
|
case 'utf8':
|
||||||
|
value = Buffer.from(binary, 'binary').toString('utf8')
|
||||||
|
break
|
||||||
|
default:
|
||||||
|
throw new TypeError('unsupported charset in extended field')
|
||||||
|
}
|
||||||
|
|
||||||
|
return value
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Get ISO-8859-1 version of string.
|
||||||
|
*
|
||||||
|
* @param {string} val
|
||||||
|
* @return {string}
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
function getlatin1 (val) {
|
||||||
|
// simple Unicode -> ISO-8859-1 transformation
|
||||||
|
return String(val).replace(NON_LATIN1_REGEXP, '?')
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Parse Content-Disposition header string.
|
||||||
|
*
|
||||||
|
* @param {string} string
|
||||||
|
* @return {object}
|
||||||
|
* @public
|
||||||
|
*/
|
||||||
|
|
||||||
|
function parse (string) {
|
||||||
|
if (!string || typeof string !== 'string') {
|
||||||
|
throw new TypeError('argument string is required')
|
||||||
|
}
|
||||||
|
|
||||||
|
var match = DISPOSITION_TYPE_REGEXP.exec(string)
|
||||||
|
|
||||||
|
if (!match) {
|
||||||
|
throw new TypeError('invalid type format')
|
||||||
|
}
|
||||||
|
|
||||||
|
// normalize type
|
||||||
|
var index = match[0].length
|
||||||
|
var type = match[1].toLowerCase()
|
||||||
|
|
||||||
|
var key
|
||||||
|
var names = []
|
||||||
|
var params = {}
|
||||||
|
var value
|
||||||
|
|
||||||
|
// calculate index to start at
|
||||||
|
index = PARAM_REGEXP.lastIndex = match[0].slice(-1) === ';'
|
||||||
|
? index - 1
|
||||||
|
: index
|
||||||
|
|
||||||
|
// match parameters
|
||||||
|
while ((match = PARAM_REGEXP.exec(string))) {
|
||||||
|
if (match.index !== index) {
|
||||||
|
throw new TypeError('invalid parameter format')
|
||||||
|
}
|
||||||
|
|
||||||
|
index += match[0].length
|
||||||
|
key = match[1].toLowerCase()
|
||||||
|
value = match[2]
|
||||||
|
|
||||||
|
if (names.indexOf(key) !== -1) {
|
||||||
|
throw new TypeError('invalid duplicate parameter')
|
||||||
|
}
|
||||||
|
|
||||||
|
names.push(key)
|
||||||
|
|
||||||
|
if (key.indexOf('*') + 1 === key.length) {
|
||||||
|
// decode extended value
|
||||||
|
key = key.slice(0, -1)
|
||||||
|
value = decodefield(value)
|
||||||
|
|
||||||
|
// overwrite existing value
|
||||||
|
params[key] = value
|
||||||
|
continue
|
||||||
|
}
|
||||||
|
|
||||||
|
if (typeof params[key] === 'string') {
|
||||||
|
continue
|
||||||
|
}
|
||||||
|
|
||||||
|
if (value[0] === '"') {
|
||||||
|
// remove quotes and escapes
|
||||||
|
value = value
|
||||||
|
.slice(1, -1)
|
||||||
|
.replace(QESC_REGEXP, '$1')
|
||||||
|
}
|
||||||
|
|
||||||
|
params[key] = value
|
||||||
|
}
|
||||||
|
|
||||||
|
if (index !== -1 && index !== string.length) {
|
||||||
|
throw new TypeError('invalid parameter format')
|
||||||
|
}
|
||||||
|
|
||||||
|
return new ContentDisposition(type, params)
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Percent decode a single character.
|
||||||
|
*
|
||||||
|
* @param {string} str
|
||||||
|
* @param {string} hex
|
||||||
|
* @return {string}
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
function pdecode (str, hex) {
|
||||||
|
return String.fromCharCode(parseInt(hex, 16))
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Percent encode a single character.
|
||||||
|
*
|
||||||
|
* @param {string} char
|
||||||
|
* @return {string}
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
function pencode (char) {
|
||||||
|
return '%' + String(char)
|
||||||
|
.charCodeAt(0)
|
||||||
|
.toString(16)
|
||||||
|
.toUpperCase()
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Quote a string for HTTP.
|
||||||
|
*
|
||||||
|
* @param {string} val
|
||||||
|
* @return {string}
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
function qstring (val) {
|
||||||
|
var str = String(val)
|
||||||
|
|
||||||
|
return '"' + str.replace(QUOTE_REGEXP, '\\$1') + '"'
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Encode a Unicode string for HTTP (RFC 5987).
|
||||||
|
*
|
||||||
|
* @param {string} val
|
||||||
|
* @return {string}
|
||||||
|
* @private
|
||||||
|
*/
|
||||||
|
|
||||||
|
function ustring (val) {
|
||||||
|
var str = String(val)
|
||||||
|
|
||||||
|
// percent encode as UTF-8
|
||||||
|
var encoded = encodeURIComponent(str)
|
||||||
|
.replace(ENCODE_URL_ATTR_CHAR_REGEXP, pencode)
|
||||||
|
|
||||||
|
return 'UTF-8\'\'' + encoded
|
||||||
|
}
|
||||||
|
|
||||||
|
/**
|
||||||
|
* Class for parsed Content-Disposition header for v8 optimization
|
||||||
|
*
|
||||||
|
* @public
|
||||||
|
* @param {string} type
|
||||||
|
* @param {object} parameters
|
||||||
|
* @constructor
|
||||||
|
*/
|
||||||
|
|
||||||
|
function ContentDisposition (type, parameters) {
|
||||||
|
this.type = type
|
||||||
|
this.parameters = parameters
|
||||||
|
}
|
||||||
+44
@@ -0,0 +1,44 @@
|
|||||||
|
{
|
||||||
|
"name": "content-disposition",
|
||||||
|
"description": "Create and parse Content-Disposition header",
|
||||||
|
"version": "1.0.0",
|
||||||
|
"author": "Douglas Christopher Wilson <doug@somethingdoug.com>",
|
||||||
|
"license": "MIT",
|
||||||
|
"keywords": [
|
||||||
|
"content-disposition",
|
||||||
|
"http",
|
||||||
|
"rfc6266",
|
||||||
|
"res"
|
||||||
|
],
|
||||||
|
"repository": "jshttp/content-disposition",
|
||||||
|
"dependencies": {
|
||||||
|
"safe-buffer": "5.2.1"
|
||||||
|
},
|
||||||
|
"devDependencies": {
|
||||||
|
"deep-equal": "1.0.1",
|
||||||
|
"eslint": "7.32.0",
|
||||||
|
"eslint-config-standard": "13.0.1",
|
||||||
|
"eslint-plugin-import": "2.25.3",
|
||||||
|
"eslint-plugin-markdown": "2.2.1",
|
||||||
|
"eslint-plugin-node": "11.1.0",
|
||||||
|
"eslint-plugin-promise": "5.2.0",
|
||||||
|
"eslint-plugin-standard": "4.1.0",
|
||||||
|
"mocha": "^9.2.2",
|
||||||
|
"nyc": "15.1.0"
|
||||||
|
},
|
||||||
|
"files": [
|
||||||
|
"LICENSE",
|
||||||
|
"HISTORY.md",
|
||||||
|
"README.md",
|
||||||
|
"index.js"
|
||||||
|
],
|
||||||
|
"engines": {
|
||||||
|
"node": ">= 0.6"
|
||||||
|
},
|
||||||
|
"scripts": {
|
||||||
|
"lint": "eslint .",
|
||||||
|
"test": "mocha --reporter spec --bail --check-leaks test/",
|
||||||
|
"test-ci": "nyc --reporter=lcovonly --reporter=text npm test",
|
||||||
|
"test-cov": "nyc --reporter=html --reporter=text npm test"
|
||||||
|
}
|
||||||
|
}
|
||||||
+29
@@ -0,0 +1,29 @@
|
|||||||
|
1.0.5 / 2023-01-29
|
||||||
|
==================
|
||||||
|
|
||||||
|
* perf: skip value escaping when unnecessary
|
||||||
|
|
||||||
|
1.0.4 / 2017-09-11
|
||||||
|
==================
|
||||||
|
|
||||||
|
* perf: skip parameter parsing when no parameters
|
||||||
|
|
||||||
|
1.0.3 / 2017-09-10
|
||||||
|
==================
|
||||||
|
|
||||||
|
* perf: remove argument reassignment
|
||||||
|
|
||||||
|
1.0.2 / 2016-05-09
|
||||||
|
==================
|
||||||
|
|
||||||
|
* perf: enable strict mode
|
||||||
|
|
||||||
|
1.0.1 / 2015-02-13
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Improve missing `Content-Type` header error message
|
||||||
|
|
||||||
|
1.0.0 / 2015-02-01
|
||||||
|
==================
|
||||||
|
|
||||||
|
* Initial implementation, derived from `media-typer@0.3.0`
|
||||||
+22
@@ -0,0 +1,22 @@
|
|||||||
|
(The MIT License)
|
||||||
|
|
||||||
|
Copyright (c) 2015 Douglas Christopher Wilson
|
||||||
|
|
||||||
|
Permission is hereby granted, free of charge, to any person obtaining
|
||||||
|
a copy of this software and associated documentation files (the
|
||||||
|
'Software'), to deal in the Software without restriction, including
|
||||||
|
without limitation the rights to use, copy, modify, merge, publish,
|
||||||
|
distribute, sublicense, and/or sell copies of the Software, and to
|
||||||
|
permit persons to whom the Software is furnished to do so, subject to
|
||||||
|
the following conditions:
|
||||||
|
|
||||||
|
The above copyright notice and this permission notice shall be
|
||||||
|
included in all copies or substantial portions of the Software.
|
||||||
|
|
||||||
|
THE SOFTWARE IS PROVIDED 'AS IS', WITHOUT WARRANTY OF ANY KIND,
|
||||||
|
EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF
|
||||||
|
MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT.
|
||||||
|
IN NO EVENT SHALL THE AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY
|
||||||
|
CLAIM, DAMAGES OR OTHER LIABILITY, WHETHER IN AN ACTION OF CONTRACT,
|
||||||
|
TORT OR OTHERWISE, ARISING FROM, OUT OF OR IN CONNECTION WITH THE
|
||||||
|
SOFTWARE OR THE USE OR OTHER DEALINGS IN THE SOFTWARE.
|
||||||
Loaded 100 of 853 files, more files were not shown because too many files have changed in this diff.
Show more
Reference in new issue
Block a user